# 智能抽取
Source: https://docs.textin.com/api-reference/endpoint/extract-v3
api-reference/extract-1.0.3.openapi.yaml POST /ai/service/v3/entity_extraction
智能抽取API已更新至v3, 如需查看旧版API请[点击](https://www.textin.com/document/legacy/open_kie_vlm_engine)
快速调试:请参考[Postman调试教程](/xparse/extract-debug-postman)或[Apifox调试教程](/xparse/extract-debug-apifox)
# 文档解析
Source: https://docs.textin.com/api-reference/endpoint/parse
api-reference/parse-1.0.1.openapi.yml POST /ai/service/v1/pdf_to_markdown
上传图片/pdf/word/html/excel/ppt/txt,进行版面检测,文字识别,表格识别,版面分析等操作,并生成markdown文档及结构化数据
快速调试:请参考[Postman调试教程](/xparse/parse-debug-postman)或[Apifox调试教程](/xparse/parse-debug-apifox)
# 异步解析
Source: https://docs.textin.com/api-reference/endpoint/xparse/v1/parse-async
api-reference/parse-async-1.4.0.openapi.yaml POST /api/v1/xparse/parse/async
创建异步文档解析任务,立即返回job_id,通过job_id查询处理状态和结果。
适用于处理大文件或批量文件,避免HTTP超时限制。
# 获取异步解析结果
Source: https://docs.textin.com/api-reference/endpoint/xparse/v1/parse-async-status
api-reference/parse-async-1.4.0.openapi.yaml GET /api/v1/xparse/parse/async/{job_id}
通过job_id查询异步解析任务的处理状态和结果。
任务状态包括:
- pending: 排队中
- in_progress: 处理中
- completed: 已完成
- failed: 处理失败
# 同步解析
Source: https://docs.textin.com/api-reference/endpoint/xparse/v1/parse-sync
api-reference/parse-sync-1.4.0.openapi.yaml POST /api/v1/xparse/parse/sync
将非结构化文档(image/pdf/word/html/excel/ppt/txt等)解析为 AI 友好的结构化数据(JSON、Markdown),包含丰富的元数据(可追溯、可解释、可验证)
# API Key
Source: https://docs.textin.com/xparse/api-key
快速获取您的 x-ti-app-id 和 x-ti-secret-code
点击链接获取API Key:[TextIn工作台 - 账号与开发者信息](https://www.textin.com/console/dashboard/setting)
1. 在功能体验页面点按左下角的个人资料图标
2. 点击「账号与开发者信息」进入工作台相应页面
![AP Ikey 1 Pn]() 3. 单击“复制”图标获取您的 x-ti-app-id 和 x-ti-secret-code
![AP Ikey Jp]() # 大版本更新迁移说明
Source: https://docs.textin.com/xparse/api-migration
从旧版 pdf_to_markdown 接口平滑迁移到新版 xParse API 的完整指南
本文档帮助你从旧版 `pdf_to_markdown` 接口平滑迁移到新版 xParse API,并介绍新增的异步处理能力。
文中所有参数映射、字段名与默认值均以 TextIn 官方接口文档为准。
***
## 为什么迁移
新版 xParse API 对旧版 `pdf_to_markdown` 做了全面升级,核心优势:
标准化的 Element 模型,语义类型清晰(Title / NarrativeText / Table / Image / Formula),JSON 体积更小
统一的请求配置(config)与响应结构(schema),便于集成与迁移
支持 TextIn / GUI 多引擎,可按场景选最优或对比效果
新增异步接口,适合大文件(建议 >10 页)和批量场景,避免 HTTP 超时;支持 Webhook 回调
归一化坐标(0\~1),不再依赖 dpi 参数
行内公式、手写体、复选框(checkbox)、内嵌图片
***
## 接口变更总览
| 维度 | 旧版 | 新版 |
| ------------ | ------------------------------------- | ----------------------------------------- |
| **URL(同步)** | `/ai/service/v1/pdf_to_markdown` | `/api/v1/xparse/parse/sync` |
| **URL(异步)** | ❌ 不支持 | `/api/v1/xparse/parse/async` |
| **任务状态查询** | ❌ 不支持 | `GET /api/v1/xparse/parse/async/{job_id}` |
| **文件上传** | Body 二进制流(`application/octet-stream`) | `multipart/form-data`,字段名 `file` |
| **URL 文件方式** | Body 文本(`text/plain`) | `multipart/form-data`,字段名 `file_url` |
| **参数传入位置** | Query String | `config` JSON 字段(form-data 内) |
| **参数开关类型** | 整数 `0` / `1` | Boolean `false` / `true` |
| **响应根节点** | `result` | `data` |
| **坐标系** | 绝对像素(受 dpi 影响) | 归一化值(0\~1) |
| **页码起始** | `page_id`(起始值 1-based) | `page_number`(1-based,第一页为 1) |
***
## 入参迁移指南
### 请求方式变更
```http theme={null}
POST https://api.textin.com/ai/service/v1/pdf_to_markdown?parse_mode=auto&table_flavor=html&page_details=1
Content-Type: application/octet-stream
x-ti-app-id:
x-ti-secret-code:
[二进制文件内容]
```
```http theme={null}
POST https://api.textin.com/api/v1/xparse/parse/sync
Content-Type: multipart/form-data
x-ti-app-id:
x-ti-secret-code:
--boundary
Content-Disposition: form-data; name="file"; filename="doc.pdf"
[二进制文件内容]
--boundary
Content-Disposition: form-data; name="config"
{"capabilities":{"table_view":"html","pages":true,"title_tree":true}}
```
### 新版 config 结构总览
新版参数不再是扁平的 Query String,而是放在 form-data 的 `config` 字段里。该字段的值是一个 JSON,内部又分四个区块(注意:其中一个区块也叫 config,下文以「config 字段值 → config 区块」指代,切勿写成 `{"config":{"config":{...}}}` 之外的多层嵌套):
```json theme={null}
{
"document": { "password": "..." },
"capabilities": { "table_view": "html", "pages": true, "...": "..." },
"scope": { "page_range": "1-10" },
"config": {
"force_engine": "textin",
"engine_params": {
"parse_mode": "auto",
"formula_level": 0,
"image_output_type": "url"
}
}
}
```
| 区块 | 作用 |
| ---------------- | ----------------------------------------------- |
| **document** | 文档本身处理参数(如加密 PDF 密码) |
| **capabilities** | 解析策略与返回格式开关(决定返回哪些字段、表格格式等) |
| **scope** | 处理范围(如页码区间) |
| **config(区块)** | 引擎选择(`force_engine`)+ 引擎级自定义参数(`engine_params`) |
**关键认知**:旧版的 `parse_mode`、`formula_level` 等"引擎行为参数"在新版并未消失,而是下沉到了 `config` 区块的 `engine_params` 里。它们与 `capabilities` 里的"返回内容开关"是两个不同维度,迁移时不要混淆。(注:`dpi` 是例外,新版已彻底移除。)
### 参数字段映射表(核心)
下表已按官方文档逐项核对。「新版参数」列给出在 `config` 字段值内的相对路径(`engine_params` 即 `config` 区块下的 `engine_params`)。
| 旧版参数
(Query) | 旧默认 | 新版参数 | 新默认 | 变更说明 |
| -------------------------------------------- | -------- | ---------------------------------------------------------- | ------- | ---------------------------------------------------- |
| `pdf_pwd` | — | `document.password` | — | 仅改位置 |
| `page_start` +
`page_count` | 0 / 1000 | `scope.page_range`
(如 `"1-10"`) | — | 合并为区间字符串 |
| `apply_document_tree`
(0/1) | 1 | `capabilities.include_hierarchy` | `true` | int→bool |
| `table_flavor`
(md/html/none) | html | `capabilities.table_view`
(markdown/html) | `html` | "md" → "markdown"
"none" 已移除 |
| `get_image`
(none/page/objects/both) | none | `capabilities.include_image_data`
(是否返回) | `false` | 详见下方说明 |
| `image_output_type`
(base64str/default) | default | `engine_params.image_output_type`
(url/base64) | `url` | 取值体系不同:
旧 base64str/default
→ 新 url/base64 |
| `formula_level`
(0/1/2) | 0 | `engine_params.formula_level`
(0/1) | 0 | ⚠️ 保留在引擎参数,
取值改为 0/1 |
| `page_details`
(0/1) | 1 | `capabilities.pages` | `false` | ⚠️ 默认反转,需显式 `true` |
| `char_details`
(0/1) | 0 | `capabilities.include_char_details` | `false` | int→bool |
| `catalog_details`
(0/1) | 0 | `capabilities.title_tree` | `false` | 改名 |
| `crop_dewarp`
(0/1) | 0 | `capabilities.crop_dewarp` | `false` | int→bool |
| `remove_watermark`
(0/1) | 0 | `capabilities.remove_watermark` | `false` | int→bool |
| `parse_mode`
(auto/scan/lite/parse) | scan | `engine_params.parse_mode`
(auto/scan/parse/lite/vlm) | 见下方说明 | ✅ 保留;新增 vlm 模式 |
| `raw_ocr`
(0/1) | 0 | 近似改用
`capabilities.include_char_details` | `false` | ⚠️ 语义非完全等价 |
| `dpi`
(72/144/216) | 144 | ❌ 已移除 | — | 新版用归一化坐标,
无对应参数 |
| `get_excel` | 0 | ❌ 已移除 | — | 新版不支持 Excel 输出 |
| `markdown_details` | 1 | ❌ 已移除 | — | elements 始终返回 |
**get\_image 迁移注意**:旧版 `get_image` 有 none/page/objects/both 四档语义(整页图 / 子图 / 两者)。新版通过组合 `capabilities.pages` 和 `capabilities.include_image_data` 实现:
* 当 `pages=true` 时,`include_image_data=true/false` 对应 `get_image=both/page`
* 当 `pages=false` 时,`include_image_data=true/false` 对应 `get_image=objects/none`
图片格式由 `engine_params.image_output_type`(url/base64)控制。
* **parse\_mode 在新版的默认值**:旧版默认 `scan`;新版 parse/sync 接口默认值以官方文档为准
* **force\_engine 是新增的"引擎选择"维度**(textin/textin\_gui),不是 `parse_mode` 的替代品;在textin引擎下,`parse_mode`可同时配置
### 新增能力(仅新版支持)
| 参数 | 默认 | 说明 |
| -------------------------------------- | -------- | ------------------------------------------------- |
| `capabilities.include_inline_objects` | `false` | 返回文本内的细粒度行内对象:公式、手写、复选框、内嵌图片 |
| `capabilities.include_table_structure` | `false` | 返回表格结构化数据(行列数、单元格坐标、跨行跨列、单元格内容类型) |
| `config.force_engine` | `textin` | 指定引擎:`textin`(默认)/ `textin_gui`。各引擎适用场景与限制以官方文档为准 |
| `config.engine_params` | — | 引擎自定义参数(专家模式),不同引擎支持的参数不同 |
***
## 出参迁移指南
### 顶层结构变化
```json theme={null}
{
"code": 200,
"message": "success",
"result": { "...": "主体数据" },
"version": "v1.0",
"duration": 1234
}
```
```json theme={null}
{
"code": 200,
"message": "success",
"data": {
"schema_version": "1.3.0",
"file_id": "doc_7f3a2b",
"job_id": "job_x9k2m",
"success_count": 10,
"metadata": { "...": "文件名/类型/页数" },
"markdown": "...",
"elements": [],
"pages": [],
"title_tree": [],
"summary": {
"duration_ms": 972
}
}
}
```
### 主体数据字段映射
| 旧版 `result.*` | 新版 `data.*` | 变更说明 |
| ------------------- | ---------------------------------------------------- | ------------ |
| `markdown` | `markdown` | 不变 |
| `detail` | `elements` | 改名,结构重组(见下节) |
| `pages` | `pages` | 字段名相同,内部结构重组 |
| `catalog`(含 `toc`) | `title_tree` | 改名,结构变为节点数组 |
| `total_page_number` | `metadata.page_count` | 下沉至 metadata |
| `valid_page_number` | `success_count` | 改名 |
| `excel_base64` | ❌ 已移除 | 新版不支持 Excel |
| (无) | `schema_version` / `file_id` / `job_id` / `metadata` | 新增字段 |
### 元素结构变化(detail → elements)
旧版 `detail[]` 与新版 `elements[]` 的字段对照:
| 旧版 `detail[]` | 新版 `elements[]` | 变更说明 |
| --------------------------------- | ------------------------------------- | -------------------------------------------------------- |
| `paragraph_id`(整数) | `element_id`(字符串,如 `el_001`) | ID 类型由整数改为字符串 |
| `type`("paragraph" / "table" 等) | `type`(语义字符串) | 改为 Title / NarrativeText / Table / Image / Formula 等语义类型 |
| `text` | `text` | 不变 |
| `position`(绝对像素) | `coordinates`(归一化 0\~1) | ⚠️ 坐标系变化,需换算 |
| `page_id` | `page_number` | 页码起始位置相同(具体说明见下节) |
| `outline_level` | `metadata.category_depth` | 层级信息下沉至 metadata |
| `cells`(表格单元格) | `table_structure.cells` | 下沉至 `table_structure` 子对象 |
| `caption_id` | `metadata.ref_element_id` | 关联关系下沉至 metadata |
| `tags`
(formula/handwritten) | `objects[]`(内嵌对象) | 改为结构化的行内对象数组 |
| (无) | `metadata.parent_id` / `children_ids` | 新增:父子层级关系 |
| (无) | `image_data` | 新增:图片 URL / MIME / base64 |
| (无) | `char_details` | 新增:字符级详情 |
### 新版元素示例
```json theme={null}
{
"element_id": "el_001",
"type": "Title",
"text": "检验结果",
"page_number": 1,
"coordinates": [0.1, 0.12, 0.32, 0.12, 0.32, 0.16, 0.1, 0.16],
"metadata": {
"category_depth": 0,
"children_ids": ["el_002", "el_003"],
"is_continuation": false
}
}
```
### 坐标系与页码换算
#### 坐标换算
```python theme={null}
# 旧版:绝对像素坐标(受 dpi 影响),字段名 position
# position = [x1, y1, x2, y2, x3, y3, x4, y4] 单位:像素
# 新版:归一化坐标(范围 0~1),字段名 coordinates
# 如需换算为像素,从 data.pages[] 取该页宽高:
page_width = page["page_width"]
page_height = page["page_height"]
pixel_coords = [
(coords[i] * page_width, coords[i + 1] * page_height)
for i in range(0, 8, 2)
]
```
#### 页码说明
* **旧版**:`page_id`,1-based(第一页为 1)
* **新版**:`page_number`,1-based(第一页为 1)
两者起始值相同,均为 1-based,遍历/定位页面的逻辑可直接迁移。
归一化 `coordinates` 8 个值的点序为:左上 → 右上 → 右下 → 左下。
***
## 异步接口使用指南
旧版不支持异步。新版异步接口适合大文件(建议 >10 页)或批量处理,避免 HTTP 连接超时。
### 接口概览
| 接口 | HTTP | URL | 说明 |
| ----------- | ---- | ------------------------------------- | ---------------------- |
| **提交异步任务** | POST | `/api/v1/xparse/parse/async` | 上传文件,返回 `job_id` |
| **查询状态/结果** | GET | `/api/v1/xparse/parse/async/{job_id}` | 轮询状态,完成后含 `result_url` |
#### 任务状态枚举
| 状态 | 含义 |
| ------------- | ------------------------------------ |
| `pending` | 排队等待中 |
| `in_progress` | 处理中 |
| `completed` | 已完成(响应含 `result_url`,下载该 URL 获取完整结果) |
| `failed` | 处理失败(响应含 `message` 错误说明) |
异步提交成功仅返回 `{"data": {"job_id": "..."}}`,完整解析结果需通过 `result_url` 二次下载。`result_url` 返回的数据结构与同步接口 `data` 一致。
### 异步调用完整流程(Python)
```python theme={null}
import requests, time, json
APP_ID = "your_app_id"
SECRET = "your_secret_code"
HEADERS = {"x-ti-app-id": APP_ID, "x-ti-secret-code": SECRET}
def submit_async_job(file_path: str, config: dict = None) -> str:
"""提交异步解析任务,返回 job_id"""
url = "https://api.textin.com/api/v1/xparse/parse/async"
with open(file_path, "rb") as f:
files = {"file": (file_path, f, "application/pdf")}
data = {"config": json.dumps(config)} if config else {}
resp = requests.post(url, headers=HEADERS, files=files, data=data)
resp.raise_for_status() # 先校验 HTTP 状态
result = resp.json()
if result.get("code") != 200: # 再校验业务 code,避免 KeyError
raise RuntimeError(f"提交失败: {result.get('message')}")
return result["data"]["job_id"]
def poll_result(job_id: str, interval: int = 3, max_wait: int = 300) -> dict:
"""轮询任务状态,完成后返回完整解析结果"""
url = f"https://api.textin.com/api/v1/xparse/parse/async/{job_id}"
elapsed = 0
while elapsed < max_wait:
resp = requests.get(url, headers=HEADERS)
resp.raise_for_status()
job_data = resp.json()["data"]
status = job_data["status"]
if status == "completed":
# result_url 鉴权要求待确认,此处带 headers 以求稳妥
return requests.get(job_data["result_url"], headers=HEADERS).json()
elif status == "failed":
raise RuntimeError(f"任务失败: {job_data.get('message')}")
print(f" {status},已等待 {elapsed}s ...")
time.sleep(interval)
elapsed += interval
raise TimeoutError(f"超时({max_wait}s),job_id={job_id}")
config = {
"capabilities": {
"include_hierarchy": True,
"table_view": "html",
"include_image_data": True, # ⚠️ 默认 false,需显式开启
"pages": True, # ⚠️ 默认 false,需显式开启
"title_tree": True,
}
}
job_id = submit_async_job("large_document.pdf", config)
result = poll_result(job_id)
print(result["data"]["markdown"])
```
### Webhook 回调(推荐生产环境)
提交任务时附带 `webhook` 参数,任务完成/失败后系统主动 POST 推送,无需轮询:
```python theme={null}
# 注意:file_url 同样走 multipart/form-data 提交。
# requests 用 files= 触发 multipart;下方用 data= 会变成 urlencoded;
# 服务端通常也能解析表单字段,但若严格遵循 multipart 协议,建议统一用 files=。
fields = {
"file_url": (None, "https://your-storage.com/document.pdf"),
"webhook": (None, "https://your-server.com/callback/textin"),
"config": (None, json.dumps({"capabilities": {"table_view": "html"}})),
}
resp = requests.post(
"https://api.textin.com/api/v1/xparse/parse/async",
headers=HEADERS,
files=fields
)
resp.raise_for_status()
job_id = resp.json()["data"]["job_id"]
# 你的服务器收到的 Webhook Body(Method: POST, Content-Type: application/json):
# {
# "job_id": "xxx",
# "status": "completed",
# "result_url": "https://..."
# }
```
***
## 完整代码迁移示例
```python theme={null}
import requests
def parse_pdf_old(file_path, app_id, secret):
url = "https://api.textin.com/ai/service/v1/pdf_to_markdown"
params = {
"parse_mode": "auto",
"table_flavor": "html",
"get_image": "objects",
"page_details": 1,
"catalog_details": 1,
"apply_document_tree": 1,
}
headers = {
"x-ti-app-id": app_id,
"x-ti-secret-code": secret,
"Content-Type": "application/octet-stream",
}
with open(file_path, "rb") as f:
resp = requests.post(url, headers=headers,
params=params, data=f)
resp.raise_for_status()
data = resp.json()
if data.get("code") != 200:
raise RuntimeError(data.get("message"))
return {
"markdown": data["result"]["markdown"],
"total_pages": data["result"]["total_page_number"],
"elements": data["result"]["detail"],
"catalog": data["result"]["catalog"],
"pages": data["result"]["pages"],
}
```
```python theme={null}
import requests, json
def parse_pdf_new(file_path, app_id, secret):
url = "https://api.textin.com/api/v1/xparse/parse/sync"
config = {
"capabilities": {
"include_hierarchy": True, # 原 apply_document_tree=1
"table_view": "html", # 原 table_flavor=html
"include_image_data": True, # 原 get_image ⚠️需显式
"pages": True, # 原 page_details=1 ⚠️需显式
"title_tree": True, # 原 catalog_details=1
},
"config": {
"force_engine": "textin",
"engine_params": {"parse_mode": "auto"}, # 原 parse_mode
},
}
headers = {"x-ti-app-id": app_id, "x-ti-secret-code": secret}
with open(file_path, "rb") as f:
resp = requests.post(
url, headers=headers,
files={"file": (file_path, f, "application/pdf")},
data={"config": json.dumps(config)})
resp.raise_for_status()
data = resp.json()
if data.get("code") != 200:
raise RuntimeError(data.get("message"))
d = data["data"]
return {
"markdown": d["markdown"],
"total_pages": d["metadata"]["page_count"],
"elements": d["elements"], # type 现为字符串
"title_tree": d.get("title_tree"),
"pages": d.get("pages"),
}
```
***
## 迁移检查清单
`/ai/service/v1/pdf_to_markdown` → `/api/v1/xparse/parse/sync`
Query String + 二进制 Body → `multipart/form-data` + `config` JSON
整数开关(0/1)全部改为 boolean(false/true)
⚠️ 显式声明 `capabilities.include_image_data: true`(默认已反转)\
⚠️ 显式声明 `capabilities.pages: true`(默认已反转)
`parse_mode` / `formula_level` / `image_output_type` 迁移到 `config` 区块的 `engine_params`(非 capabilities)
评估是否需要 `force_engine` 选择特定引擎(新增能力,textin引擎下可同时配置 `parse_mode` )
* 响应根节点:`result` → `data`
* `total_page_number` → `data.metadata.page_count`
* `valid_page_number` → `data.success_count`
* `detail` → `data.elements`(`paragraph_id` → `element_id`;`type` 由 "paragraph" 等改为语义字符串)
* `catalog` → `data.title_tree`
坐标:`position`(绝对像素)→ `coordinates`(归一化,× page\_width/height 换算)
`table_flavor='md'` → `table_view='markdown'`;'none' 已移除,需调整逻辑
`image_output_type`:取值由 base64str/default 改为 url/base64
* 如用 `get_excel`:新版不支持 Excel 输出,需另寻替代
* 如用 `raw_ocr`:近似改用 `capabilities.include_char_details`(语义非完全等价,需验证)
* `dpi`:新版无对应参数,坐标改为归一化输出
所有响应在读取 `["data"]` 前先校验 HTTP 状态与业务 `code`,避免鉴权/参数错误变成 KeyError
大文件(建议 >10 页)评估迁移至异步接口
生产环境异步场景配置 Webhook 回调替代轮询
# 计费说明
Source: https://docs.textin.com/xparse/charge
您可以[在此处](https://www.textin.com/market/chager/pdf_to_markdown?cache=7919)查看定价选项及购买套餐。
## 具体使用计费规则说明
TextIn xParse智能文档解析采用「按量计费」制,计费单位为“T币/页”。在实际使用时,您可以选择[购买页数套餐](https://www.textin.com/market/chager/pdf_to_markdown?cache=7921)包,也可以直接[充值T币](https://www.textin.com/console/dashboard/userCenter/charge)使用。套餐和T币的计费规则为:
* 扣费顺序:优先消耗即将到期的套餐包,未购买套餐包则按实际使用量扣减T币余额。
* 购买套餐后,会自动开启按量计费模式;当套餐额度使用完毕后,如果未购买新套餐包,则会按实际使用量扣减T币余额,扣减T币余额时按[套餐](https://www.textin.com/market/chager/pdf_to_markdown?cache=7921)中的最高单价进行扣减。
* 可以在【[工作台-我的套餐](https://www.textin.com/console/dashboard/userCenter/package_management)】中查看套餐使用情况,可以在【[工作台-充值与消费明细](https://www.textin.com/console/dashboard/userCenter/finance)】中查看T币订单和消费情况。
TextIn xParse智能文档解析的使用方式包括:在线Web平台使用、API使用、第三方Agent平台使用。需要注意的是:[**文档解析**](https://docs.textin.com/api-reference/endpoint/parse)和[**文档抽取**](https://docs.textin.com/api-reference/endpoint/extract)是2个独立的API,其使用计费和消耗额度也是独立区分开的。
下面会为您详细介绍不同使用方式的计费说明。
### 在线Web平台使用
在Web平台使用时,可以直接在页面左下角账号信息处看到当前拥有的总额度和已消耗额度。
![Charge Web Pn]() 在平台上使用示例文件进行解析和抽取是**完全免费**的!您可以先通过示例文件快速感受效果。
同时我们为每位新注册的用户朋友**免费赠送100页**使用额度,添加TextIn福利官还可获得**免费加赠1000页**使用额度和其他超多福利!您可以自行上传文档进行解析和抽取,验证TextIn xParse智能文档解析在您实际业务场景中的表现。
当您的免费额度使用完毕后,需要[购买页数套餐](https://www.textin.com/market/chager/pdf_to_markdown?cache=7921)包或[充值T币](https://www.textin.com/console/dashboard/userCenter/charge)使用。
* 文档解析会根据您实际解析成功的文件页数进行计费扣减,解析失败的页数不计费。
* 您可以通过`page_start`和`page_count`这两个参数控制要解析的页数范围。
* 文档解析成功后,在返回的JSON结果中有`success_count`字段,即为解析成功的页数。
* 文档解析成功后,解析结果会在Web平台缓存;无论您何时重新查看解析结果,还是修改参数配置后重新解析识别,都是**限时免费**的!
在文档解析Web页面使用智能抽取功能**限时免费**!您可以充分体验,感受文档抽取能力的应用价值。
### 通过API使用
通过API使用时,仍然是根据实际解析和抽取的文件页数进行计费扣减。API请求失败不会计费。
与Web平台使用不同的是:无论何种文件,每次成功调用API进行解析或抽取后均会产生计费扣减。
您可以通过以下字段进行核验
* 文档解析:[**返回JSON结构说明**](https://docs.textin.com/xparse/parse-getjson);`success_count`字段,解析成功的页数
* 文档抽取:[**返回JSON结构说明**](https://docs.textin.com/xparse/extract-getjson);
* prompt模式抽取:`success_count`字段,智能抽取处理的页数
* 自定义字段抽取:`page_count`字段,智能抽取处理的页数
另外还需要特殊注意的是:由于文档抽取API整合了文档解析处理能力和大模型语义理解能力,会先对文档进行解析预处理再进行语义理解抽取,因此在计费上:**文档抽取API的消耗是文档解析API的2倍**。这样做是为了更好的保障文档抽取的结果准确性,以及可以提供精确的原文坐标,便于对结果做快速复核校验。
**例如一份10页的文档,对10页全部解析和抽取且均成功,那么:**
* 单独调用文档解析API时消耗页数额度为10页,单独调用文档抽取API时消耗页数额度为20页。
* 如果是T币扣减,单独使用文档解析扣减0.5T币(单价0.05T币/页),单独使用文档抽取扣减1T币。
### 第三方Agent平台使用
TextIn xParse智能文档解析在Coze、Dify等主流Agent平台上架了文档解析官方插件。
详情可见:[TextIn官方插件使用教程](https://vrk3wty1lu.feishu.cn/docx/Mhh2dJJFLoFjl2x7i2Ic7VrBnyc)
在Agent平台使用文档解析插件时,需要先前往【[**工作台 - 账号与开发者信息**](https://www.textin.com/console/dashboard/setting)】获取 `x-ti-app-id` 和 `x-ti-secret-code`;当插件运行后,会根据账号信息进行套餐页数额度和T币余额扣减。
# 最佳实践
Source: https://docs.textin.com/xparse/extract-best-practices-v3
关于如何创建高质量 JSON schema 的建议
## 概述
构造良好的 schema 可以确保抽取结果更符合预期,且便于下游使用,本文分享的最佳实践包括:
* 如何定义清晰的字段
* 使用枚举与描述
* 避免不必要的嵌套
* 聚焦于原文档中的关键信息,引导抽取引擎准确理解抽取意图和解读文档
通过应用这些实践,您可以减少抽取错误、提高输出信息完整度,并利于下游更容易接入。
## JSON schema 建议
您的抽取 schema 对输出质量起着至关重要的作用。您可以在 schema 结构、描述(description)以及类型约束上多做尝试,以取得最佳抽取效果。
**1. 使用与原文档内容高度匹配的字段名,并为每个字段提供清晰的描述。**
采用与原文档中信息呈现方式一致的字段名和描述,有助于抽取引擎更容易识别并提取正确的值。例如从表格中抽取数据,可以直接使用表头作为字段名。
**2. 如果要抽取的数据是少量有限值的集合,可以使用枚举类型约束。**
如果某个字段有可预测的一组取值(例如“是/否”或预定义的类别),使用枚举(enum)类型来约束输出并提升一致性。
```json theme={null}
"properties": {
"币种": {
"type": ["enum", "null"],
"enum": [
"USD",
"EUR",
"JPY",
"CAD",
"AUD",
"Other"
],
"description": "国际货币种类代码"
}
}
```
**3. 避免在 schema 中创造新数据,将数据处理放到下游完成。**
```python theme={null}
# 通过 schema 抽取原文档中的月消费值
"properties": {
"monthly_cost": {
"type": ["number", "null"],
"description": "服务月度消费总计"
},
}
.
.
.
# 下游计算年消费值
total_annual_price =
extract_result.json()["result"][0]["monthly_cost"] * 12
```
**4. 对于长列表使用数组类型。**
如果你需要抽取一个较长的项目列表(例如发票表格中的订单列表),请在 schema 中使用数组类型(array)。这有助于引擎完整获取列表中的每一项,避免遗漏末尾的数据。
# Apifox调试教程
Source: https://docs.textin.com/xparse/extract-debug-apifox
通过Apifox快速调试文档抽取API
## 概述
本文档将指导您如何使用Apifox导入和调试文档抽取API。文档抽取API使用JSON格式的请求体,通过定义schema来指定要抽取的字段。
## 先决条件
* 已安装Apifox([下载地址](https://apifox.com/))
* 已获取API Key(x-ti-app-id 和 x-ti-secret-code),请前往 [TextIn工作台 - 账号与开发者信息](https://www.textin.com/console/dashboard/setting) 获取
## curl命令示例
```bash theme={null}
curl -X POST 'https://api.textin.com/ai/service/v3/entity_extraction' \
--header 'x-ti-app-id: YOUR_APP_ID' \
--header 'x-ti-secret-code: YOUR_SECRET_CODE' \
--header 'Content-Type: application/json' \
--data '{
"file": {
"file_url": "https://web-api.textin.com/open/image/download?filename=54efc36a05cf475aa6b39137b0717726"
},
"schema": {
"type": "object",
"properties": {
"商品": {
"type": ["string","null"],
"description": "商品名称"
}
},
"required": ["商品"]
}
}'
```
## 导入curl命令到Apifox
### 步骤1:复制curl命令
复制上面的curl命令。
### 步骤2:打开Apifox导入功能
1. 打开Apifox应用
2. 点击左侧菜单栏的 **+** 按钮,或使用快捷键 `Ctrl+I` (Windows) / `Cmd+I` (Mac)
![点击导入按钮]() ### 步骤3:选择导入方式
1. 在弹出的导入窗口中,将复制的curl命令粘贴到文本框中
![选择cURL导入]() ### 步骤4:确认导入
1. 在预览页面确认请求信息
2. 点击 **确定** 按钮完成导入
![确认导入]() ## 配置请求
### 修改API Key
1. 点击 **Headers** 标签页
2. 找到 `x-ti-app-id` 和 `x-ti-secret-code` 两个header
3. 将 `YOUR_APP_ID` 替换为您的实际x-ti-app-id
4. 将 `YOUR_SECRET_CODE` 替换为您的实际x-ti-secret-code
![修改API Key]() ### 修改JSON Body
文档抽取API的核心是JSON schema配置。您可以根据需要修改Body中的内容:
1. 点击 **Body** 标签页
2. 确保Body类型为 **raw** 和 **JSON**
3. 修改JSON内容,主要包括:
**修改文件信息:**
```json theme={null}
{
"file": {
"file_url": "https://web-api.textin.com/open/image/download?filename=54efc36a05cf475aa6b39137b0717726"
},
...
}
```
或者使用base64编码的文件:
```json theme={null}
{
"file": {
"file_base64": "base64编码的文件内容"
},
...
}
```
**修改抽取schema:**
根据您的需求修改schema,例如抽取更多字段:
```json theme={null}
{
...
"schema": {
"type": "object",
"properties": {
"商品": {
"type": ["string","null"],
"description": "商品名称"
},
"价格": {
"type": ["number","null"],
"description": "商品价格"
},
"商品列表": {
"type": "array",
"description": "商品列表",
"items": {
"type": "object",
"properties": {
"名称": {
"type": ["string","null"],
"description": "商品名称"
},
"类型": {
"type": ["string","null"],
"description": "商品类型"
}
},
"required": ["名称", "类型"]
}
}
},
"required": ["商品", "价格", "商品列表"]
}
}
```
**添加解析选项(可选):**
```json theme={null}
{
...
"parse_options": {
"page_start": 1,
"page_count": 10,
"parse_mode": "scan",
"get_image": "objects",
"crop_dewarp": 0,
"remove_watermark": 0
}
}
```
**添加抽取选项(可选):**
```json theme={null}
{
...
"extract_options": {
"generate_citations": true,
"stamp": true
}
}
```
![修改JSON Body]() ## 发送请求
1. 确认所有配置无误后,点击右上角的 **发送** 按钮
2. 等待响应返回
3. 在下方查看响应结果
![发送请求]() ## 查看响应结果
响应结果会显示在Apifox下方的响应区域:
* **Body**:查看JSON格式的响应内容,包括:
* `extracted_schema`: 抽取的结构化数据
* `citations`: 带坐标信息的抽取结果
* `pages`: 文档页面信息
* **Headers**:查看响应头信息
* **状态码**:查看HTTP状态码(200表示成功)
响应结果如上图。
## 常见问题
### Q: 如何修改要抽取的字段?
A: 在Body标签页中修改`schema`字段,根据您的需求定义字段名称、类型和描述。详细说明请参考[文档抽取快速启动](/xparse/extract-quickstart-v3)。
### Q: 响应返回400错误?
A: 请检查JSON格式是否正确,确保schema格式符合JSON Schema规范。
### Q: 响应返回401错误?
A: 请检查API Key是否正确设置,确保x-ti-app-id和x-ti-secret-code都已正确替换。
### Q: 如何保存请求?
A: 可以将请求保存到项目中,方便后续重复使用。请求会自动保存到当前项目。
## 相关链接
* [文档抽取快速启动](/xparse/extract-quickstart-v3)
* [Postman调试教程](/xparse/extract-debug-postman)
* [API参考文档](/api-reference/endpoint/extract-v3)
# Postman调试教程
Source: https://docs.textin.com/xparse/extract-debug-postman
通过Postman快速调试文档抽取API
## 概述
本文档将指导您如何使用Postman导入和调试文档抽取API。文档抽取API使用JSON格式的请求体,通过定义schema来指定要抽取的字段。
## 先决条件
* 已安装Postman([下载地址](https://www.postman.com/downloads/))
* 已获取API Key(x-ti-app-id 和 x-ti-secret-code),请前往 [TextIn工作台 - 账号与开发者信息](https://www.textin.com/console/dashboard/setting) 获取
## curl命令示例
```bash theme={null}
curl -X POST 'https://api.textin.com/ai/service/v3/entity_extraction' \
--header 'x-ti-app-id: YOUR_APP_ID' \
--header 'x-ti-secret-code: YOUR_SECRET_CODE' \
--header 'Content-Type: application/json' \
--data '{
"file": {
"file_url": "https://web-api.textin.com/open/image/download?filename=54efc36a05cf475aa6b39137b0717726"
},
"schema": {
"type": "object",
"properties": {
"商品": {
"type": ["string","null"],
"description": "商品名称"
}
},
"required": ["商品"]
}
}'
```
## 导入curl命令到Postman
### 步骤1:复制curl命令
复制上面的curl命令。
### 步骤2:打开Postman导入功能
1. 打开Postman应用
2. 点击左上角的 **Import** 按钮
![点击Import按钮]() ### 步骤3:粘贴curl命令
1. 在弹出的导入窗口中,将复制的curl命令粘贴到文本框中
![粘贴curl命令]() ### 步骤4:确认导入
1. 在预览页面确认请求信息
2. 点击 **Import Into Collection**或者**Import Without Saving** 按钮完成导入
![确认导入]() ## 配置请求
### 修改API Key
1. 点击 **Headers** 标签页
2. 找到 `x-ti-app-id` 和 `x-ti-secret-code` 两个header
3. 将 `YOUR_APP_ID` 替换为您的实际x-ti-app-id
4. 将 `YOUR_SECRET_CODE` 替换为您的实际x-ti-secret-code
![修改API Key]() ### 修改JSON Body
文档抽取API的核心是JSON schema配置。您可以根据需要修改Body中的内容:
1. 点击 **Body** 标签页
2. 确保Body类型为 **raw** 和 **JSON**
3. 修改JSON内容,主要包括:
**修改文件信息:**
```json theme={null}
{
"file": {
"file_url": "https://web-api.textin.com/open/image/download?filename=54efc36a05cf475aa6b39137b0717726"
},
...
}
```
或者使用base64编码的文件:
```json theme={null}
{
"file": {
"file_base64": "base64编码的文件内容"
},
...
}
```
**修改抽取schema:**
根据您的需求修改schema,例如抽取更多字段:
```json theme={null}
{
...
"schema": {
"type": "object",
"properties": {
"商品": {
"type": ["string","null"],
"description": "商品名称"
},
"价格": {
"type": ["number","null"],
"description": "商品价格"
},
"商品列表": {
"type": "array",
"description": "商品列表",
"items": {
"type": "object",
"properties": {
"名称": {
"type": ["string","null"],
"description": "商品名称"
},
"类型": {
"type": ["string","null"],
"description": "商品类型"
}
},
"required": ["名称", "类型"]
}
}
},
"required": ["商品", "价格", "商品列表"]
}
}
```
**添加解析选项(可选):**
```json theme={null}
{
...
"parse_options": {
"page_start": 1,
"page_count": 10,
"parse_mode": "scan",
"get_image": "objects",
"crop_dewarp": 0,
"remove_watermark": 0
}
}
```
**添加抽取选项(可选):**
```json theme={null}
{
...
"extract_options": {
"generate_citations": true,
"stamp": true
}
}
```
![修改JSON Body]() ## 发送请求
1. 确认所有配置无误后,点击右上角的 **Send** 按钮
2. 等待响应返回
3. 在下方查看响应结果
![发送请求]() ## 查看响应结果
响应结果会显示在Postman下方的响应区域:
* **Body**:查看JSON格式的响应内容,包括:
* `extracted_schema`: 抽取的结构化数据
* `citations`: 带坐标信息的抽取结果
* `pages`: 文档页面信息
* **Headers**:查看响应头信息
* **Status**:查看HTTP状态码(200表示成功)
响应结果如上图。
## 常见问题
### Q: 如何修改要抽取的字段?
A: 在Body标签页中修改`schema`字段,根据您的需求定义字段名称、类型和描述。详细说明请参考[文档抽取快速启动](/xparse/extract-quickstart-v3)。
### Q: 响应返回400错误?
A: 请检查JSON格式是否正确,确保schema格式符合JSON Schema规范。
### Q: 响应返回401错误?
A: 请检查API Key是否正确设置,确保x-ti-app-id和x-ti-secret-code都已正确替换。
### Q: 如何保存请求?
A: 可以将请求保存到Collection中,方便后续重复使用。点击请求右侧的"Save"按钮即可。
## 相关链接
* [文档抽取快速启动](/xparse/extract-quickstart-v3)
* [Apifox调试教程](/xparse/extract-debug-apifox)
* [API参考文档](/api-reference/endpoint/extract-v3)
# 快速启动
Source: https://docs.textin.com/xparse/extract-quickstart-v3
本文档基于最新抽取API版本v3 ,如需查看旧版API(包含**Prompt模式**)或在线调试,请移步[Textin文档中心](https://www.textin.com/document/legacy/open_kie_vlm_engine)。
## 概述
TextIn xParse现已推出的全新版本的文档抽取API(v3)。在文档抽取中,您可以自定义抽取配置(JSON schema),指定您要抽取的字段名称、类型和字段描述,系统会根据您定义的配置进行抽取。
通过定义JSON schema,文档抽取兼顾了定义字段的**灵活性**和输出结果的**稳定性**。
您可以从多种样式的表单或文档中提取统一的结构化信息,并根据字段设定的标准类型完成自动格式转换。您可以根据下游系统的字段和结构要求来定义抽取JSON schema,以实现API"即插即用"的效果。例如,当您想要完成文档数据自动化录入系统时,文档抽取可以帮助您快速完成从复杂文档到系统结构化数据的无缝衔接。
新增功能
1. 支持更灵活的上传文件传参方式,兼容`file_url`和`file_base64`
2. 支持设定字段类型,包括常见的文本、数字、枚举等格式
3. 支持抽取多个表格,且限定抽取范围
4. 支持通过参数开关按需返回坐标信息,提升响应速度
## 文档抽取配置
### JSON schema 结构示例
在文档抽取中最核心的配置是JSON schema,其结构示例如下:
```json theme={null}
{
"type": "object",
"properties": {
"field_name": {
"type": ["string","null"],
"description": "Field description"
},
"table_name": {
"type": "array",
"description": "Table description",
"items": {
"type": "object",
"properties": {
"name": {
"type": ["string","null"],
"description": ""
},
"category": {
"type": ["string","null"],
"description": ""
}
},
"required": [
"name",
"category"
]
}
}
},
"required": [
"field_name",
"table_name"
]
}
```
### JSON schema 结构说明和抽取指南
我们使用[JSON Schema](https://json-schema.org/)来定义要抽取的数据结构,在遵循 schema 规范的基础上,剔除了一些不必要的字段,文档抽取使用的 schema 字段如下:
* **type**:schema的类型,最外层固定为`object`
* **properties**:抽取字段的集合
* **\**:要抽取的字段名称,由用户自定义,每个字段包含以下信息:
* **type**:要抽取的字段类型,参考[支持的字段类型](#json-schema-支持的字段类型)列表
* **description**:要抽取的字段描述
* **enum**:当type为`enum`时,该字段表示抽取字段的枚举值列表
* **items**:当type为`array`时,该字段表示要抽取的列表中的字段集合,与`properties`类似
* **required**:指定抽取必要字段,其顺序表达了抽取输出的字段顺序,仅在type为`object`时需要。
在定义要抽取的数据时,您需要为每个字段提供一个名称,以及确定该字段的类型。您还可以添加可选的字段描述为大模型提供更多的上下文,帮助文档抽取准确了解需要从文档中查找和提取哪些信息。字段名称和描述越具体、表义越明确,文档抽取就越能准确地识别和抽取文档中的正确数据。
### JSON schema 支持的字段类型
* string:字符串
* number:数字
* integer:整数
* enum:枚举
* object:对象,对象内可以包含以下类型:string、number、integer、enum。
* array:数组,数组内可以包含以下类型:string、number、integer、enum、object。
请注意,在JSON schema中array、object类型均支持层级嵌套结构,以便于抽取如表格或者具有多个属性的实体对象。目前文档抽取仅支持最多**不超过3级**的嵌套。
type可以设置为字符串(如`"type": "string"`)或者包含null的数组(如`"type": ["string", "null"]`),即使type不带null,接口底层也会默认带上null,当抽取不到数据时,接口统一返回null值。
### JSON schema 支持的字段数量
为了获得最佳性能,保障抽取的精度和速度,在JSON schema中包含的最低层级(叶子节点)字段数量限制总计应**不超过100个**。
### 更多请求体参数说明
**file**: `object` 必填,传入需要处理的文件内容
* file\_url: `string` 待处理文件的url链接,与file\_base64二选一
* file\_base64: `string` 待处理文件的base64编码,与file\_url二选一
* file\_name: `string` 文件名,可选
如果file\_base64和file\_url同时存在,优先取file\_base64的值。
**parse\_options**: `object` 用于控制文档解析输出的相关参数
* **page\_start**:当上传的是pdf时,page\_start 表示从第几页开始抽取,取值范围从1开始,不传该参数时默认从首页开始。
* **page\_count**:当上传的是pdf时,page\_count 表示要进行抽取的pdf页数。
* **parse\_mode**:文档的解析模式,默认为scan模式。
* auto 由引擎自动选择,适用范围最广
* scan 文档统一当成图片解析(如pdf每一页都当成图片解析)
* lite 轻量版,只输出表格和文字结果
* parse 仅电子档文字解析,速度最快
* vlm 视觉语言模型解析模式
* **get\_image**:获取图片,默认为objects。
* none 不返回任何图像
* page 返回每一页的整页图像:即pdf页的完整页图片
* objects 返回页面内的子图像:即pdf页内的各个子图片
* both 返回整页图像和图像对象
* **crop\_dewarp**:是否进行切边矫正预处理,默认为0,不进行切边矫正。
* 0 不进行切边矫正
* 1 进行切边矫正
* **remove\_watermark**:是否进行去水印预处理,默认为0,不去水印。
* 0 不去水印
* 1 去水印
* **formula\_level**:公式识别等级,默认为0,全识别。
* 0 行间公式和行内公式都识别
* 1 仅识别行间公式,行内公式不识别
* 2 不识别公式
* **table\_flavor**:markdown里的表格格式,默认为html,按html语法输出表格。
* md 按md语法输出表格
* html 按html语法输出表格
* none 不进行表格识别,把表格图像当成普通文字段落来识别
* **pdf\_pwd**:当pdf为加密文档时,需要提供密码。
**extract\_options**: `object` 用于控制更多抽取的高级功能
* generate\_citations `boolean` 是否生成坐标,默认为`true`
* stamp `boolean` 是否开启印章识别,默认为`true`
## 使用文档抽取 API:快速启动
推荐使用我们的[在线Web平台](https://www.textin.com/console/recognition/robot_markdown?service=pdf_to_markdown)快速创建和验证 schema 抽取效果,页面使用方式请参考[使用指南](/extract-tutorial-v3),之后您可以在[**API**](/api-reference/endpoint/extract-v3)调用中直接使用。
您也可以参考以下示例文件和示例代码,快速验证并将文档抽取接入到您的系统和应用流程中。
### 示例文件
这里为您提供了一份Textin官方示例图片,您可以点击下载使用:[文档抽取png示例.png](https://web-api.textin.com/open/image/download?filename=54efc36a05cf475aa6b39137b0717726)
![Extract Sample Image]() ### 先决条件:获取API Key
使用文档抽取API处理文档时,您需要先获取[API Key](/xparse/api-key.mdx)。请先登录后前往 [TextIn工作台 - 账号与开发者信息](https://www.textin.com/console/dashboard/setting) 获取您的x-ti-app-id 和 x-ti-secret-code。
想要快速调试API?请参考[Postman调试教程](/xparse/extract-debug-postman)或[Apifox调试教程](/xparse/extract-debug-apifox)。
### 请求示例
```python theme={null}
import requests
url = "https://api.textin.com/ai/service/v3/entity_extraction"
payload = {
# 您要抽取的文件
"file": {
"file_url": "https://web-api.textin.com/open/image/download?filename=54efc36a05cf475aa6b39137b0717726"
},
# 定义抽取的schema
"schema": {
"type": "object",
"properties": {
"商品": {
"type": ["string","null"],
"description": ""
},
"商品列表": {
"type": "array",
"description": "",
"items": {
"type": "object",
"properties": {
"名称": {
"type": ["string","null"],
"description": ""
},
"类型": {
"type": ["string","null"],
"description": ""
}
},
"required": ["名称","类型"]
}
}
},
"required": [
"商品",
"商品列表"
]
},
# 解析相关参数
"parse_options":{
"crop_dewarp":1,
"get_image":"both"
},
# 抽取高级配置
"extract_options":{
"generate_citations": True,
"stamp": True
}
}
# 设置API key
headers = {
"x-ti-app-id": "", #需替换为你的x-ti-app-id
"x-ti-secret-code": "", #需替换为你的x-ti-secret-code
"Content-Type": "application/json"
}
response = requests.post(url, json=payload, headers=headers)
print(response.json())
```
### 返回示例
```json theme={null}
{
"code": 200,
"message": "Success",
"version": "v3.0.60",
"duration": 8267,
"x_request_id": "7596b8c9d2ddbc9924b66651e9efc174",
"status": "finished",
"result": {
"success_count": 1,
"extracted_schema": {
"商品": "童装 Looney Tunes UT(短袖T恤)女装SUPIMA COTTON圆领T恤(短袖)",
"商品列表": [
{
"名称": "童装 Looney Tunes UT(短袖T恤)",
"类型": "童装"
},
{
"名称": "女装SUPIMA COTTON圆领T恤(短袖)",
"类型": "女装"
}
]
},
"citations": {
"商品": {
"value": "童装 Looney Tunes UT(短袖T恤)女装SUPIMA COTTON圆领T恤(短袖)",
"bounding_regions": [
{
"page_number": 1,
"position": [137, 599, 1129, 599, 1129, 625, 182, 625],
"text": "童装 Looney Tunes UT(短袖T恤)"
}
],
}
// 商品列表...
},
"pages": [
{
"page_number": 1,
"image_id": "62bfe3c3a8e9c9cf.jpg",
"height": 1824,
"width": 600,
"angle": 0,
"status": "Success",
"durations": 930.178466796875
}
]
}
}
```
## 返回结果说明
### 常规字段说明
* x\_request\_id:该请求的唯一标识
* code:错误码,200表示成功。详情见[错误码说明](/xparse/extract-quickstart-v3#错误码说明)
* message:错误信息,成功时为”Success”
* version:版本号,例如”v3.0.29\_20250819”
* duration:总耗时(毫秒),例如”8267”
* status:处理状态,例如"finished"
### 主要结果说明:result对象
文档抽取会在返回结果的result对象中包含以下关键信息。
**success\_count**:成功处理的文档页数。
**extracted\_schema**:结构化的抽取结果,以json格式返回,与抽取时传入的schema定义的结构一致。
**citations**:抽取结果的详细信息,包含坐标位置,结构与schema定义一致。
每个抽取字段的详细信息如下:
* **\**:在schema中定义的抽取字段名
* **value**:该字段的抽取结果
* **bounding\_regions**:抽取结果value对应的坐标位置
* **page\_number**:所在页码,从1开始
* **text**:边界框所在区域内的文本内容
* **position**:坐标位置,长度为8的数组,表示四个顶点的像素坐标 \[左上x, 左上y, 右上x, 右上y, 右下x, 右下y, 左下x, 左下y]
**stamps**:印章相关信息
* **color**:当前印章颜色,可选值有:红色、蓝色、黑色、其他
* **position**:印章的坐标信息
* **stamp\_shape**:当前印章形状,可选值有:圆章、椭圆章、方章、三角章、菱形章、其他
* **type**:当前印章类型,可选值有:公章、个人章、专用章、其他、合同专用章、财务专用章、发票专用章、业务专用章
* **value**:印章的文本内容
**pages**:文档页面相关信息
* **page\_number**:当前页码
* **image\_id**:当前页面图片id
* **height**:文档页面高度
* **width**:文档页面宽度
* **angle**:页面角度(可选值0, 90, 180, 270)
* **status**:当前页处理状态
* **durations**:当前页处理耗时(毫秒)
### 错误码说明
| **错误码** | **描述** |
| :------ | :------------------------------------------------- |
| 40101 | x-ti-app-id 或 x-ti-secret-code 为空 |
| 40102 | x-ti-app-id 或 x-ti-secret-code 无效,验证失败 |
| 40103 | 客户端IP不在白名单 |
| 40003 | 余额不足,请充值后再使用 |
| 40004 | Parameter error (参数错误,请检查入参) |
| 40007 | 机器人不存在或未发布 |
| 40008 | 机器人未开通,请至市场开通后重试 |
| 40301 | 图片类型不支持 |
| 40302 | 上传文件大小不符,文件大小不超过 50M |
| 40303 | 文件类型不支持,接口会返回实际检测到的文件类型,如“当前文件类型为.gif” |
| 40304 | 图片尺寸不符,图像宽高须介于 20 和 10000(像素)之间 |
| 40305 | File not uploaded (识别文件未上传) |
| 40306 | qps超过限制 |
| 40400 | 无效的请求链接,请检查链接是否正确 |
| 40422 | The file is corrupted (文件损坏) |
| 40423 | Password required or incorrect password (PDF密码错误) |
| 40424 | Page number out of range (页面设置超出文件范围) |
| 40425 | The input file format is not supported (输入文件格式不支持) |
| 40428 | Process office file failed (word和ppt转pdf失败或者超时) |
| 500 | Engine failed (服务器内部错误) |
| 50011 | LLM Connection Failed (访问大模型超时) |
| 50012 | LLM Engine Failed (大模型引擎错误) |
| 50207 | Partial failed (部分页面解析失败) |
## Prompt 模式
目前v3版本仅支持字段模式(JSON Schema )抽取,Prompt 模式抽取请参考[v2](https://www.textin.com/document/legacy/open_kie_vlm_engine)版本文档。
# 使用指南
Source: https://docs.textin.com/xparse/extract-tutorial-v3
为了创建一个正确可用的schema,我们提供了一个[Web配置](https://www.textin.com/console/recognition/robot_markdown?service=pdf_to_markdown\&tab=llmExtract)界面,您可以按以下步骤操作:
使用Web界面上传文件,或点击示例文件,系统会自动开始解析文件内容,为抽取做准备
使用Web界面从0开始创建一个schema。
使用配置好的schema进行抽取,验证结果是否符合您的预期。
当schema调试好后,您可以导出为json文件,以便在api调用时使用。
## 创建Schema
您可以通过我们的[Web配置](https://www.textin.com/console/recognition/robot_markdown?service=pdf_to_markdown\&tab=llmExtract)界面来创建抽取schema。
1. 登录并进入到TextIn xParse智能文档解析 [工作台](https://www.textin.com/console/recognition/robot_markdown?service=pdf_to_markdown);
2. 上传一个文件,或打开一个已存在的文件;
3. 切换到**智能抽取**tab,并切换到**字段模式**;
![Extract V3 Schema Empty Jp]() 4. 在**抽取配置**中,可以添加您想抽取的字段,如 ”商品名称“;
5. 选择**字段类型**下拉框,可以设定您所期望返回的字段类型,详情请参考[支持的字段类型](/xparse/extract-quickstart-v3#json-schema-%E6%94%AF%E6%8C%81%E7%9A%84%E5%AD%97%E6%AE%B5%E7%B1%BB%E5%9E%8B);
6. 为字段增加一个**字段描述**(可选);
7. 点击**添加字段**按钮,可以新加一个字段;
8. 鼠标 hover 时字段左侧出现小图标,可以**删除字段**和**拖拽排序**;
9. 重复以上步骤,直到添加完您想抽取的全部字段;
 10. 点击右上角**抽取**按钮,配置面板会收起,并自动切换到抽取结果面板,您可以在结果面板查看所有的内容。
## 验证抽取效果
1. 抽取完成后,会展示抽取结果面板,您可以点击字段抽取结果,会在左侧原文件区域找到对应的坐标边界(高亮显示);
![Extract V3 Schema Result Panel Jp]() 2. 抽取结果默认显示**预览**面板,您也可以切换到**JSON**面板查看对应的结构化数据;
 3. 您可以展开下方抽取配置面板,进一步调整schema后再抽取,直到抽取结果符合预期。
## 导出Schema
1. 在**抽取配置**面板,点击**导出配置**,可将当前schema对应的JSON文件下载到本地;
2. 在后续API调用时,通过该Schema,就能保证每次抽取的结果符合格式要求。
使用schema文件,可以参考以下代码示例:
```python theme={null}
import requests
import json
url = "https://api.textin.com/ai/service/v3/entity_extraction"
schema_file = '/Downloads/商铺小票.json' #您所保存的实际schema文件路径
payload = {
"file": {
"file_url": "https://web-api.textin.com/open/image/download?filename=54efc36a05cf475aa6b39137b0717726"
},
"schema":json.loads(open(schema_file).read()), #读入schema文件
"parse_options":{
"crop_dewarp":1,
"get_image":"both"
},
"extract_options":{
"generate_citations": True,
"stamp": True
}
}
headers = {
"x-ti-app-id": "", #需替换为你的x-ti-app-id
"x-ti-secret-code": "", #需替换为你的x-ti-secret-code
"Content-Type": "application/json"
}
response = requests.post(url, json=payload, headers=headers)
print(response.json())
```
## 常见抽取场景的配置方式
### 抽取单值
当待抽取的字段在文件中仅会有一个值时,推荐单值抽取,使用`string`, `number`, `integer`, `enum`类型。
![Extract V3 Mono Key Jp]() ### 抽取多值
当待抽取的字段存在多个并列的值时,推荐多值抽取,使用`array/string`,`array/number`等类型。
![Extract V3 Multi Value Jp]()
![Extract V3 Multi Value Demo Jp]() ### 抽取表格
当待抽取的内容有多组重复属性的数据组成,一般在原文档中呈现为类表格形式时,推荐表格抽取,使用`array/object`加单值字段嵌套表示。
![Extract V3 Schema Table Sample Jp]() 如果文件中存在多个表格,可以添加多个`array/object`类型的字段。
![Extract V3 Schema Multi Table Jp]() ### 抽取嵌套对象
当待抽取的内容由多个相关联的属性字段组成,推荐使用嵌套对象抽取,使用`object`类型。
![Extract V3 Object Jp]() # 产品简介
Source: https://docs.textin.com/xparse/overview
TextIn xParse for ETL
TextIn xParse智能文档解析,致力于将复杂文档转变为结构化数据,让任意文档的信息都能高效准确流入您的数据库,将非结构化内容转化为可查询、可分析的宝贵数据资产,同时兼容关系型数据库与向量数据库。
TextIn xParse智能文档解析可以从 pdf、word、excel、ppt、图片等十余种格式的非结构化文档中提取结构化数据。[文档解析](/xparse/v1/quickstart)可以识别文本、图像、表格、公式、手写体、表单字段、页眉页脚等各种元素,并支持印章、二维码、条形码等子类型,转换成 markdown 和 JSON 格式返回,同时包含精确的页面元素和坐标信息。[文档抽取](/xparse/extract-quickstart-v3)可以根据定义的规则提取特定的数据信息,支持根据prompt(自然语言)和自定义字段模式(JSON Schema)抽取。
解析或抽取后的数据是LLM友好的格式,非常适用于下游应用程序,如知识库、RAG、Agent或其他自定义工作流程。
### TextIn xParse 助力从文档到可操作的数据资产
提供全链路的文档结构化工具,最大化挖掘数据资产价值,您只需关心业务,剩下的交给TextIn
![Index 1 Pn]() ### 立即试用
免费试用,一站式极速体验解析抽取效果
灵活使用不同编程语言,支持接口高度自定义
提供可直接复制运行的命令行工具与 SDK,快速将 xParse 文档解析能力集成到开发环境中
适配 Langchain, Dify, RAGFlow 等框架
### 核心优势
* **支持任意复杂布局**:将任意版式的文档拆解为语义完整的段落,并按阅读顺序还原,更加适配大模型。
* **多元素高精度解析**:准确提取标题、公式、图表、手写体、印章、跨页段落、页眉页脚、表单字段等各种元素,同时具备行业领先的表格识别能力,轻松解决合并单元格、跨页表格、无线表格等识别难题。
* **强大的语义理解和上下文感知**:捕捉更多版面元素间的语义关系,让大模型更加读懂一份文档。
* **强大的预处理工具**:无缝集成TextIn平台中的图像处理能力,文档带水印、图片有弯曲、模糊,都能搞定。
* **高精度坐标还原**:JSON结果包含高精度的页面、元素、字符级坐标数据,方便人工复核。
* **极简、智能、灵活的语义抽取**:xParse提供prompt模式和Schema模式两种抽取规则定制,帮助您根据业务需要实现更灵活的文档信息精准提取。
* **开发者友好**:提供清晰的API文档和灵活的集成方式,支持FastGPT、Coze、CherryStudio等主流平台。
更多详情见: [TextIn xParse for ETL 产品介绍](https://www.textin.com/market/detail/xparse)
# Apifox调试教程
Source: https://docs.textin.com/xparse/parse-debug-apifox
通过Apifox快速调试文档解析API
## 概述
本文档将指导您如何使用Apifox导入和调试文档解析API。Apifox是一款功能强大的API协作工具,支持导入curl命令并快速调试API。
## 先决条件
* 已安装Apifox([下载地址](https://apifox.com/))
* 已获取API Key(x-ti-app-id 和 x-ti-secret-code),请前往 [TextIn工作台 - 账号与开发者信息](https://www.textin.com/console/dashboard/setting) 获取
## curl命令示例
### 方式一:上传本地文件
```bash theme={null}
curl -X POST 'https://api.textin.com/ai/service/v1/pdf_to_markdown?dpi=144&get_image=objects&parse_mode=auto' \
--header 'x-ti-app-id: YOUR_APP_ID' \
--header 'x-ti-secret-code: YOUR_SECRET_CODE' \
--header 'Content-Type: application/octet-stream' \
--data-binary '@your_file.pdf'
```
### 方式二:使用文件URL
```bash theme={null}
curl -X POST 'https://api.textin.com/ai/service/v1/pdf_to_markdown?dpi=144&get_image=objects&parse_mode=auto' \
--header 'x-ti-app-id: YOUR_APP_ID' \
--header 'x-ti-secret-code: YOUR_SECRET_CODE' \
--header 'Content-Type: text/plain' \
--data 'https://web-api.textin.com/open/image/download?filename=54efc36a05cf475aa6b39137b0717726'
```
## 导入curl命令到Apifox
### 步骤1:复制curl命令
复制上面的curl命令(方式一或方式二),根据您的需求选择。
### 步骤2:打开Apifox导入功能
1. 打开Apifox应用
2. 点击左侧菜单栏的 **+** 按钮,或使用快捷键 `Ctrl+I` (Windows) / `Cmd+I` (Mac)
![点击导入按钮]() ### 步骤3:选择导入方式
1. 在弹出的导入窗口中,选择 **cURL** 选项
2. 将复制的curl命令粘贴到文本框中
3. 点击 **确认** 按钮
![选择cURL导入]() ### 步骤4:确认导入
1. 在预览页面确认请求信息
2. 点击 **确定** 按钮完成导入
![确认导入]() ## 配置请求
### 重要:设置Body类型(仅方式一需要)
当导入包含`--data-binary '@file'`的curl命令时,Apifox可能会将Body类型识别为raw而不是binary。您需要手动设置Body类型为binary。
**对于方式一(本地文件上传):**
1. 在导入的请求中,点击 **Body** 标签页
2. 选择 **Binary** 类型(而不是raw)
3. 点击 **Upload** 按钮选择要上传的文件
![设置Body类型为binary]() **对于方式二(文件URL):**
Body类型会自动设置为raw,无需修改。确保Body内容为文件URL字符串。
### 修改API Key
1. 点击 **Headers** 标签页
2. 找到 `x-ti-app-id` 和 `x-ti-secret-code` 两个header
3. 将 `YOUR_APP_ID` 替换为您的实际x-ti-app-id
4. 将 `YOUR_SECRET_CODE` 替换为您的实际x-ti-secret-code
![修改API Key]() ### 修改请求参数(可选)
如果需要修改URL参数,可以:
1. 点击 **Params** 标签页查看所有参数
2. 修改参数值,例如:
* `dpi`: 144(默认值)
* `get_image`: objects(默认值)
* `parse_mode`: auto(默认值)
![修改请求参数]() ## 发送请求
1. 确认所有配置无误后,点击右上角的 **发送** 按钮
2. 等待响应返回
3. 在下方查看响应结果
![发送请求]() ## 查看响应结果
响应结果会显示在Apifox下方的响应区域:
* **Body**:查看JSON格式的响应内容
* **Headers**:查看响应头信息
* **状态码**:查看HTTP状态码(200表示成功)
响应结果如上图。
## 常见问题
### Q: 导入后Body类型不是binary怎么办?
A: 请按照上述"设置Body类型"步骤,手动将Body类型改为binary,然后选择文件。
### Q: 如何修改文件?
A: 在Body标签页选择binary类型后,点击"选择文件"按钮重新选择文件。
### Q: 响应返回401错误?
A: 请检查API Key是否正确设置,确保x-ti-app-id和x-ti-secret-code都已正确替换。
### Q: 如何保存请求?
A: 可以将请求保存到项目中,方便后续重复使用。请求会自动保存到当前项目。
## 相关链接
* [文档解析快速启动](/xparse/parse-quickstart)
* [Postman调试教程](/xparse/parse-debug-postman)
* [API参考文档](/api-reference/endpoint/parse)
# Postman调试教程
Source: https://docs.textin.com/xparse/parse-debug-postman
通过Postman快速调试文档解析API
## 概述
本文档将指导您如何使用Postman导入和调试文档解析API。Postman是一款流行的API测试工具,可以帮助您快速验证API调用。
## 先决条件
* 已安装Postman([下载地址](https://www.postman.com/downloads/))
* 已获取API Key(x-ti-app-id 和 x-ti-secret-code),请前往 [TextIn工作台 - 账号与开发者信息](https://www.textin.com/console/dashboard/setting) 获取
## curl命令示例
### 方式一:上传本地文件
```bash theme={null}
curl -X POST 'https://api.textin.com/ai/service/v1/pdf_to_markdown?dpi=144&get_image=objects&parse_mode=auto' \
--header 'x-ti-app-id: YOUR_APP_ID' \
--header 'x-ti-secret-code: YOUR_SECRET_CODE' \
--header 'Content-Type: application/octet-stream' \
--data-binary '@your_file.pdf'
```
### 方式二:使用文件URL
```bash theme={null}
curl -X POST 'https://api.textin.com/ai/service/v1/pdf_to_markdown?dpi=144&get_image=objects&parse_mode=auto' \
--header 'x-ti-app-id: YOUR_APP_ID' \
--header 'x-ti-secret-code: YOUR_SECRET_CODE' \
--header 'Content-Type: text/plain' \
--data 'https://web-api.textin.com/open/image/download?filename=54efc36a05cf475aa6b39137b0717726'
```
## 导入curl命令到Postman
### 步骤1:复制curl命令
复制上面的curl命令(方式一或方式二),根据您的需求选择。
### 步骤2:打开Postman导入功能
1. 打开Postman应用
2. 点击左上角的 **Import** 按钮
![点击Import按钮]() ### 步骤3:粘贴curl命令
1. 在弹出的导入窗口中,将复制的curl命令粘贴到文本框中
![粘贴curl命令]() ### 步骤4:确认导入
1. 在预览页面确认请求信息
2. 点击 **Import Into Collection**或者**Import Without Saving** 按钮完成导入
![确认导入]() ## 配置请求
### 重要:设置Body类型(仅方式一需要)
当导入包含`--data-binary '@file'`的curl命令时,Postman可能会将Body类型识别为raw而不是binary。您需要手动设置Body类型为binary。
**对于方式一(本地文件上传):**
1. 在导入的请求中,点击 **Body** 标签页
2. 选择 **binary** 类型(而不是raw)
3. 点击 **Select File** 按钮选择要上传的文件
![设置Body类型为binary]() **对于方式二(文件URL):**
Body类型会自动设置为raw,无需修改。确保Body内容为文件URL字符串。
### 修改API Key
1. 点击 **Headers** 标签页
2. 找到 `x-ti-app-id` 和 `x-ti-secret-code` 两个header
3. 将 `YOUR_APP_ID` 替换为您的实际x-ti-app-id
4. 将 `YOUR_SECRET_CODE` 替换为您的实际x-ti-secret-code
![修改API Key]() ### 修改请求参数(可选)
如果需要修改URL参数,可以:
1. 点击 **Params** 标签页查看所有参数
2. 修改参数值,例如:
* `dpi`: 144(默认值)
* `get_image`: objects(默认值)
* `parse_mode`: auto(默认值)
![修改请求参数]() ## 发送请求
1. 确认所有配置无误后,点击右上角的 **Send** 按钮
2. 等待响应返回
3. 在下方查看响应结果
![发送请求]() ## 查看响应结果
响应结果会显示在Postman下方的响应区域:
* **Body**:查看JSON格式的响应内容
* **Headers**:查看响应头信息
* **Status**:查看HTTP状态码(200表示成功)
响应结果如上图。
## 常见问题
### Q: 导入后Body类型不是binary怎么办?
A: 请按照上述"设置Body类型"步骤,手动将Body类型改为binary,然后选择文件。
### Q: 如何修改文件?
A: 在Body标签页选择binary类型后,点击"Select File"按钮重新选择文件。
### Q: 响应返回401错误?
A: 请检查API Key是否正确设置,确保x-ti-app-id和x-ti-secret-code都已正确替换。
### Q: 如何保存请求?
A: 可以将请求保存到Collection中,方便后续重复使用。点击请求右侧的"Save"按钮即可。
## 相关链接
* [文档解析快速启动](/xparse/parse-quickstart)
* [Apifox调试教程](/xparse/parse-debug-apifox)
* [API参考文档](/api-reference/endpoint/parse)
# 获取目录树
Source: https://docs.textin.com/xparse/parse-getcatalog
在处理长篇技术文档、学术论文或企业规范文档时,RAG系统面临的最大挑战之一是如何理解内容的逻辑层次和上下文关系。简单的文本分块往往会破坏文档的原有结构,导致检索到的信息缺乏必要的背景context。例如:当用户询问"数据安全相关的实施要求"时,如果系统无法区分这些要求是来自"总体概述"、"技术规范"还是"合规检查"章节,就可能提供不准确或不完整的信息。
实践中通常有一种技巧,即利用文档的标题层级分chunk,然后在检索和重排序的时候也利用标题层级过滤无关的chunk,从而提升Top5召回的相关度,以便让大模型在最终回答时效果更好。
在TextIn xParse文档解析API中,我们提供了获取文档标题层级的功能,最多可支持6级标题的输出,您可以基于API的返回结果来构建完整的文档目录树。
## 如何获取目录树
当您想要获取文档目录树(即大纲结构)时,您可以参考以下教程和示例代码。
这里为您提供了一份Textin官方pdf示例文件,您可点击下载或使用该链接:[文档解析pdf示例.pdf](https://web-api.textin.com/open/image/download?filename=c9cf7431eb314c7ba3f43ee716c799a3)
* 参考[快速启动](/xparse/parse-quickstart),在 options 中设置URL参数 catalog\_details=1,API会在返回结果中包含目录相关信息。
* 在main函数中添加以下示例代码,获取API输出的目录信息,并保存为 json 文件。
```python theme={null}
# 解析JSON响应
json_response = json.loads(response)
if "result" in json_response and "catalog" in json_response["result"]:
catalog = json_response["result"]["catalog"]
# 保存为json文件
with open("catalog.json", "w", encoding="utf-8") as f:
json.dump(catalog, f, ensure_ascii=False, indent=2)
print("目录已保存为 catalog.json")
else:
print("未检测到目录字段,可能文档没有目录或参数设置有误。")
return
```
* 请注意:为了更加灵活的支持下游业务场景,文档解析API的目录返回结果中通过**hierarchy**字段表示目录的标题层级,但并没有目录之间直接的父子层级关系,您可以参考以下示例代码获取标题目录间的父子层级关系,以构建目录树状结构。
```python theme={null}
toc_list = catalog['toc']
result = []
parent_stack = [] # 用于跟踪当前路径上的父节点
for item in toc_list:
# 复制当前项目,避免修改原始数据
current_item = item.copy()
current_item['children'] = []
current_level = item.get('hierarchy', 1)
# 根据层级调整父节点栈
# 移除层级大于等于当前层级的节点
while parent_stack and parent_stack[-1]['hierarchy'] >= current_level:
parent_stack.pop()
# 如果有父节点,将当前项目添加到父节点的children中
if parent_stack:
parent_stack[-1]['children'].append(current_item)
else:
# 如果没有父节点,说明是根节点
result.append(current_item)
# 将当前项目添加到父节点栈中
parent_stack.append(current_item)
print(result)
# 保存处理后的目录结构为json文件
with open("processed_catalog.json", "w", encoding="utf-8") as f:
json.dump(result, f, ensure_ascii=False, indent=2)
print("处理后的目录结构已保存为 processed_catalog.json")
return result
```
* 处理后的目录结构如下,标题目录间有了父子层级关系,您可以据此构建标题目录的树状结构。
```json expandable theme={null}
[
{
"title": "Textin",
"hierarchy": 1,
"page_id": 1,
"paragraph_id": 0,
"pos": [
276,
228,
467,
228,
467,
272,
276,
272
],
"pos_list": [
[
276,
228,
467,
228,
467,
272,
276,
272
]
],
"sub_type": "text_title",
"children": []
},
{
"pos": [
371,
382,
906,
382,
906,
450,
371,
450
],
"pos_list": [
[
371,
382,
906,
382,
906,
450,
371,
450
]
],
"sub_type": "text_title",
"title": "标准参考样例",
"hierarchy": 1,
"page_id": 1,
"paragraph_id": 2,
"children": []
},
{
"paragraph_id": 3,
"pos": [
214,
564,
974,
564,
974,
657,
214,
657
],
"pos_list": [
[
214,
564,
974,
564,
974,
657,
214,
657
]
],
"sub_type": "text_title",
"title": "本科毕业论文模板",
"hierarchy": 1,
"page_id": 1,
"children": []
},
{
"sub_type": "text_title",
"title": "目录",
"hierarchy": 1,
"page_id": 2,
"paragraph_id": 0,
"pos": [
571,
198,
685,
198,
685,
228,
571,
228
],
"pos_list": [
[
571,
198,
685,
198,
685,
228,
571,
228
]
],
"children": []
},
{
"title": "第一章 背景介绍",
"hierarchy": 1,
"page_id": 3,
"paragraph_id": 0,
"pos": [
456,
212,
733,
212,
733,
241,
456,
241
],
"pos_list": [
[
456,
212,
733,
212,
733,
241,
456,
241
]
],
"sub_type": "text_title",
"children": [
{
"page_id": 3,
"paragraph_id": 2,
"pos": [
342,
413,
657,
413,
657,
440,
342,
440
],
"pos_list": [
[
342,
413,
657,
413,
657,
440,
342,
440
]
],
"sub_type": "text_title",
"title": "第1节 模板使用说明",
"hierarchy": 2,
"children": [
{
"title": "1.1.如何使用样式?",
"hierarchy": 3,
"page_id": 3,
"paragraph_id": 5,
"pos": [
179,
798,
411,
798,
411,
820,
179,
820
],
"pos_list": [
[
179,
798,
411,
798,
411,
820,
179,
820
]
],
"sub_type": "text_title",
"children": []
}
]
},
{
"title": "第2节 如何刷新目录",
"hierarchy": 2,
"page_id": 3,
"paragraph_id": 7,
"pos": [
342,
1019,
657,
1019,
657,
1046,
342,
1046
],
"pos_list": [
[
342,
1019,
657,
1019,
657,
1046,
342,
1046
]
],
"sub_type": "text_title",
"children": [
{
"hierarchy": 3,
"page_id": 3,
"paragraph_id": 9,
"pos": [
177,
1286,
747,
1286,
747,
1308,
177,
1308
],
"pos_list": [
[
177,
1286,
747,
1286,
747,
1308,
177,
1308
]
],
"sub_type": "text_title",
"title": "2.1.为什么我写了新的章节后没有新的目录项出现?",
"children": []
},
{
"title": "2.2. 如何排版文章章节",
"hierarchy": 3,
"page_id": 4,
"paragraph_id": 1,
"pos": [
176,
221,
445,
221,
445,
243,
176,
243
],
"pos_list": [
[
176,
221,
445,
221,
445,
243,
176,
243
]
],
"sub_type": "text_title",
"children": []
},
{
"paragraph_id": 4,
"pos": [
176,
522,
423,
522,
423,
543,
176,
543
],
"pos_list": [
[
176,
522,
423,
522,
423,
543,
176,
543
]
],
"sub_type": "text_title",
"title": "2.3. 其他的一些样式",
"hierarchy": 3,
"page_id": 4,
"children": []
},
{
"sub_type": "text_title",
"title": "2.4.如何使用其他的高级功能?",
"hierarchy": 3,
"page_id": 4,
"paragraph_id": 6,
"pos": [
176,
684,
531,
684,
531,
704,
176,
704
],
"pos_list": [
[
176,
684,
531,
684,
531,
704,
176,
704
]
],
"children": []
}
]
}
]
},
{
"title": "第二章 正文要求说明",
"hierarchy": 1,
"page_id": 5,
"paragraph_id": 0,
"pos": [
422,
210,
766,
210,
766,
241,
422,
241
],
"pos_list": [
[
422,
210,
766,
210,
766,
241,
422,
241
]
],
"sub_type": "text_title",
"children": [
{
"hierarchy": 2,
"page_id": 5,
"paragraph_id": 2,
"pos": [
384,
412,
642,
412,
642,
439,
384,
439
],
"pos_list": [
[
384,
412,
642,
412,
642,
439,
384,
439
]
],
"sub_type": "text_title",
"title": "第1节 字体和大小",
"children": [
{
"hierarchy": 3,
"page_id": 5,
"paragraph_id": 3,
"pos": [
176,
496,
349,
496,
349,
518,
176,
518
],
"pos_list": [
[
176,
496,
349,
496,
349,
518,
176,
518
]
],
"sub_type": "text_title",
"title": "1.1.文章标题",
"children": []
},
{
"pos": [
176,
636,
324,
636,
324,
657,
176,
657
],
"pos_list": [
[
176,
636,
324,
636,
324,
657,
176,
657
]
],
"sub_type": "text_title",
"title": "1.2. 章标题",
"hierarchy": 3,
"page_id": 5,
"paragraph_id": 5,
"children": []
},
{
"hierarchy": 3,
"page_id": 5,
"paragraph_id": 7,
"pos": [
176,
775,
324,
775,
324,
795,
176,
795
],
"pos_list": [
[
176,
775,
324,
775,
324,
795,
176,
795
]
],
"sub_type": "text_title",
"title": "1.3. 节标题",
"children": []
},
{
"title": "1.4.子节标题",
"hierarchy": 3,
"page_id": 5,
"paragraph_id": 9,
"pos": [
176,
913,
349,
913,
349,
934,
176,
934
],
"pos_list": [
[
176,
913,
349,
913,
349,
934,
176,
934
]
],
"sub_type": "text_title",
"children": []
},
{
"title": "1.5.正文",
"hierarchy": 3,
"page_id": 5,
"paragraph_id": 11,
"pos": [
176,
1054,
300,
1054,
300,
1076,
176,
1076
],
"pos_list": [
[
176,
1054,
300,
1054,
300,
1076,
176,
1076
]
],
"sub_type": "text_title",
"children": []
}
]
}
]
},
{
"title": "第三章 公式排版",
"hierarchy": 1,
"page_id": 6,
"paragraph_id": 0,
"pos": [
457,
211,
733,
211,
733,
241,
457,
241
],
"pos_list": [
[
457,
211,
733,
211,
733,
241,
457,
241
]
],
"sub_type": "text_title",
"children": [
{
"hierarchy": 2,
"page_id": 6,
"paragraph_id": 2,
"pos": [
297,
412,
731,
412,
731,
441,
297,
441
],
"pos_list": [
[
297,
412,
731,
412,
731,
441,
297,
441
]
],
"sub_type": "text_title",
"title": "第1节 Microsoft Equation Editor",
"children": []
},
{
"page_id": 6,
"paragraph_id": 4,
"pos": [
366,
641,
637,
641,
637,
669,
366,
669
],
"pos_list": [
[
366,
641,
637,
641,
637,
669,
366,
669
]
],
"sub_type": "text_title",
"title": "第2节 MathType",
"hierarchy": 2,
"children": []
}
]
},
{
"pos_list": [
[
359,
163,
644,
163,
644,
189,
359,
189
]
],
"sub_type": "text_title",
"title": "第3节 TeX/LaTeX",
"hierarchy": 1,
"page_id": 7,
"paragraph_id": 0,
"pos": [
359,
163,
644,
163,
644,
189,
359,
189
],
"children": []
},
{
"pos": [
442,
210,
750,
210,
750,
241,
442,
241
],
"pos_list": [
[
442,
210,
750,
210,
750,
241,
442,
241
]
],
"sub_type": "text_title",
"title": "第四章 图形和表格",
"hierarchy": 1,
"page_id": 8,
"paragraph_id": 0,
"children": [
{
"pos": [
428,
350,
602,
350,
602,
376,
428,
376
],
"pos_list": [
[
428,
350,
602,
350,
602,
376,
428,
376
]
],
"sub_type": "text_title",
"title": "第1节 图形",
"hierarchy": 2,
"page_id": 8,
"paragraph_id": 1,
"children": [
{
"sub_type": "image_title",
"title": "图表1.1这是一幅牛的图片",
"hierarchy": 3,
"page_id": 8,
"paragraph_id": 4,
"pos": [
471,
847,
719,
847,
719,
865,
471,
865
],
"pos_list": [
[
471,
847,
719,
847,
719,
865,
471,
865
]
],
"children": []
}
]
},
{
"pos": [
401,
1087,
602,
1087,
602,
1114,
401,
1114
],
"pos_list": [
[
401,
1087,
602,
1087,
602,
1114,
401,
1114
]
],
"sub_type": "text_title",
"title": "第2节 表格",
"hierarchy": 2,
"page_id": 8,
"paragraph_id": 6,
"children": [
{
"sub_type": "table_title",
"title": "插入表格与图片类似。当然,可以使用Excel预先作一个表格,然后导入进来,但是word本身也可以胜任一部分简单表格的绘制,如:",
"hierarchy": 3,
"page_id": 8,
"paragraph_id": 8,
"pos": [
179,
1167,
1011,
1167,
1011,
1231,
179,
1231
],
"pos_list": [
[
179,
1167,
1011,
1167,
1011,
1231,
179,
1231
]
],
"children": []
},
{
"hierarchy": 3,
"page_id": 8,
"paragraph_id": 10,
"pos": [
479,
1372,
713,
1372,
713,
1391,
479,
1391
],
"pos_list": [
[
479,
1372,
713,
1372,
713,
1391,
479,
1391
]
],
"sub_type": "table_title",
"title": "表格2.1一个简单的表格",
"children": []
}
]
}
]
},
{
"sub_type": "text_title",
"title": "第五章 定理环境",
"hierarchy": 1,
"page_id": 9,
"paragraph_id": 0,
"pos": [
456,
208,
734,
208,
734,
242,
456,
242
],
"pos_list": [
[
456,
208,
734,
208,
734,
242,
456,
242
]
],
"children": [
{
"pos_list": [
[
357,
452,
673,
452,
673,
478,
357,
478
]
],
"sub_type": "text_title",
"title": "第1节 自定义定理环境",
"hierarchy": 2,
"page_id": 9,
"paragraph_id": 2,
"pos": [
357,
452,
673,
452,
673,
478,
357,
478
],
"children": [
{
"page_id": 9,
"paragraph_id": 4,
"pos": [
176,
581,
411,
581,
411,
603,
176,
603
],
"pos_list": [
[
176,
581,
411,
581,
411,
603,
176,
603
]
],
"sub_type": "text_title",
"title": "定理1.1.对顶角相等。",
"hierarchy": 3,
"children": []
},
{
"hierarchy": 3,
"page_id": 9,
"paragraph_id": 6,
"pos": [
176,
683,
581,
683,
581,
706,
176,
706
],
"pos_list": [
[
176,
683,
581,
683,
581,
706,
176,
706
]
],
"sub_type": "text_title",
"title": "定理1.2.三边对应相等的三角形全等。",
"children": []
}
]
},
{
"page_id": 9,
"paragraph_id": 9,
"pos": [
371,
925,
631,
925,
631,
951,
371,
951
],
"pos_list": [
[
371,
925,
631,
925,
631,
951,
371,
951
]
],
"sub_type": "text_title",
"title": "第2节 已有环境",
"hierarchy": 2,
"children": []
},
{
"pos_list": [
[
357,
1255,
645,
1255,
645,
1282,
357,
1282
]
],
"sub_type": "text_title",
"title": "第3节 自定义环境",
"hierarchy": 2,
"page_id": 9,
"paragraph_id": 14,
"pos": [
357,
1255,
645,
1255,
645,
1282,
357,
1282
],
"children": []
}
]
}
]
```
# 获取图片并持久化
Source: https://docs.textin.com/xparse/parse-getimage
TextIn xParse为了保护您的数据隐私安全,从文档解析API返回的图片链接有效期为30天,30天后平台会自动删除图片资源。如果您想要获取图片保存到本地并使markdown中的图片链接持久化,以便您在下游诸如知识库问答等AI应用中长期稳定地为用户展示图片,有以下两种方法供您选择:
1. 设置URL参数[image-output-type](https://docs.textin.com/api-reference/endpoint/parse#parameter-image-output-type)为base64str,此时图片直接以base64格式在API结果中返回。(这种方式返回结果体积会很大,长文档不推荐)
2. 设置URL参数[image-output-type](https://docs.textin.com/api-reference/endpoint/parse#parameter-image-output-type)为default(不传时默认为该值),此时图片直接以TextIn平台的链接方式返回,您可以通过链接下载图片到本地,或上传到您的云存储。
## 如何将markdown中的图片链接替换为本地图片链接
**您可以参考如下教程:使用上述方法2让API返回图片链接,并完成markdown中的图片链接替换。**
这里为您提供了一份Textin官方pdf示例文件,您可点击下载或使用该链接:[文档解析pdf示例.pdf](https://web-api.textin.com/open/image/download?filename=c9cf7431eb314c7ba3f43ee716c799a3)
* 参考[快速启动](/xparse/parse-quickstart),在 options 中设置参数 get\_image 为 objects 或 both,让API返回页面内的图片对象;设置参数 image\_output\_type 为 default,API会返回图片URL。如下图:
![Parse Image Ori Pn]() * 参考如下示例代码:提取返回结果markdown中的图片URL将图片下载保存至本地,并将markdown中的图片链接替换为本地图片链接。
```python theme={null}
import os
import re
import requests
import hashlib
from urllib.parse import urlparse
from pathlib import Path
import time
from typing import List, Tuple, Optional
class ImageDownloader:
def __init__(self, md_file: str, images_dir: str = "images"):
"""
初始化图片下载器
Args:
md_file: markdown文件路径
images_dir: 图片存储目录
"""
self.md_file = md_file
self.images_dir = images_dir
self.session = requests.Session()
self.session.headers.update({
'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36'
})
# 创建图片目录
Path(self.images_dir).mkdir(exist_ok=True)
def extract_image_urls(self, content: str) -> List[Tuple[str, str]]:
"""
提取markdown内容中的图片链接
Args:
content: markdown文件内容
Returns:
(完整的markdown语法, 图片URL) 的元组列表
"""
# 匹配  格式的markdown图片语法
pattern = r'!\[([^\]]*)\]\((https://[^\s\)]+\.(?:jpg|jpeg|png|gif|bmp|webp|svg))\)'
matches = re.findall(pattern, content, re.IGNORECASE)
# 返回完整的markdown语法和URL
result = []
for alt_text, url in matches:
full_markdown = f""
result.append((full_markdown, url))
return result
def generate_filename(self, url: str) -> str:
"""
根据URL生成本地文件名
Args:
url: 图片URL
Returns:
本地文件名
"""
# 解析URL获取文件名
parsed_url = urlparse(url)
original_filename = os.path.basename(parsed_url.path)
# 如果没有扩展名,从URL中提取
if not original_filename or '.' not in original_filename:
# 使用URL的MD5哈希作为文件名
url_hash = hashlib.md5(url.encode()).hexdigest()[:12]
original_filename = f"{url_hash}.jpg" # 默认为jpg
return original_filename
def download_image(self, url: str, max_retries: int = 3) -> Optional[str]:
"""
下载单个图片
Args:
url: 图片URL
max_retries: 最大重试次数
Returns:
成功时返回本地文件路径,失败时返回None
"""
filename = self.generate_filename(url)
local_path = os.path.join(self.images_dir, filename)
# 如果文件已存在,跳过下载
if os.path.exists(local_path):
print(f"📁 文件已存在: {local_path}")
return local_path
for attempt in range(max_retries):
try:
print(f"⬇️ 正在下载 ({attempt + 1}/{max_retries}): {url}")
response = self.session.get(url, timeout=30)
response.raise_for_status()
# 检查是否是图片文件
content_type = response.headers.get('content-type', '')
if not content_type.startswith('image/'):
print(f"⚠️ 警告: {url} 不是图片文件 (Content-Type: {content_type})")
# 保存文件
with open(local_path, 'wb') as f:
f.write(response.content)
file_size = len(response.content)
print(f"✅ 下载成功: {filename} ({file_size} bytes)")
return local_path
except requests.exceptions.RequestException as e:
print(f"❌ 下载失败 (尝试 {attempt + 1}/{max_retries}): {e}")
if attempt < max_retries - 1:
time.sleep(2) # 重试前等待2秒
else:
print(f"💀 下载彻底失败: {url}")
return None
return None
def process_markdown(self) -> bool:
"""
处理markdown文件,下载图片并替换链接
Returns:
处理是否成功
"""
try:
# 读取markdown文件
with open(self.md_file, 'r', encoding='utf-8') as f:
content = f.read()
# 备份原文件
backup_file = f"{self.md_file}.backup"
with open(backup_file, 'w', encoding='utf-8') as f:
f.write(content)
print(f"🗂️ 已创建备份文件: {backup_file}")
# 提取图片链接
image_data = self.extract_image_urls(content)
if not image_data:
print("🔍 未找到图片链接")
return True
print(f"🔍 找到 {len(image_data)} 个图片链接")
# 下载图片并替换链接
replacements = []
for i, (markdown_syntax, url) in enumerate(image_data, 1):
print(f"\n📋 处理第 {i}/{len(image_data)} 个链接:")
print(f"🔍 原始语法: {markdown_syntax}")
local_path = self.download_image(url)
if local_path:
# 使用相对路径
relative_path = os.path.relpath(local_path, os.path.dirname(self.md_file))
# 保留原始的alt text,只替换URL
alt_text = re.search(r'!\[([^\]]*)\]', markdown_syntax).group(1)
new_markdown = f""
replacements.append((markdown_syntax, new_markdown))
print(f"🔗 将替换为: {new_markdown}")
else:
print(f"⚠️ 保留原始链接: {markdown_syntax}")
# 应用替换
modified_content = content
for old_link, new_link in replacements:
modified_content = modified_content.replace(old_link, new_link)
# 保存修改后的文件
with open(self.md_file, 'w', encoding='utf-8') as f:
f.write(modified_content)
print(f"\n✅ 处理完成!")
print(f"📊 成功替换 {len(replacements)} 个链接")
print(f"📁 图片保存在: {self.images_dir}/")
print(f"📄 原文件备份: {backup_file}")
return True
except Exception as e:
print(f"❌ 处理失败: {e}")
return False
def cleanup(self):
"""清理资源"""
self.session.close()
def main():
"""主函数"""
print("🚀 图片下载器启动")
print("=" * 50)
# 配置
md_file = "test.md" # 这里替换为你的markdown文件路径
images_dir = "images" # 这里替换为你的图片存储目录
# 检查文件是否存在
if not os.path.exists(md_file):
print(f"❌ 文件不存在: {md_file}")
return
# 创建下载器并处理
downloader = ImageDownloader(md_file, images_dir)
try:
success = downloader.process_markdown()
if success:
print("\n🎉 所有操作完成!")
else:
print("\n💥 操作失败!")
finally:
downloader.cleanup()
if __name__ == "__main__":
main()
```
* 如下图:可以看到图片已经保存到本地指定目录下,打开markdown文件可以看到图片链接已经替换为本地图片链接。
![Parse Image Re Pn]() # 返回JSON结构说明
Source: https://docs.textin.com/xparse/parse-getjson
当您使用文档解析API解析文档时,解析后的数据将按照以下结构的JSON格式返回。
**重要说明:根据 `parse_mode` 参数的不同,返回结构会有所不同**:
* 当 `parse_mode` 为 `auto`、`scan`、`parse` 时,返回 `markdown`、`detail`、`pages` 等字段
* 当 `parse_mode` 为 `lite` 时,返回新的 `elements` 结构(包含 `success_count`、`elements` 数组等字段)
如需将 `elements` 格式转换为统一的`detail`/`pages`格式,请参考[转换脚本](/xparse/parse-quickstart#elements格式转换脚本)。
```json expandable theme={null}
{
"code": 200,
"message": "success",
"result": {
"markdown": "# hello markdown",
"detail": [
{
"page_id": 1,
"paragraph_id": 123,
"outline_level": -1,
"text": "hello markdown",
"position": [217,390,1336,390,1336,460,217,460],
"origin_position": [217,390,1336,390,1336,460,217,460],
"content": 0,
"type": "paragraph",
"sub_type": "catalog",
"image_url": "",
"tags": [
"formula",
"handwritten"
],
"caption_id": {
"page_id": 123,
"paragraph_id": 123
},
"cells": [
{
"row": 123,
"col": 123,
"row_span": 123,
"col_span": 123,
"position": [10,10,100,10,100,50,10,50],
"origin_position": [
123
],
"text": "",
"type": ""
}
],
"split_section_page_ids": [1,2,3],
"split_section_positions": [
[0,0,100,100,100,200,0,200],
[0,0,100,100,100,200,0,200],
[0,0,100,100,100,200,0,200]
],
"stamp": {
"value": "",
"stamp_shape": "",
"type": "",
"color": ""
}
}
],
"pages": [
{
"status": "success",
"page_id": 0,
"durations": 612.5,
"image_id": "90u12adcad08r2",
"origin_image_id": "90u12adcad08r2",
"base64": "",
"origin_base64": "",
"width": 123,
"height": 123,
"angle": 123,
"content": [
{
"id": 123,
"type": "line",
"text": "",
"angle": 0,
"pos": [
123
],
"origin_position": [
123
],
"sub_type": "handwriting",
"direction": 123,
"score": 0.5,
"char_pos": [
[
123
]
]
}
],
"raw_ocr": [
{
"text": "这是一个例子。",
"score": 0.99,
"type": "text",
"position": [10,10,100,10,100,50,10,50],
"angle": 123,
"direction": 1,
"handwritten": 1,
"char_scores": [0.99,0.98,0.95,0.95,0.99,0.93,0.87],
"char_centers": [
[20,10],
[30,10],
[40,10],
[50,10],
[60,10],
[70,10],
[80,10]
],
"char_positions": [
[
[18,8,22,8,22,12,18,12]
],
[
[28,88,32,8,32,12,28,12]
],
[
[38,88,42,8,42,12,38,12]
],
[
[48,88,52,8,52,12,48,12]
],
[
[58,88,62,8,62,12,58,12]
],
[
[68,88,72,8,72,12,68,12]
],
[
[78,88,82,8,82,12,78,12]
]
],
"char_candidates": [
["这"],
["是"],
["一","-"],
["个"],
["例"],
["子"],
["。","O"]
],
"char_candidates_score": [
[0.99],
[0.99],
[0.95,0.05],
[0.99],
[0.99],
[0.99],
[0.89,0.11]
]
}
],
"structured": [
{
"type": "textblock",
"pos": [
123
],
"origin_position": [
123
],
"content": [0,1,2],
"sub_type": "text",
"continue": true,
"next_page_id": 2,
"next_para_id": 1,
"text": "",
"outline_level": 123
}
]
}
],
"catalog": {
"toc": [
[
{
"hierarchy": 2,
"title": "1.公司简介和主要财务指标",
"page_id": 3,
"pos": [10,10,100,10,100,50,10,50]
},
{
"hierarchy": 3,
"title": "1.1 公司简介",
"page_id": 4,
"pos": [10,10,100,10,100,50,10,50]
}
]
]
},
"total_page_number": 10,
"valid_page_number": 3,
"excel_base64": "",
"success_count": 1,
"elements": [
{
"element_id": "",
"type": "NarrativeText",
"text": "xParse 是一个端到端文档处理 AI 基础设施",
"metadata": {
"page_image_url": "https://web-api.textin.com/ocr_image/external/01a91572ca81092c.jpg",
"original_image_url": "",
"angle": 0,
"page_number": 1,
"page_width": 600,
"page_height": 800,
"coordinates": [0.182212, 0.231622, 0.671733, 0.231634, 0.671754, 0.273244, 0.182266, 0.273255],
"is_continue": false,
"category_depth": -1,
"parent_id": "",
"sub_type": "stamp",
"image_url": "https://web-api.textin.com/ocr_image/external/e47f8aed69ccabce.jpg",
"image_base64": ""
}
}
]
},
"version": "2.1.0",
"duration": 999,
"metrics": [
{
"page_image_width": 1024,
"page_image_height": 768,
"dpi": 72,
"durations": 123,
"status": "",
"page_id": 123,
"angle": 90,
"image_id": ""
}
]
}
```
## 常规字段说明
* x\_request\_id:该请求的唯一标识。
* code:错误码,200表示成功。详情见[快速启动-错误码说明](/xparse/parse-quickstart)。
* message:错误信息,成功时为"success"。
* version:引擎版本号,例如"3.18.9"。
* duration:引擎耗时(毫秒),例如"999"。
## 主要结果说明:result对象
文档解析API会在返回结果的result对象中包含以下关键信息。
### markdown:正文字符串
* **markdown**:解析结果 markdown 的正文字符串。
### detail:markdown 各类型元素详细信息
detail包含markdown中不同类型元素的详细信息。受URL参数**markdown\_details**影响,默认返回detail字段,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。
* **detail**:markdown各类型元素详细信息
* **page\_id**:当前元素所在页码,例如"1"。
* **paragraph\_id**:当前元素id。
* **outline\_level**:标题级别(最多支持5级标题) -1表示正文,0表示一级标题,1表示二级标题 ...
* **text**:文本,例如"hello markdown"。
* **position**:以长度为8的整型数组表示四边形,8个数两两一组为一个点的横纵坐标,分别是左上,右上,右下,左下。 当输入是PDF时, 此坐标是基于72dpi的;当输入是图片时,此坐标是原图里的坐标。 单位:像素。例如\[217, 390, 1336, 390, 1336, 460, 217, 460]
* **origin\_position**:受URL参数**切边矫正**和**去水印**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。仅当打开切边或去水印时返回,表示该段落在原图中的坐标。格式同**position**。
* **content**:表示元素是否为正文。0 正文(段落、图片、表格);1 非正文(页眉、页脚、侧边栏)
* **type**:元素的类型。
* paragraph(段落类型,包括正文、标题、公式等文字信息)
* image(图片类型)
* table(表格类型)
* **sub\_type**:元素子类型,受**type**影响。
* 当**type**为**paragraph**时,取值范围为catalog(目录),header(页眉),footer(页脚),sidebar(侧边栏),text(正文普通文本),text\_title(文本标题),image\_title(图片标题),table\_title(表格标题);
* 当**type**是**image**时,取值范围为stamp(印章),chart(图表),qrcode(二维码),barcode(条形码);
* 当**type**为**table**时,取值范围为bordered(有线表), borderless(无线表)
* **image\_url**:图片链接,仅在**type**为**image**时返回。受URL参数**get\_image**和**image\_output\_type**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。
* 当get\_image = objects, image\_output\_type = default时,返回图片的url,图片默认保存30天;如需长久保存,请在有效期内下载图片并自行保存,可参考[获取图片并持久化](/xparse/parse-getimage);
* 或者使用image\_output\_type = base64str,图片以base64的方式返回。
* **tags**:表示段落内是否存在特殊文本,类型包括公式formula和手写体handwritten,仅在**type**为**paragraph**时返回。
* **caption\_id**:表格或图片的标题id,仅在**type**为**image**或**table**时返回。
* **page\_id**:标题所在页码。
* **paragraph\_id**:标题所在段落id。
* **cells**:单元格数组,仅在**type**为**table**时返回。
* **row**:单元格行号。
* **col**:单元格列号。
* **row\_span**:单元格行跨度,默认为1。
* **col\_span**:单元格列跨度,默认为1。
* **position**:单元格的四个角点坐标,依次为左上,右上,右下,左下。例如\[10, 10, 100, 10, 100, 50, 10, 50]
* **origin\_position**:受URL参数**切边矫正**或**去水印**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。仅当打开切边或去水印时返回,表示该单元格在原图中的坐标。格式同position。
* **text**:单元格文本内容。
* **type**:类型,固定为cell,表示单元格。
* **split\_section\_page\_ids**:当表格/段落有合并时,记录合并前各个子表格/段落所在的页的id
* **split\_section\_positions**:当表格/段落有合并时,记录合并前各个子表格/段落所在页的位置,位置所属的页码与split\_section\_page\_ids按索引一一对应,如split\_section\_positions\[2]所属的页码为split\_section\_page\_ids\[2]
* **stamp**:当sub\_type为stamp时,返回印章识别结果
* **value**:印章文本内容
* **stamp\_shape**:印章形状
* **type**:印章类型
* **color**:印章颜色
### pages:每一页的详细信息
文档按页为单位展开时, 存储每一页的详情和状态(适用于PDF),部分信息与**metrics**字段重复。受URL参数**page\_details**影响,默认返回pages,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。
* **pages**:每一页的详细信息
* **page\_id**:当前页码 (若为流式文件, 页码置为0),例如"0"。
* **status**:表示当前页的引擎输出状态,或者error\_message,例如"success"。
* **durations**:当前页总耗时(毫秒),例如"612.5"。
* **width**:文档页宽度
* **height**:文档页高度
* **angle**:图像的角度(可选值0, 90, 180, 270)
* **image\_id**:当前页图片id 。受URL参数**get\_image**和**image\_output\_type**影响,当URL参数image\_output\_type=default且get\_image=page/both时返回,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。
* 下载方式:[https://api.textin.com/ocr\_image/download?image\_id=xxx](https://api.textin.com/ocr_image/download?image_id=xxx) ,需要在headers里添加appid和key
* **origin\_image\_id**:切边或去水印前的原始页图片。受URL参数**切边矫正**或**去水印**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。仅当开启切边或去水印,image\_output\_type=default且get\_image=page/both时返回。
* 下载方式同image\_id
* **base64**:当前页图片的base64字符串,受URL参数**image\_output\_type**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。当输入参数image\_output\_type=base64str且get\_image=page/both时返回。
* **origin\_base64**:切边或去水印前的原始页图片base64字符串。受URL参数**切边矫正**或**去水印**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。仅当开启切边或去水印,image\_output\_type=base64str且get\_image=page/both时返回。
* **raw\_ocr**:全部文字识别结果,只包含文字结果。受URL参数**raw\_ocr**影响,默认不返回,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。
* **text**:识别内容字符串,例如"这是一个例子。"
* **score**:识别置信度(0 \<= x \<= 1),例如"0.99"。
* **type**:文本类型,用于表示文字的形态。 当前版本下,文本类型包括:
* text(文本)
* formula(公式)
* **position**:文本行的四个角点坐标,依次为左上,右上,右下,左下。例如\[10, 10, 100, 10, 100, 50, 10, 50]
* **angle**:文本行的角度(可选值0, 90, 180, 270)
* **direction**:文字阅读方向。
* -1: 其他
* 0: 单字
* 1: 横向阅读
* 2: 纵向阅读
* **handwritten**:文字是否手写所得。
* -1: 未知
* 0: 非手写文字, 一般为印刷文字
* 1: 文字手写, 一般具备明显的书写特征
* **char\_scores**:字符置信度,值域范围0-1。 受URL参数**char\_details**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。设置char\_details=1时输出。
* **char\_centers**:字符中心点坐标。受URL参数**char\_details**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。设置char\_details=1时输出。
* **char\_positions**:字符四边形点坐标,以顺时针构成闭合区域。 受URL参数**char\_details**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。设置char\_details=1时输出。
* **char\_candidates**:候选字数组,表示每一个字符的候选,与候选置信度配套使用。受URL参数**char\_details**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。 设置char\_details=1时输出。
* **char\_candidates\_score**:候选字置信度数组,表示每一个候选字符的置信度,与候选字符配套使用。 受URL参数**char\_details**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。 设置char\_details=1时输出。
* **content**:基础数据,为文字行、图像中的其中一种。
* **textline:文字行**
* **id**:数据id(页内唯一)
* **type**:数据类型,line
* **text**:文本行文字内容
* **angle**:文本行文字方向, 默认为0(angle为0时, json中可能不包含angle属性)。
* **pos**:文本行四个角点坐标。
* **origin\_position**:表示文本行在原图中的坐标。受URL参数**切边矫正**或**去水印**影响,详情见[**快速启动-URL参数说明**](https://docs.textin.com/xparse/parse-quickstart)。仅当打开切边或去水印时返回,格式同pos。
* **sub\_type**:子类型。有handwriting, formula。
* **direction**:文字方向, 默认为0。
* 0:横向文本;
* 1:竖向文本;
* 2:横向右往左文本(如阿拉伯语)
* **score**:文本行内每个字符的置信度(仅当输入图像做ocr时)
* **char\_pos**:文本行内每个字符的坐标,每个item是一个由八个整数组成的数组,分别表示,左上,右上,右下,左下四个点的(x,y)坐标。受URL参数**char\_details**影响,详情见[**快速启动-URL参数说明**](https://docs.textin.com/xparse/parse-quickstart)。设置char\_details=1时输出。
* **image:图像**
* **id**:数据id
* **type**:数据类型, image
* **pos**:图像四个角点坐标
* **sub\_type**:子类型, 包括stamp, chart, qrcode, barcode
* **size**:图像大小\[width, height]
* **data**:图像内容
* **base64**:图像文件(jpg, png)的base64字符串
* **region**:图像在页图像中的区域(四边形4个点坐标)
* **path**:图像文件路径(如在zip包中的路径)
* **stamp**:当sub\_type为stamp时,返回印章识别结果
* **value**:印章文本内容
* **stamp\_shape**:印章形状
* **type**:印章类型
* **color**:印章颜色
* **structured**:结构化数据,为段落块、图像块、表格块、页脚块、页眉块中的一种。
* **textblock:段落块**
* **type**:段落块类型, 固定为 textblock
* **pos**:文本行四个角点坐标
* **origin\_position**:表示该段落在原图中的坐标。受URL参数**切边矫正**或**去水印**影响,详情见[**快速启动-URL参数说明**](https://docs.textin.com/xparse/parse-quickstart)。仅当打开切边或去水印时返回,格式同pos。
* **content**:段落块内文本行id数据组
* **sub\_type**:段落块子类型,包括catalog(目录),text(正文普通文本),text\_title(文本标题),image\_title(图片标题),table\_title(表格标题)
* **continue**:段落块连续属性,用于判断完整的段落块是否被页面或栏分割,为true表示该段落块和下一个段落块连续(即两个段落块可合成一个逻辑段落块)。
* **next\_page\_id**:当且仅当continue为true时有值。表示下一个段落块的page\_id。
* **next\_para\_id**:当且仅当continue为true时有值。表示下一个段落块的paragraph\_id。
* **text**:段落块文本内容
* **outline\_level**:标题级别: (最多支持5级标题)
* -1:正文
* 0:一级标题
* 1:二级标题
* …
* **imageblock:图像块**
* **type**:图像块类型, 值为 image
* **pos**:文本行四个角点坐标
* **origin\_position**:表示该子图在原图中的坐标。受URL参数**切边矫正**或**去水印**影响,详情见[**快速启动-URL参数说明**](https://docs.textin.com/xparse/parse-quickstart)。仅当打开切边或去水印时返回,格式同pos。
* **lines**:图像包含的文本行id
* **content**:图像资源数据id数组
* **caption\_id**:图片的标题id
* **page\_id**:标题所在页码
* **paragraph\_id**:标题所在段落id
* **text**:子图片识别得到的文本内容。受URL参数**apply\_image\_analysis**影响,详情见[**快速启动-URL参数说明**](https://docs.textin.com/xparse/parse-quickstart)。开启图像分析后,该字段内容会替换为大模型对子图片的分析结果。
* **table:表格块**
* **type**:表格块类型, 固定为table
* **sub\_type**:表格子属性,取值为bordered(有线表)或borderless(无线表),默认为bordered(即json中无该字段时,默认值为bordered)
* **pos**:文本行四个角点坐标
* **origin\_position**:表示该表格在原图中的坐标。受URL参数**切边矫正**或**去水印**影响,详情见[**快速启动-URL参数说明**](https://docs.textin.com/xparse/parse-quickstart)。仅当打开切边或去水印时返回,格式同pos。
* **rows**:表格行数
* **cols**:表格列数
* **columns\_width**:表格列宽度列表
* **rows\_height**:表格行高度列表
* **text**:表格文本内容,以html或md格式展示
* **continue**:当前表格与后一表格连续,用来判断一个表格是否被页面分割(如果 continue为true 且该表格位于本页结尾,该表格可与下一页开头表格组合为一个表格)
* **caption\_id**:表格的标题id
* **page\_id**:标题所在页码
* **paragraph\_id**:标题所在段落id
* **cells**:单元格数组
* **row**:单元格行号
* **col**:单元格列号
* **row\_span**:单元格行跨度,默认为1
* **col\_span**:单元格列跨度,默认为1
* **pos**:单元格的四个角点坐标,依次为左上,右上,右下,左下。
* **content**:单元格内容
* **footer:页脚块**
* **type**:页脚块类型,固定为 footer
* **pos**:文本行四个角点坐标
* **blocks**:footer段落内容,为textblock, imageblock, table中其中的一种
* **header:页眉块**
* **type**:页眉块类型,固定为 header
* **pos**:文本行四个角点坐标
* **blocks**:header段落内容,为textblock, imageblock, table中的其中一种
### catalog:描述目录树的结构
* **catalog**:目录树结构。受URL参数**catalog\_details**和**apply\_document\_tree**影响,详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。
* **toc**:返回的table of contents
* **sub\_type**:标题类型 text\_title、 image\_title、 table\_title
* **hierarchy**:标题层级, 1 是 一级标题, 2 是 二级标题,依次类推
* **title**:标题内容
* **page\_id**:标题所在页码(最小页码为 1)
* **paragraph\_id**:标题所在段落id
* **pos**:该目录区域的四个角点坐标,依次为左上,右上,右下,左下。
* **pos\_list**:发生标题合并时,为合并前多个标题的坐标;未发生标题合并时,即为该标题的坐标。
### elements:元素数组(parse\_mode 为 lite 时返回)
当 `parse_mode` 为 `lite` 时,返回 `elements` 数组结构,替代原有的 `detail` 和 `pages` 结构。如需将 `elements` 格式转换为原有格式,请参考[转换脚本](/xparse/parse-quickstart#elements格式转换脚本)。
* **success\_count**:解析成功页数
* **elements**:element 数组,包含文档中的所有元素
* **element\_id**:唯一标识
* **type**:类型,具体见下文 Element type 类型说明
* **text**:文本内容
* **metadata**:元数据对象
* **page\_image\_url**:页图url
* **original\_image\_url**:原始页图url,仅当开启去水印或切边时返回
* **angle**:页面角度
* **page\_number**:页码
* **page\_width**:页宽
* **page\_height**:页高
* **coordinates**:element的归一化坐标(float数组,8个值,六位小数)
* **is\_continue**:是否和下一个element合并
* **category\_depth**:目录层级,0表示一级标题,1表示2级标题,依次增加。-1表示正文段落
* **parent\_id**:父节点的element\_id。表格和图片等父节点为对应的表格标题和图片标题。文本段落的父节点为对应的文本标题
* **sub\_type**:仅当type为Image时返回,包括stamp, card, qrcode\_barcode, chart
* **image\_url**:仅当type为Image 且请求参数 image\_output\_type=default 时返回,值为子图的url
* **image\_base64**:仅当type为Image 且请求参数 image\_output\_type=base64str时返回,值为子图的base64字符串
#### Element type 类型说明
当 `parse_mode` 为 `lite` 时,返回的 `elements` 数组中每个 element 的 `type` 字段可能的值如下:
| Element type | 说明 |
| ----------------- | -------------------------- |
| NarrativeText | 除了标题、页眉页脚、图片说明文字列表外的普通段落文字 |
| Title | 章节标题 |
| Table | 表格 |
| TableCaption | 表格标题 |
| Image | 图片 |
| FigureCaption | 图片标题 |
| Formula | 公式 |
| Header | 页眉 |
| Footer | 页脚 |
| CodeSnippet | 代码片段 |
| PageNumber | 页码 |
| UncategorizedText | 其他文本 |
### 其他result字段
* **total\_count**:解析总页数
* **success\_count**:解析成功的页数(parse\_mode 为 lite 时返回)
* **total\_page\_number**:输入PDF时, 返回文档的总页数。
* **valid\_page\_number**:记录本次解析成功的总页数。
* **excel\_base64**:excel的base64结果,受URL参数**get\_excel**影响,仅当get\_excel=1时返回。详情见[快速启动-URL参数说明](/xparse/parse-quickstart)。
## metrics:每一页的信息
部分信息跟**pages**字段重复,当URL参数**page\_details**设置为不返回pages字段时,可以在**metrics**字段获取每一页的信息。
* **metrics**:每一页信息
* **page\_image\_width**:当前段落所在页的图片宽或者pdf转成的图片宽,例如"1024"。
* **page\_image\_height**:当前段落所在页的图片高或者pdf转成的图片高,例如"768"。
* **dpi**:当前pdf页转成图片所用的dpi,例如"72"。
* **durations**:当前页总耗时(毫秒)
* **status**:当前页状态
* **page\_id**:当前页码
* **angle**:图像角度, 定义0度为人类阅读文字的图像方向,称为正置图像, 本字段表示输入图像是正置图像进行顺时针若干角度的旋转所得。
* 0: ▲
* 90: ▶
* 180: ▼
* 270: ◀
* **image\_id**:当前页图片id。
* 下载方式:[https://api.textin.com/ocr\_image/download?image\_id=xxx](https://api.textin.com/ocr_image/download?image_id=xxx), 需要在headers里添加appid和key, 有效期30天
**另外您也可以在**[**API**](/api-reference/endpoint/parse)**中查看Response说明以及调试查看结果。**
## 将结果保存为JSON或markdown文件
参考[快速启动](/xparse/parse-quickstart)中的使用示例,您可以将API返回的结果保存为JSON文件,也可以解析JSON响应以提取并保存markdown文件。以下示例代码在快速启动中已提供,您可以直接使用。
```python theme={null}
# 保存完整的JSON响应到result.json文件
with open("result.json", "w", encoding="utf-8") as f:
f.write(response)
# 解析JSON响应以提取markdown内容
json_response = json.loads(response)
if "result" in json_response and "markdown" in json_response["result"]:
markdown_content = json_response["result"]["markdown"]
with open("result.md", "w", encoding="utf-8") as f:
f.write(markdown_content)
```
# 前端可视化:获取精确坐标
Source: https://docs.textin.com/xparse/parse-getpos
一个功能丰富的RAG应用,通常会支持用户查看大模型找到的片段在原文档中的具体位置,从而让用户检查大模型是否在胡编乱造。而这就需要能把文本段落等各元素在原文档中高亮标记出来的能力。
TextIn xParse文档解析API支持返回块级坐标`position`以及字符级坐标`char_pos`(请求时设置URL参数`char_details=true`),代表解析结果片段在原文档中的精确位置。
将解析结果和坐标可视化,有助于:
* 与原文档对照,细粒度验证解析的效果
* 审核校正解析结果
例如,下面是一个原文档(带坐标回显,左)和解析结果(Markdown,右)的对比图:
![]() 接下来详细介绍如何利用python实现坐标可视化。
本教程基于Textin官方pdf示例文件,您可点击下载或使用该链接:[文档解析pdf示例.pdf](https://web-api.textin.com/open/image/download?filename=a2bd40607faa4be7ba975d41c96b9a47)
## 上传pdf文件,获取解析结果
参考[快速启动](/xparse/parse-quickstart),上传pdf文件,获取解析结果。为获得详细的页面信息和坐标数据,解析时需要设置URL参数page\_details=1和markdown\_details=1。
本次示例文件解析结果如下(为方便展示,此处只解析一页,仅列出坐标相关数据):
```python theme={null}
{
"code": 200,
"message": "success",
"duration": 1751,
"result": {
"pages": [
{
"status": "Success",
"angle": 0,
"page_id": 1,
"width": 1191,
"height": 1684,
"structured": [
{
"blocks": [
{
"id": 0,
"pos": [71,146,549,144,548,185,70,187],
"text": "某服装企业(600398.SH)",
"type": "textblock"
# ...
}
],
"type": "header"
},
{
"type": "header",
"blocks": [
{ "id": 2,
"pos": [69,203,781,203,781,238,69,238],
"text": "第三季度收入下滑11%,费用率提升盈利承压",
"type": "textblock",
}
],
}
]
# ...
}
],
"detail": [
{
"page_id": 1,
"text": "**某服装企业(600398.SH)**"
"position": [71,146,549,144,548,185,70,187]
# ...
},
{
"page_id": 1,
"text": "**第三季度收入下滑11%,费用率提升盈利承压**"
"position": [69,203,781,203,781,238,69,238]
# ...
}
# ...
]
}
}
```
`pages`字段包含每一页的信息,其中`page_id`表示页码(从1开始),`width, height`表示识别时文档转成图像的宽高,`angle`表示将图像转正的角度(如需要),`structured`表示解析后对应页的结构化数据,包含元素块内容以及对应的坐标`pos`。
`detail`中包含所有markdown块级元素(文字、段落、表格等)的详细信息,每一块通过`page_id`与页码关联,`position`字段表示该块的坐标信息。与`pages`不同的是,detail中是将markdown内容规整后元素块,比如跨页段落、跨页表格在detail中已经合并,采用了更好的语义上的分割,可以直接用于下游需要分块的应用,而`pages`中最大限度地保留了每一页的原始信息。
**坐标系统说明**
接口返回的坐标格式为:`[x1, y1, x2, y2, x3, y3, x4, y4]`
这表示一个四边形的四个顶点坐标,按顺时针排列:
```
坐标数组: [x1, y1, x2, y2, x3, y3, x4, y4]
↑左上 ↑右上 ↑右下 ↑左下
```
该坐标表示在识别时以页面左上角为原点,宽高为`page.width`、`page.height`画布下的绝对坐标,单位为像素(px)。
比如上述接口返回:
```json theme={null}
"pages": [{ "width": 1191, "height": 1684}]
"position": [69,203,781,203,781,238,69,238]
```
在图像上示意如下:
```
图像坐标系 (原点在左上角)
┌───────────────1191────────────────── x
│(0,0)
│
│
│ (69,203) ───────────── (781,203)
│ │ │
1684 文本区域
│ │ │
│ (69,238) ───────────── (781,238)
│
│
│
│
y
```
下面演示如何从pages中和detail中获取页面和元素块坐标信息,并在原文档上绘制标注。
原文档页面图片可以通过设置参数`get_image="page"或"both"`返回,
您将获得每一页的image\_id或者base64(详见[JSON结构说明](/xparse/parse-getjson))用于预览,也可以手动将您的原文档转成图片,
只要保证每一页的图片跟上述`page.width`、`page.height`同比例渲染,`position`中的坐标值也需要跟随页面同比例缩放,,即可准确绘制。
## 从API返回结果中获取坐标数据
从json结果提取出每一页的元素坐标信息,输出到二维数组:
```python theme={null}
def extract_coordinates_from_parse_result(parse_result):
"""
从API返回的解析结果中提取每页的宽高、角度和所有detail块的坐标信息
返回: [{width, height, angle, details: [detail, ...]}, ...]
"""
result = parse_result.get("result", {})
pages = result.get("pages", [])
details = result.get("detail", [])
# 按页组织details
page_map = {}
for page in pages:
page_id = page.get("page_id", 1)
page_map[page_id] = {
"width": page.get("width", 0),
"height": page.get("height", 0),
"angle": page.get("angle", 0),
"details": []
}
for d in details:
page_id = d.get("page_id", 1)
if page_id in page_map:
page_map[page_id]["details"].append(d)
# 保证顺序
return [page_map[pid] for pid in sorted(page_map.keys())]
```
## 绘制坐标框到原图
```python theme={null}
import fitz # PyMuPDF
from PIL import Image, ImageDraw
import os
# pdf转图片,获取页面图片
def pdf_to_images(pdf_path, output_dir="./temp_images"):
os.makedirs(output_dir, exist_ok=True)
doc = fitz.open(pdf_path)
zoom = 144 / 72 # dpi=144,图片更清晰
mat = fitz.Matrix(zoom, zoom)
image_paths = []
for i, page in enumerate(doc):
pix = page.get_pixmap(matrix=mat)
img_path = os.path.join(output_dir, f"page_{i+1}.png")
pix.save(img_path)
image_paths.append(img_path)
doc.close()
return image_paths
# 绘制一页坐标
def draw_boxes_on_image(image_path, details, page_width, page_height, color=(26,102,255), line_width=2):
image = Image.open(image_path).convert("RGB")
draw = ImageDraw.Draw(image)
img_w, img_h = image.size
# 根据解析时的页面宽高缩放适配,确保绘制坐标准确
scale_x = img_w / page_width if page_width else 1
scale_y = img_h / page_height if page_height else 1
for d in details:
pos = d.get("position")
if pos and len(pos) == 8:
points = [
(pos[0]*scale_x, pos[1]*scale_y),
(pos[2]*scale_x, pos[3]*scale_y),
(pos[4]*scale_x, pos[5]*scale_y),
(pos[6]*scale_x, pos[7]*scale_y),
(pos[0]*scale_x, pos[1]*scale_y)
]
draw.line(points, fill=color, width=line_width)
out_path = image_path.replace('.png', '_boxed.png')
image.save(out_path)
return out_path
# 绘制所有页面全部坐标
def annotate_pdf_with_boxes(pdf_path, page_details, output_dir="./annotated_images"):
os.makedirs(output_dir, exist_ok=True)
image_paths = pdf_to_images(pdf_path, output_dir=output_dir)
result_paths = []
for i, page in enumerate(page_details):
img_path = image_paths[i]
out_path = draw_boxes_on_image(
img_path,
page["details"],
page["width"],
page["height"]
)
result_paths.append(out_path)
return result_paths
# 使用示例
if __name__ == "__main__":
import json
PDF_PATH = "your_document.pdf"
JSON_PATH = "parse_result.json"
with open(JSON_PATH, "r", encoding="utf-8") as f:
parse_result = json.load(f)
page_details = extract_coordinates_from_parse_result(parse_result)
result_imgs = annotate_pdf_with_boxes(PDF_PATH, page_details)
print("标注图片:", result_imgs)
```
### 代码使用说明
**1. 准备环境**
```bash theme={null}
pip install PyMuPDF pillow
```
**2. 绘制图片和坐标**
将上述代码保存为`pdf_coordinate_drawer.py`文件,替换main函数中的`your_document.pdf`和`parse_result.json`为真实文件路径,运行:
```bash theme={null}
python3 pdf_coordinate_drawer.py
```
**3. 输出结果**
* 每页生成一个标注后的PNG图片
* 坐标框用指定颜色绘制,您也可以自定义颜色,不同类型元素用不同颜色绘制
* 生成坐标类型图例
该示例生成的标注最终效果如下:
![]() 可以看到,Textin xParse针对复杂布局的文档,能够精准识别并细粒度还原坐标,方便您将解析结果与原文件进行对比,查看解析效果以及审核校正。
## 前端开源项目
此外,我们开源了web前端项目[xparse-frontend](https://github.com/intsig-textin/xparse-frontend/),该项目包含跟我们[在线web平台](https://www.textin.com/console/recognition/robot_markdown?service=pdf_to_markdown)效果一致的全套前端代码,具备文件预览、坐标回显、动态交互对照、编辑校正、导出多种格式结果文件等丰富功能。上手方便,开箱即用,欢迎体验!
## 常见问题
### **坐标偏移不准确,有错位**
**可能原因:**
* 文档转图片使用了跟解析时不同的DPI,且坐标没有根据解析返回的页面宽高缩放适配
* 页面旋转角度未正确处理
**解决方案**
* 文档转图片的时候使用跟解析相同的DPI,或者渲染时将页面和坐标值根据解析返回的页面宽高缩放适配(推荐,参考上述代码示例)
* 确认页面是否经过旋转(angle),绘制时设置angle修正角度
### **如何处理跨页段落和表格**
跨页信息可以在两个位置获取:
* 在pages的structure中:跨页信息通过continue和next\_page\_id、next\_para\_id表示
* 在detail中:跨页信息通过通过split\_section\_page\_ids和split\_section\_positions表示
更多信息请参考[JSON结构说明](/xparse/parse-getjson)。
# 获取表格
Source: https://docs.textin.com/xparse/parse-gettable
在RAG应用中,为了更高的信息精度或稳定性,通常需要对表格做单独处理,如将表格区域保存为图片供前端展示,或者单独为表格设置分chunk策略等。在TextIn xParse文档解析API的输出中,对每个表格都有单独的定义,您可以获取每个表格并单独保存下来。
此外,我们也提供了一步到位的从PDF中提取表格并保存为Excel文件的教程,方便整合到您现有的基于Excel的业务任务流程中。
## 如何获取表格
您可以参考以下步骤和示例代码将解析获取到的表格保存为 md 和 json 以及 excel 格式的文件。
### 将表格保存为 md 和 json 文件
*
* 参考[快速启动](/xparse/parse-quickstart),在 options 中设置URL参数 table\_flavor 为 md 或 html,这样API会以Markdown或HTML格式输出表格。您可根据实际需要进行设置。
* 在main函数中添加以下示例代码,解析API输出markdown中的表格,并保存为 md 和 json 文件。
```python theme={null}
import re
if "result" in json_response and "markdown" in json_response["result"]:
markdown_content = json_response["result"]["markdown"]
# 提取所有表格
tables = re.findall(r'(?:\|.*\n)+', markdown_content)
tables_md = '\n'.join(tables)
# 保存为md文件
with open("tables.md", "w", encoding="utf-8") as f:
f.write(tables_md)
tables_json = []
for page in json_response["result"]["pages"]:
for block in page.get("structured", []):
if block.get("type") == "table":
tables_json.append(block)
# 保存为 json 文件
with open("tables.json", "w", encoding="utf-8") as f:
json.dump(tables_json, f, ensure_ascii=False, indent=2)
```
### 将表格保存为 excel 文件
* 参考[快速启动](/xparse/parse-quickstart),在 options 中设置URL参数 get\_excel=1,让API返回 excel\_base64 字段(Excel文件的base64编码)。
* 在main函数中添加以下示例代码,将表格保存为excel文件。
```python theme={null}
import base64
if "result" in json_response and "excel_base64" in json_response["result"]:
excel_base64 = json_response["result"]["excel_base64"]
excel_bytes = base64.b64decode(excel_base64)
with open("result.xlsx", "wb") as f:
f.write(excel_bytes)
print("Excel 文件已保存为 result.xlsx")
else:
print("未检测到 excel_base64 字段,可能 PDF 中没有表格或参数设置有误。")
```
* 参考[快速启动](/xparse/parse-quickstart)中的示例文件,保存后的表格如下图(仅截取部分作为示例)
![Parse Gettable Pn]() # 多并发请求
Source: https://docs.textin.com/xparse/parse-max-workers
在实际使用过程中,您可能会需要在一定时间内集中性的批量解析文档;在这种情况下,即使TextIn xParse 文档解析API本身的速度足够快,但依次逐个解析大批量文档所需要的总耗时也可能会较长。
针对这种情况,TextIn xParse 文档解析API支持多并发请求,默认2 QPS,如果您有更大并发的需求,可以联系我们进行[商务咨询](https://www.textin.com/contact?type=28)。帮助您快速高效的完成大批量文档解析工作。
### 多并发测试
您可以先参考以下示例代码进行文档解析API的多并发请求测试。
```python theme={null}
import concurrent.futures
import subprocess
import time
# 要测试的命令
CMD = [
"python3",
"用于跑示例的请求脚本.py" # 替换为你用于测试的请求脚本,也可以使用下文提供的脚本进行测试
]
# 并发数
CONCURRENCY = 5
# 总测试次数
TOTAL_RUNS = 5
def run_cmd(i):
try:
result = subprocess.run(CMD, capture_output=True, text=True, check=True)
print(f"任务 {i} 成功,输出:{result.stdout.strip()}")
except subprocess.CalledProcessError as e:
print(f"任务 {i} 失败,错误:{e.stderr.strip()}")
if __name__ == "__main__":
print(f'并发测试,当前并发数为: {CONCURRENCY}')
start_time = time.time()
with concurrent.futures.ThreadPoolExecutor(max_workers=CONCURRENCY) as executor:
futures = [executor.submit(run_cmd, i) for i in range(TOTAL_RUNS)]
concurrent.futures.wait(futures)
end_time = time.time()
print(f"程序总耗时:{end_time - start_time:.2f} 秒")
```
这里使用[快速启动](/xparse/parse-quickstart)中的示例文件进行多并发测试:[文档解析pdf示例.pdf](https://dllf.intsig.net/download/2025/Solution/textin/sample/pdf_to_markdown/sample_02.pdf)
* 测试脚本如下:参考[快速启动](/xparse/parse-quickstart),解析位于URL的文件并保存结果;需替换您自己的 x-ti-app-id 和 x-ti-secret-code
注意:进行多并发测试等同对当前账号发起线上资源操作,请留意费用情况,请小心操作。
```python theme={null}
import json
import requests
class OCRClient:
def __init__(self, app_id: str, secret_code: str):
self.app_id = app_id
self.secret_code = secret_code
def recognize(self, file_content: bytes, options: dict) -> str:
# 构建请求参数
params = {}
for key, value in options.items():
params[key] = str(value)
# 设置请求头
headers = {
"x-ti-app-id": self.app_id,
"x-ti-secret-code": self.secret_code,
# 方式一:读取本地文件
# "Content-Type": "application/octet-stream"
# 方式二:使用URL方式
"Content-Type": "text/plain"
}
# 发送请求
response = requests.post(
f"https://api.textin.com/ai/service/v1/pdf_to_markdown",
params=params,
headers=headers,
data=file_content
)
# 检查响应状态
response.raise_for_status()
return response.text
def main():
# 创建客户端实例,需替换为你的API Key
client = OCRClient("你的x-ti-app-id", "你的x-ti-secret-code")
# 文件URL,这里为你提供了一份真实可用的示例URL
file_content = "https://dllf.intsig.net/download/2025/Solution/textin/sample/pdf_to_markdown/sample_02.pdf"
# 设置URL参数,可按需设置,这里已为你默认设置了一些参数
options = dict(
dpi=144,
get_image="objects",
markdown_details=1,
page_count=10,
parse_mode="auto",
table_flavor="html"
)
import time
# 在发送请求前记录开始时间
start_time = time.time()
try:
response = client.recognize(file_content, options)
# 保存完整的JSON响应到result.json文件
with open("result.json", "w", encoding="utf-8") as f:
f.write(response)
# 解析JSON响应以提取markdown内容
json_response = json.loads(response)
if "result" in json_response and "markdown" in json_response["result"]:
markdown_content = json_response["result"]["markdown"]
with open("result.md", "w", encoding="utf-8") as f:
f.write(markdown_content)
# 记录请求结束时间
end_time = time.time()
print(f"请求耗时:{end_time - start_time:.2f} 秒")
except Exception as e:
print(f"Error: {e}")
if __name__ == "__main__":
main()
```
* 多并发测试结果如下图:可以看到文档解析API支持多并发请求,并且可以极大程度上节省时间。我们始终贯彻“您只需关心业务,剩下的文档解析处理工作交给TextIn”的理念,希望尽一切可能为您的业务发展提供帮助。
![Concurrent1 Pn]()
![Concurrent5 Pn]() ### 多并发请求
当您想要进行文档解析API的多并发请求时,以下是一份完整的示例代码供您参考,您也可以根据实际使用需要进行修改调整。
```python theme={null}
import os
import json
import requests
from concurrent.futures import ThreadPoolExecutor, as_completed
class OCRClient:
def __init__(self, app_id: str, secret_code: str):
self.app_id = app_id
self.secret_code = secret_code
def recognize(self, file_content: bytes, options: dict) -> str:
params = {key: str(value) for key, value in options.items()}
headers = {
"x-ti-app-id": self.app_id,
"x-ti-secret-code": self.secret_code,
"Content-Type": "application/octet-stream"
}
response = requests.post(
"https://api.textin.com/ai/service/v1/pdf_to_markdown",
params=params,
headers=headers,
data=file_content
)
response.raise_for_status()
return response.text
def process_file(client: OCRClient, file_path: str, output_dir: str, options: dict):
filename = os.path.basename(file_path)
try:
with open(file_path, "rb") as f:
file_content = f.read()
response = client.recognize(file_content, options)
base_name = os.path.splitext(filename)[0]
# 保存JSON
with open(os.path.join(output_dir, f"{base_name}.json"), "w", encoding="utf-8") as fw:
fw.write(response)
# 保存Markdown
json_response = json.loads(response)
if "result" in json_response and "markdown" in json_response["result"]:
markdown_content = json_response["result"]["markdown"]
with open(os.path.join(output_dir, f"{base_name}.md"), "w", encoding="utf-8") as fw:
fw.write(markdown_content)
print(f"{filename} 处理完成")
except Exception as e:
print(f"{filename} 处理出错: {e}")
def main():
client = OCRClient("你的x-ti-app-id", "你的x-ti-secret-code")
input_dir = "./tmp" # 你的待解析文件夹
output_dir = "./output" # 输出结果的文件夹
os.makedirs(output_dir, exist_ok=True)
exts = (".pdf",".png",".jpg",".jpeg",".bmp",".tiff",".webp",".doc",".docx",".html",".mhtml",".xls",".xlsx",".csv",".ppt",".pptx",".txt",".ofd",".rtf")
files = [f for f in os.listdir(input_dir) if f.lower().endswith(exts)]
file_paths = [os.path.join(input_dir, f) for f in files]
# 设置URL参数,可按需设置,这里已为你默认设置了一些参数
options = dict(
dpi=144,
get_image="objects",
markdown_details=1,
page_count=10,
parse_mode="auto",
table_flavor="html"
)
# 设置并发数
max_workers = 5 # 你可以根据需要调整并发数
with ThreadPoolExecutor(max_workers=max_workers) as executor:
futures = [
executor.submit(process_file, client, file_path, output_dir, options)
for file_path in file_paths
]
for future in as_completed(futures):
# 这里可以捕获每个任务的异常
try:
future.result()
except Exception as exc:
print(f"任务出错: {exc}")
if __name__ == "__main__":
main()
```
# 快速启动
Source: https://docs.textin.com/xparse/parse-quickstart
参考示例,快速将文档解析API接入到您的系统和应用流程中。
本教程基于python示例分步讲解如何使用文档解析API。我们另外提供了完整的多语言示例代码包,可在本地一键运行,助您10s跑通接口示例,请[点击下载](https://static.textin.com/docs/%E9%80%9A%E7%94%A8%E6%96%87%E6%A1%A3%E8%A7%A3%E6%9E%90-%E7%A4%BA%E4%BE%8B%E4%BB%A3%E7%A0%81.zip)。如需在线快捷调试API,请参考[Textin文档中心](https://www.textin.com/document/legacy/pdf_to_markdown)。
## 为什么使用文档解析API ?
大模型时代,文档(尤其是复杂文档)中蕴含着海量高价值的数据内容,借助文档解析API将其结构化为大模型更容易理解的格式(如markdown),可以更大程度上增强大模型的能力、发挥更大价值,快速实现业务AI升级。
TextIn xParse 文档解析API 是专为大模型重新设计的文档理解引擎,可以满足AI开发者的核心需求:✅ 文档结构完整保持 ✅ 语义关系准确理解 ✅ 大模型原生友好
使用文档解析API解析一个或多个文档,您可以选择将输出结果作为markdown或JSON文件保存在指定的目录中,也可以对输出结果做进一步的处理以满足您的业务需求。如果您正在进行知识库、RAG、大模型原生应用、Agent等业务方向的产品建设,文档解析API会为您提供帮助。
## 如何使用文档解析API ?
您可以参考以下示例文件和步骤,快速验证并将文档解析API接入到您的系统和应用流程中。
这里为您提供了一份Textin官方pdf示例文件,您可以点击下载或使用该链接:[文档解析pdf示例.pdf](https://dllf.intsig.net/download/2025/Solution/textin/sample/pdf_to_markdown/sample_02.pdf)
### 先决条件:获取API Key
使用文档解析API处理文档时,您需要先获取API Key。请先登录后前往 [TextIn工作台 - 账号与开发者信息](https://www.textin.com/console/dashboard/setting) 获取您的 x-ti-app-id 和 x-ti-secret-code 。
想要快速调试API?请参考[Postman调试教程](/xparse/parse-debug-postman)或[Apifox调试教程](/xparse/parse-debug-apifox)。
### 前置准备
您可以参考以下示例代码完成文档解析API请求的前置准备工作,替换您自己的 x-ti-app-id 和 x-ti-secret-code ,后续步骤可根据实际使用场景在main函数中插入代码。
```python theme={null}
import json
import requests
class OCRClient:
def __init__(self, app_id: str, secret_code: str):
self.app_id = app_id
self.secret_code = secret_code
def recognize(self, file_content: bytes, options: dict) -> str:
# 构建请求参数
params = {}
for key, value in options.items():
params[key] = str(value)
# 设置请求头
headers = {
"x-ti-app-id": self.app_id,
"x-ti-secret-code": self.secret_code,
# 方式一:读取本地文件
"Content-Type": "application/octet-stream"
# 方式二:使用URL方式
# "Content-Type": "text/plain"
}
# 发送请求
response = requests.post(
f"https://api.textin.com/ai/service/v1/pdf_to_markdown",
params=params,
headers=headers,
data=file_content
)
# 检查响应状态
response.raise_for_status()
return response.text
def main():
# 创建客户端实例,需替换你的API Key
client = OCRClient("你的x-ti-app-id", "你的x-ti-secret-code")
# 插入下面的示例代码
if __name__ == "__main__":
main()
```
### 解析单个本地文件并保存结果
复制以下示例代码,粘贴至前置准备代码的main函数中;替换要解析的文件;运行脚本来解析本地目录中的文件并将结果作为markdown和JSON文件保存。
请注意:请求体的数据格式为本地文件的二进制流,非 FormData 或其他格式。文件大小不超过 500M,长宽比小于2的图片宽高需在20~20000像素范围内,其他图片的宽高需在20~10000像素范围内。
* 支持的文件格式:png, jpg, jpeg, pdf, bmp, tiff, webp, doc, docx, html, mhtml, xls, xlsx, csv, ppt, pptx, txt, ofd, rtf
* 如果是xls/xlsx/csv文件,每个sheet行数不能超过2000,列数不能超过100。
* 如果是txt文件,文件大小不超过100k。
```python theme={null}
# 在main函数中插入
# 读取本地文件
with open("你的文件.pdf", "rb") as f:
file_content = f.read()
# 设置URL参数,可按需设置,这里已为你默认设置了一些参数
options = dict(
dpi=144,
get_image="objects",
markdown_details=1,
page_count=10,
parse_mode="auto",
table_flavor="html"
)
try:
response = client.recognize(file_content, options)
# 保存完整的JSON响应到result.json文件
with open("result.json", "w", encoding="utf-8") as f:
f.write(response)
# 解析JSON响应以提取markdown内容
json_response = json.loads(response)
if "result" in json_response and "markdown" in json_response["result"]:
markdown_content = json_response["result"]["markdown"]
with open("result.md", "w", encoding="utf-8") as f:
f.write(markdown_content)
print(response)
except Exception as e:
print(f"Error: {e}")
```
### 解析多个本地文件并保存结果至指定目录
复制以下示例代码,粘贴至前置准备代码的main函数中;替换要解析的文件夹和输出结果文件夹;运行脚本来解析本地目录中的多个文件并将结果作为markdown和JSON文件保存至指定目录中。
```python theme={null}
# 在main函数中插入
# 读取本地文件夹
input_dir = "./tmp" # 你可以修改为自己的文件夹
output_dir = "./output" # 输出结果的文件夹
import os
os.makedirs(output_dir, exist_ok=True)
# 支持的文件类型
exts = (".pdf",".png",".jpg",".jpeg",".bmp",".tiff",".webp",".doc",".docx",".html",".mhtml",".xls",".xlsx",".csv",".ppt",".pptx",".txt",".ofd",".rtf")
files = [f for f in os.listdir(input_dir) if f.lower().endswith(exts)]
# 设置URL参数,可按需设置,这里已为你默认设置了一些参数
options = dict(
dpi=144,
get_image="objects",
markdown_details=1,
page_count=10,
parse_mode="auto",
table_flavor="html"
)
#循环处理
for filename in files:
file_path = os.path.join(input_dir, filename)
with open(file_path, "rb") as f:
file_content = f.read()
try:
response = client.recognize(file_content, options)
base_name = os.path.splitext(filename)[0]
# 保存JSON
with open(os.path.join(output_dir, f"{base_name}.json"), "w", encoding="utf-8") as fw:
fw.write(response)
# 保存Markdown
json_response = json.loads(response)
if "result" in json_response and "markdown" in json_response["result"]:
markdown_content = json_response["result"]["markdown"]
with open(os.path.join(output_dir, f"{base_name}.md"), "w", encoding="utf-8") as fw:
fw.write(markdown_content)
print(f"{filename} 处理完成")
except Exception as e:
print(f"{filename} 处理出错: {e}")
```
### 解析位于URL的文件并保存结果
您可以参考以下步骤,解析位于URL的文件。
请注意:请求体的数据格式为文本,内容为在线文件的URL链接(支持http以及https协议)。在线文件大小不超过 500M,长宽比小于2的图片宽高需在20~20000像素范围内,其他图片的宽高需在20~10000像素范围内。为了快速验证接入,这里为您提供了示例文件URL。
* 步骤一:在前置准备代码中修改请求头设置。
```python theme={null}
# 在前置准备中修改请求头设置
headers = {
"x-ti-app-id": self.app_id,
"x-ti-secret-code": self.secret_code,
# 方式:使用URL方式
"Content-Type": "text/plain"
}
```
* 步骤二:复制以下示例代码,粘贴至前置准备代码的main函数中;替换要解析的文件URL或直接使用示例URL;运行脚本来解析位于URL的文件并将结果作为markdown和JSON文件保存。
```python theme={null}
# 在main函数中插入
# 文件URL,这里为你提供了一份真实可用的示例URL
file_content = "https://dllf.intsig.net/download/2025/Solution/textin/sample/pdf_to_markdown/sample_02.pdf"
# 设置URL参数,可按需设置,这里已为你默认设置了一些参数
options = dict(
dpi=144,
get_image="objects",
markdown_details=1,
page_count=10,
parse_mode="auto",
table_flavor="html"
)
try:
response = client.recognize(file_content, options)
# 保存完整的JSON响应到result.json文件
with open("result.json", "w", encoding="utf-8") as f:
f.write(response)
# 解析JSON响应以提取markdown内容
json_response = json.loads(response)
if "result" in json_response and "markdown" in json_response["result"]:
markdown_content = json_response["result"]["markdown"]
with open("result.md", "w", encoding="utf-8") as f:
f.write(markdown_content)
print(response)
except Exception as e:
print(f"Error: {e}")
```
### URL参数说明
以下是文档解析API的URL参数,URL参数指以 参数名=参数值 形式拼接到 URL 上的键值对。它以 `?` 开头,不同参数之间使用 `&` 连接,形如 `?p1=v1&p2=v2`。URL参数会影响文档的解析结果和JSON输出内容,您可按需进行设置。
* **parse\_mode**:文档的解析模式,默认为scan模式。
* auto 由引擎自动选择,适用范围最广
* scan 文档统一当成图片解析(如pdf每一页都当成图片解析)
* lite 轻量版,只输出表格和文字结果
* parse 仅电子档文字解析,速度最快
* **pdf\_pwd**:当pdf为加密文档时,需要提供密码。
* 备注:对前端封装该接口参数时,需要自行对密码进行安全防护。
* **page\_start**:当上传的是pdf时,表示从第几页开始解析,取值范围从1开始,不传该参数时默认从首页开始。
* **page\_count**:当上传的是pdf时,表示要进行解析的pdf页数。总页数不得超过1000页,默认为1000页。
* **dpi**:pdf文档的坐标基准,默认144 dpi。 与**parse\_mode**参数联动
* 当parse\_mode=auto时,默认动态,支持72,144,216;
* 当parse\_mode=scan时,默认144,支持72,144,216。
* **apply\_document\_tree**:**markdown**中是否生成标题层级,默认为1,生成标题。
* 0 不生成标题:同时也不会返回**catalog**字段
* 1 生成标题
* **table\_flavor**:**markdown**里的表格格式,默认为html,按html语法输出表格。
* md 按md语法输出表格
* html 按html语法输出表格
* none 不进行表格识别,把表格图像当成普通文字段落来识别。
* **get\_image**:获取**markdown**里的图片,默认为none,不返回任何图像。
* none 不返回任何图像
* page 返回每一页的整页图像:即pdf页的完整页图片
* objects 返回页面内的子图像:即pdf页内的各个子图片
* both 返回整页图像和图像对象
* **image\_output\_type**:指定返回的图片对象输出类型,默认返回子图片url和页图片id。
* base64str 指定所有图片对象为base64字符串,适用于没有云存储的用户,但是引擎返回结果体积会很大。
* default 指定子图片对象为图片url,页图片对象为图片id
* **apply\_image\_analysis**:图像分析参数。利用大模型对文档中的子图片进行分析,分析结果以markdown格式输出,并替换掉子图片的文本识别内容。默认为0,不进行图像分析。
* 0 不进行图像分析
* 1 进行图像分析
* **paratext\_mode**:**markdown**中非正文文本内容展示模式。默认为annotation。非正文内容包括页眉页脚、子图中的文本。
* none 不展示
* annotation 以注释格式插入到markdown中。页眉页脚中的图片只保留文本,图片base64或url不保留
* body 以正文格式插入到markdown中
* **formula\_level**:公式识别等级,默认为0,全识别。开启公式识别后,会使用latex表达式。
* 0 行间公式和行内公式都识别
* 1 仅识别行间公式,行内公式不识别
* 2 不识别公式
* **underline\_level**:控制下划线识别范围,默认为0,不识别。
* 0: 不识别
* 1: 仅识别无文字的下划线,仅scan模式可用
* 2: 识别全部的下划线,仅scan模式可用
* **apply\_merge**:是否进行段落合并和表格合并。默认为1,合并段落和表格。
* 0 不合并
* 1 合并
* **markdown\_details**:是否返回结果中的**detail**字段。默认为1,返回detail字段,保存markdown各类型元素的详细信息。
* 0 不返回
* 1 返回
* **page\_details**:是否返回结果中的**pages**字段。默认为1,返回pages字段,保存每一页更加详细的解析结果。
* 0 不返回
* 1 返回
* **raw\_ocr**:是否返回全部文字识别结果(包含字符坐标信息),结果字段为**raw\_ocr**。默认为0,不返回。与**page\_details**参数联动,当page\_details为0或false时不返回。
* 0 不返回
* 1 返回
* **char\_details**:是否返回结果中的**char\_pos**字段(保存每个字符的位置信息)和**raw\_ocr**中的**char\_**相关字段。默认为0,不返回。
* 0 不返回
* 1 返回
* **catalog\_details**:是否返回结果中的**catalog**字段,保存目录相关信息。与**apply\_document\_tree**参数联动,当apply\_document\_tree为0时不返回。
* 0 不返回
* 1 返回
* **get\_excel**:是否返回excel的base64结果,结果字段为**excel\_base64**,可以根据该字段进行后处理保存excel文件。默认为0,不返回。
* 0 不返回
* 1 返回
* **crop\_dewarp**(**切边矫正**):是否进行切边矫正预处理,默认为0,不进行切边矫正。
* 0 不进行切边矫正
* 1 进行切边矫正
* **remove\_watermark**(**去水印**):是否进行去水印预处理,默认为0,不去水印。
* 0 不去水印
* 1 去水印
* **apply\_chart**(**图表识别**):是否开启图表识别,开启图表识别会将识别到的图表以表格形式输出。默认为0,不进行图表识别。
* 0 不开启图表识别
* 1 开启图表识别
### 返回结果示例
解析后的结果数据将按照以下JSON格式返回。**根据 `parse_mode` 的不同,返回结构会有所不同**:
* 当 `parse_mode` 为 `auto`、`scan`、`parse` 时,返回 `markdown`、`detail`、`pages` 等字段
* 当 `parse_mode` 为 `lite` 时,返回新的 `elements` 结构(包含 `success_count`、`elements` 数组等字段)
下面为您提供了两种格式的返回示例。如果您想了解最全面的返回结果说明,可以在[返回JSON结构说明](/xparse/parse-getjson)中查看,也可以在[API](/api-reference/endpoint/parse)中查看和调试。
#### parse\_mode 为 auto/scan/parse 时的返回结构
```json theme={null}
{
"code": 200, // 响应状态码,200表示成功
"result": {
"markdown": "# 劳动人事争议仲裁申请书\n\n致:广东省劳动人事争议调解仲裁院\n\n[完整表格内容...]", // 生成的markdown格式文档内容正文字符串
"success_count": 5, // 成功处理的页面数量
"pages": [
{
"angle": 0, // 页面旋转角度,0表示无旋转
"page_id": 1, // 页面ID
"content": [
{
"pos": [276, 243, 970, 243, 970, 291, 276, 291], // 文本行四个角点坐标
"id": 0, // 内容块ID
"score": 1, // 识别置信度分数
"type": "line", // 内容类型,line表示文本行
"text": "劳动人事争议仲裁申请书" // 识别的文本内容
},
{
"pos": [181, 400, 560, 400, 560, 424, 181, 424], // 文本行四个角点坐标
"id": 1, // 内容块ID
"score": 1, // 识别置信度分数
"type": "line", // 内容类型,line表示文本行
"text": "致:广东省劳动人事争议调解仲裁院" // 识别的文本内容
}
// [更多content条目...]
],
"status": "success", // 页面处理状态,success表示成功
"height": 1684, // 页面高度
"structured": [
{
"pos": [278, 244, 967, 242, 967, 293, 278, 295], // 结构化内容的位置坐标
"type": "textblock", // 结构化内容类型,textblock表示文本块
"id": 0, // 结构化内容ID
"content": [0], // 关联的content数组索引
"text": "劳动人事争议仲裁申请书", // 结构化文本内容
"outline_level": 0, // 大纲级别,0表示顶级标题
"sub_type": "text_title" // 子类型,text_title表示文本标题
}
// [更多structured条目...]
],
"durations": 459.98861694336, // 页面处理耗时(毫秒)
"image_id": "", // 页面图像ID
"width": 1191 // 页面宽度
}
// [更多pages条目...]
],
"valid_page_number": 5, // 有效页面数量
"total_page_number": 5, // 总页面数量
"total_count": 5, // 总处理数量
"detail": [
{
"paragraph_id": 0, // 段落ID
"page_id": 1, // 所属页面ID
"tags": [], // 标签数组
"outline_level": 0, // 大纲级别
"text": "劳动人事争议仲裁申请书", // 段落文本内容
"type": "paragraph", // 内容类型,paragraph表示段落
"position": [278, 244, 967, 242, 967, 293, 278, 295], // 段落位置坐标
"content": 0, // 关联的content索引
"sub_type": "text_title" // 子类型,text_title表示文本标题
}
// [更多detail条目...]
]
},
"x_request_id": "f36effda6a0141ed0583bea0d596f597", // 请求唯一标识符
"metrics": [
{
"angle": 0, // 页面旋转角度
"status": "success", // 处理状态
"dpi": 144, // 图像DPI值
"image_id": "", // 图像ID
"page_id": 1, // 页面ID
"duration": 464.10571289062, // 处理耗时(毫秒)
"page_image_width": 1191, // 页面图像宽度
"page_image_height": 1684 // 页面图像高度
}
// [更多metrics条目...]
],
"duration": 1459, // 引擎耗时(毫秒)
"message": "success", // 响应消息
"version": "3.17.12" // 引擎版本号
}
```
#### parse\_mode 为 lite 时的返回结构
```json theme={null}
{
"code": 200,
"message": "success",
"x_request_id": "81017abf0fdd3f63ca5c42872cd09a0b",
"result": {
"success_count": 1,
"elements": [
{
"element_id": "",
"type": "NarrativeText",
"text": "xParse 是一个端到端文档处理 AI 基础设施",
"metadata": {
"page_image_url": "https://web-api.textin.com/ocr_image/external/01a91572ca81092c.jpg",
"original_image_url": "",
"angle": 0,
"page_number": 1,
"page_width": 600,
"page_height": 800,
"coordinates": [0.182222, 0.231623, 0.671734, 0.231643, 0.671744, 0.273255, 0.182266, 0.273211],
"is_continue": false,
"category_depth": -1,
"parent_id": ""
}
},
{
"element_id": "",
"type": "Image",
"text": "椭圆章 ENABLINGTECHNOLOGIES\tGROUP\tOF\t威特立创能科技\t(苏州)有限公司",
"metadata": {
"page_image_url": "https://web-api.textin.com/ocr_image/external/01a91572ca81092c.jpg",
"original_image_url": "",
"angle": 0,
"page_number": 1,
"page_width": 600,
"page_height": 800,
"coordinates": [0.182200, 0.231600, 0.671700, 0.231600, 0.671700, 0.273200, 0.182200, 0.273200],
"is_continue": false,
"category_depth": -1,
"sub_type": "stamp",
"image_url": "https://web-api.textin.com/ocr_image/external/e47f8aed69ccabce.jpg",
"image_base64": ""
}
},
{
"element_id": "",
"type": "Table",
"text": "",
"metadata": {
"page_image_url": "https://web-api.textin.com/ocr_image/external/01a91572ca81092c.jpg",
"original_image_url": "",
"angle": 0,
"page_number": 1,
"page_width": 600,
"page_height": 800,
"coordinates": [0.182200, 0.231600, 0.671700, 0.231600, 0.671700, 0.273200, 0.182200, 0.273200],
"is_continue": false,
"category_depth": -1,
"parent_id": ""
}
}
]
}
}
```
#### Element type 类型说明
当 `parse_mode` 为 `lite` 时,返回的 `elements` 数组中每个 element 的 `type` 字段可能的值如下:
| Element type | 说明 |
| ----------------- | -------------------------- |
| NarrativeText | 除了标题、页眉页脚、图片说明文字列表外的普通段落文字 |
| Title | 章节标题 |
| Table | 表格 |
| TableCaption | 表格标题 |
| Image | 图片 |
| FigureCaption | 图片标题 |
| Formula | 公式 |
| Header | 页眉 |
| Footer | 页脚 |
| CodeSnippet | 代码片段 |
| PageNumber | 页码 |
| UncategorizedText | 其他文本 |
#### elements格式转换脚本
如果您需要将 `elements` 格式转换为统一的 `detail`/`pages` 格式,可以使用以下 Python 转换脚本:
```python expandable theme={null}
def convert_elements_to_legacy_format(elements_result):
"""
将 elements 格式转换为原有的 detail/pages 格式
Args:
elements_result: parse_mode 为 lite 时返回的 result 对象,包含 success_count 和 elements
Returns:
转换后的结果,包含 detail 和 pages 结构
"""
if not elements_result or 'elements' not in elements_result:
raise ValueError("输入结果不包含 elements 字段")
elements = elements_result.get('elements', [])
success_count = elements_result.get('success_count', 0)
# 按页码分组 elements
pages_dict = {}
detail_list = []
paragraph_id_counter = 0
# 用于生成 markdown:收集所有 text 和 is_continue 信息
markdown_parts = []
for idx, element in enumerate(elements):
if not element or 'metadata' not in element:
continue
metadata = element.get('metadata', {})
page_number = metadata.get('page_number', 1)
element_type = element.get('type', '')
text = element.get('text', '')
is_continue = metadata.get('is_continue', False)
coordinates = metadata.get('coordinates', [])
category_depth = metadata.get('category_depth', -1)
parent_id = metadata.get('parent_id', '')
sub_type = metadata.get('sub_type', '')
page_width = metadata.get('page_width', 0)
page_height = metadata.get('page_height', 0)
angle = metadata.get('angle', 0)
page_image_url = metadata.get('page_image_url', '')
original_image_url = metadata.get('original_image_url', '')
image_url = metadata.get('image_url', '')
image_base64 = metadata.get('image_base64', '')
# 初始化页面数据
if page_number not in pages_dict:
pages_dict[page_number] = {
'page_id': page_number,
'status': 'success',
'width': page_width,
'height': page_height,
'angle': angle,
'image_id': '',
'content': [],
'structured': [],
'durations': 0.0
}
page_data = pages_dict[page_number]
# 转换坐标:从归一化坐标转换为像素坐标
# coordinates 是归一化的 [x1, y1, x2, y2, x3, y3, x4, y4]
position = []
if len(coordinates) >= 8 and page_width > 0 and page_height > 0:
for i in range(0, 8, 2):
x = int(coordinates[i] * page_width)
y = int(coordinates[i + 1] * page_height)
position.extend([x, y])
else:
position = [0, 0, 0, 0, 0, 0, 0, 0]
# 创建 detail 条目
detail_item = {
'paragraph_id': paragraph_id_counter,
'page_id': page_number,
'outline_level': category_depth,
'text': text,
'position': position,
'type': '',
'sub_type': '',
'content': 0
}
# 根据 element type 映射到 detail 的 type 和 sub_type
type_mapping = {
'NarrativeText': ('paragraph', 'text'),
'Title': ('paragraph', 'text_title'),
'Table': ('table', 'bordered'),
'TableCaption': ('paragraph', 'table_title'),
'Image': ('image', sub_type if sub_type else ''),
'FigureCaption': ('paragraph', 'image_title'),
'Formula': ('paragraph', 'text'),
'Header': ('paragraph', 'header'),
'Footer': ('paragraph', 'footer'),
'CodeSnippet': ('paragraph', 'text'),
'PageNumber': ('paragraph', 'text'),
'UncategorizedText': ('paragraph', 'text')
}
detail_type, detail_sub_type = type_mapping.get(element_type, ('paragraph', 'text'))
detail_item['type'] = detail_type
detail_item['sub_type'] = detail_sub_type
# 处理图片相关字段
if element_type == 'Image' and image_url:
detail_item['image_url'] = image_url
if element_type == 'Image' and image_base64:
detail_item['image_base64'] = image_base64
detail_list.append(detail_item)
# 创建 content 条目(文本行)
content_id = len(page_data['content'])
content_item = {
'id': content_id,
'type': 'line',
'text': text,
'pos': position,
'angle': angle,
'score': 1.0
}
page_data['content'].append(content_item)
# 创建 structured 条目
structured_item = {
'type': 'textblock' if detail_type == 'paragraph' else detail_type,
'pos': position,
'content': [content_id],
'text': text,
'outline_level': category_depth
}
if detail_sub_type:
structured_item['sub_type'] = detail_sub_type
if detail_type == 'table':
structured_item['rows'] = 1
structured_item['cols'] = 1
structured_item['columns_width'] = [position[2] - position[0]] if len(position) >= 4 else [100]
structured_item['rows_height'] = [position[5] - position[1]] if len(position) >= 6 else [50]
structured_item['cells'] = []
if detail_type == 'image':
structured_item['lines'] = [content_id]
structured_item['content'] = [content_id]
page_data['structured'].append(structured_item)
# 收集 markdown 内容
markdown_parts.append({
'text': text,
'is_continue': is_continue
})
paragraph_id_counter += 1
# 生成 markdown:根据 is_continue 决定拼接方式
markdown_lines = []
for idx, part in enumerate(markdown_parts):
if idx == 0:
# 第一个元素直接添加
markdown_lines.append(part['text'])
else:
# 如果前一个元素 is_continue=True,直接拼接;否则用换行符拼接
prev_is_continue = markdown_parts[idx - 1]['is_continue']
if prev_is_continue:
# 直接拼接(追加到最后一个元素)
markdown_lines[-1] += part['text']
else:
# 用换行符拼接
markdown_lines.append(part['text'])
markdown = '\n'.join(markdown_lines)
# 构建最终结果
pages_list = [pages_dict[page_num] for page_num in sorted(pages_dict.keys())]
result = {
'markdown': markdown, # 由 elements 中的 text 拼接而成
'detail': detail_list,
'pages': pages_list,
'valid_page_number': success_count,
'total_page_number': len(pages_dict),
'success_count': success_count
}
return result
# 使用示例
if __name__ == "__main__":
# 示例:从 API 响应中提取 result
api_response = {
"code": 200,
"message": "success",
"result": {
"success_count": 1,
"elements": [
{
"element_id": "",
"type": "NarrativeText",
"text": "xParse 是一个端到端文档处理 AI 基础设施",
"metadata": {
"page_image_url": "https://web-api.textin.com/ocr_image/external/01a91572ca81092c.jpg",
"original_image_url": "",
"angle": 0,
"page_number": 1,
"page_width": 600,
"page_height": 800,
"coordinates": [0.182200, 0.231600, 0.671700, 0.231600, 0.671700, 0.273200, 0.182200, 0.273200],
"is_continue": False,
"category_depth": -1,
"parent_id": ""
}
}
]
}
}
# 转换格式
try:
converted_result = convert_elements_to_legacy_format(api_response['result'])
print("转换成功!")
print(f"Detail 条目数: {len(converted_result['detail'])}")
print(f"Pages 条目数: {len(converted_result['pages'])}")
except Exception as e:
print(f"转换失败: {e}")
```
### 错误码说明
| **错误码** | **描述** |
| :------ | :------------------------------------------------------------------- |
| 40101 | x-ti-app-id 或 x-ti-secret-code 为空 |
| 40102 | x-ti-app-id 或 x-ti-secret-code 无效,验证失败 |
| 40103 | 客户端IP不在白名单 |
| 40003 | 余额不足,请充值后再使用 |
| 40004 | 参数错误,请查看技术文档,检查传参 |
| 40007 | 机器人不存在或未发布 |
| 40008 | 机器人未开通,请至市场开通后重试 |
| 40301 | 图片类型不支持 |
| 40302 | 上传文件大小不符,文件大小不超过 500M |
| 40303 | 文件类型不支持,接口会返回实际检测到的文件类型,如“当前文件类型为.gif” |
| 40304 | 图片尺寸不符,长宽比小于2的图片宽高需在20~20000像素范围内,其他图片的宽高需在20~10000像素范围内 |
| 40305 | 识别文件未上传 |
| 40422 | 文件损坏(The file is corrupted.) |
| 40423 | PDF密码错误(Password required or incorrect password.) |
| 40424 | 页数设置超出文件范围(Page number out of range.) |
| 40425 | 文件格式不支持(The input file format is not supported.) |
| 40427 | DPI参数不在支持列表中(Input DPI is not in the allowed DPIs list(72,144,216).) |
| 40428 | word和ppt转pdf失败或者超时(Process office file failed.) |
| 50207 | 部分页面解析失败(Partial failed) |
| 40400 | 无效的请求链接,请检查链接是否正确 |
| 30203 | 基础服务故障,请稍后重试 |
| 500 | 服务器内部错误 |
### 示例代码下载
我们提供了完整的多语言示例代码包,助您10s跑通接口示例,[点击下载](https://static.textin.com/docs/%E9%80%9A%E7%94%A8%E6%96%87%E6%A1%A3%E8%A7%A3%E6%9E%90-%E7%A4%BA%E4%BE%8B%E4%BB%A3%E7%A0%81.zip?version=1)。
# 使用手册
Source: https://docs.textin.com/xparse/product-manual
智能文档解析产品使用手册,在线快速体验感受能力效果
我们提供了一个[在线的Web平台](https://www.textin.com/console/recognition/robot_markdown?service=pdf_to_markdown),您可以通过浏览器直接使用,无需编写任何代码即可快速试用我们的API并感受效果。
### 文档解析
您可以点击预存的示例文档,也可以自行上传文档(如发票、表格或报告等)在右侧快速查看解析结果并与原文档进行对照;可以切换查看JSON格式输出以及特定元素解析结果,同时也支持您对解析结果进行编辑、复制、导出等操作。
请注意:预存示例文档的解析是免费的,而您自行上传文档进行解析需要消耗页数额度。
![Manual 1 PN]() 参数会影响文档的解析结果和JSON输出内容;我们为您提供了可视化的配置选项,同时也已经为您预先配好了一些参数,您可以根据实际使用需求自定义这些参数;当参数配置保存后,您可以重新解析文档以获取最新结果。
![Manual 2 PN]() 如果您想要快速接入API并集成到您的系统中,我们提供了快捷的代码生成功能,它会基于当前的参数配置生成示例代码,您可以点击按钮下载,并根据您的实际需要进行后续的编辑和应用。
![Manual 3 Pn]()
![Manual 4 Pn]() 如果您想要将文档解析API接入到您的应用系统和流程中,您可以从[这里](/xparse/parse-quickstart)快速开始您的工作!
### **文档抽取**
除了文档解析外,我们还提供了文档智能抽取功能,可以从文档中提取您指定的数据。如果您需要从多个文档中提取结构化信息,例如:您想要提取发票中的信息,以便于完成财务报销流程自动化和提效;这个功能会非常有用!
在[Web平台](https://www.textin.com/console/recognition/robot_markdown?service=pdf_to_markdown)中,您可以在右侧面板中切换至「智能抽取」对文档进行结构化信息提取。
**智能抽取支持2种配置模式,可以切换使用。**
* **prompt模式**:您可以输入想提取的内容,系统会根据您的prompt要求提取相应信息,并以JSON格式输出。
让结构更稳定的要点:
* 有明确的字段信息,如“交易金额、签约日期”等
* 对字段增加简单的描述,如“交易金额(小写数字)、签约日期(以yy-mm-dd表示)”
* 指定输出格式,如“\[ 日期: \[明细1: ]“
* 提供明确的结构化示例
![Manual Prompt Pn]() * **字段模式**:您可以自定义添加要抽取的文本字段或表格表头,系统会根据字段进行抽取;您可以直接查看字段和表头的抽取结果,也可以切换至JSON格式查看输出。文本字段和表格表头的抽取字段数量总计不超过100个。
定义要提取的数据时,您需要为每个字段提供一个名称,您还可以添加可选的描述以提供更多上下文。名称和描述均会作为抽取的指导因素,帮助系统更准确的了解需要从文档中查找和提取哪些信息。字段名称和描述越具体、越清晰,系统就越能够准确地识别和抽取文档中的正确数据。
![Manual 5 Pn]() 请注意:文档智能抽取在API中支持最大不超过100页的文档,超出部分的文档信息将被忽略;而在Web平台使用时,为了能够让您更快感受效果,支持最大不超过20页的文档。
在线Web平台旨在帮助您快速了解智能文档解析可以做什么,以及使用您自行上传的文档感受效果。它往往不直接应用于大范围生产,更适合小规模的测试和体验。
要全面的解析文档或对文档做提取转换处理以及集成到您的系统中,请使用我们的[文档解析](/api-reference/endpoint/parse)和[文档抽取](/api-reference/endpoint/extract)API。
[文档抽取](/api-reference/endpoint/extract)与[文档解析](/api-reference/endpoint/parse)是2个独立的API,您可以根据自身业务和应用需求,选择合适的API。
# Schema 版本迁移指南
Source: https://docs.textin.com/xparse/schema-migration
了解 Schema 版本差异,选择合适版本,以及如何平滑迁移到新版本
为了支持单元格内输出多个图片的能力,我们升级了 Table 结构的 Schema。本指南帮助你理解版本差异,选择合适的版本,以及平滑迁移到新版本。
***
## 版本说明
### v1.3.0(旧版)— 单图支持
* **发布时间**:原始版本
* **特点**:单元格只返回第一个图片
* **字段**:`image_data`(单对象)
* **支持状态**:✅ 长期支持(不计划下线)
### v1.3.1(新版)— 多图支持
* **发布时间**:2026-06-03
* **特点**:单元格支持返回多个图片
* **字段**:`image_datas`(数组)
* **支持状态**:✅ 推荐使用
**重点**:两个版本会长期共存,你可以根据业务需要选择。
***
## 如何选择版本
### 使用 v1.3.1(推荐)
如果你需要:
* ✅ 在一个单元格中获取多张图片
* ✅ 获取最新的特性和改进
* ✅ 享受更好的向前兼容性
### 保持使用 v1.3.0
如果你:
* ✅ 现有系统只需要单元格中的第一张图片
* ✅ 暂时不想修改代码
* ✅ 需要确保返回格式向后兼容
***
## 版本对比
### Schema 结构变化
```
v1.3.0(旧版)
├── cells[]
│ └── image_data (Object)
│ ├── image_url
│ └── mime_type
v1.3.1(新版)
├── cells[]
│ └── image_datas[] (Array)
│ └── [0..N]
│ ├── image_url
│ └── mime_type
```
### 具体示例对比
```json theme={null}
{
"cells": [
{
"row": 0,
"col": 0,
"text": "Product Name",
"image_data": {
"image_url": "https://webapi.textin.com/ocr_image/external/644a750608ccd302.jpg",
"mime_type": "image/jpeg"
}
}
]
}
```
```json theme={null}
{
"cells": [
{
"row": 0,
"col": 0,
"text": "Product Name",
"image_datas": [
{
"image_url": "https://webapi.textin.com/ocr_image/external/644a750608ccd302.jpg",
"mime_type": "image/jpeg"
},
{
"image_url": "https://webapi.textin.com/ocr_image/external/644a750608ccd303.jpg",
"mime_type": "image/jpeg"
}
]
}
]
}
```
### 关键差异
| 方面 | v1.3.0 | v1.3.1 |
| ------- | ------------- | -------------- |
| 字段名 | `image_data` | `image_datas` |
| 数据类型 | Object | Array |
| 单元格图片数量 | 最多 1 张 | 多张 |
| 无图片时 | 字段存在,为 `null` | 字段存在,为空数组 `[]` |
***
## 迁移步骤
### 1. 检查当前版本
查看你的代码中如何访问图片数据:
```python theme={null}
# 如果你的代码这样写,说明使用的是 v1.3.0
cell_image = cell.get('image_data')
if cell_image:
url = cell_image['image_url']
```
### 2. 保留在 v1.3.0
修改 API 请求,添加 `schema_version` 参数:
```python theme={null}
import requests
response = requests.post(
'https://api.textin.com/ocr/parse',
json={
'file_url': 'https://example.com/document.pdf',
'schema_version': '1.3.0' # 指定版本
}
)
result = response.json()
```
### 3. 更新数据处理代码
```python theme={null}
for cell in result['cells']:
if 'image_data' in cell and cell['image_data']:
image_url = cell['image_data']['image_url']
process_image(image_url)
```
```python theme={null}
for cell in result['cells']:
if 'image_datas' in cell:
for image_data in cell['image_datas']:
image_url = image_data['image_url']
process_image(image_url)
```
### 4. 测试验证
* ☐ 使用包含多个图片的测试表格验证
* ☐ 确认能获取到所有图片 URL
* ☐ 检查无图片单元格的处理逻辑
* ☐ 运行现有测试套件确保兼容性
***
## 代码示例
### Python
```python theme={null}
def extract_cell_images(cell, schema_version='1.3.1'):
"""从单元格中提取所有图片 URL"""
if schema_version == '1.3.1':
image_datas = cell.get('image_datas', [])
return [img['image_url'] for img in image_datas]
elif schema_version == '1.3.0':
image_data = cell.get('image_data')
if image_data:
return [image_data['image_url']]
return []
raise ValueError(f"Unsupported schema_version: {schema_version}")
# 使用示例
response = call_api(schema_version='1.3.1')
for cell in response['cells']:
images = extract_cell_images(cell, schema_version='1.3.1')
print(f"单元格 ({cell['row']}, {cell['col']}) 包含 {len(images)} 张图片")
```
### JavaScript
```javascript theme={null}
function extractCellImages(cell, schemaVersion = '1.3.1') {
if (schemaVersion === '1.3.1') {
return (cell.image_datas || []).map(img => img.image_url);
}
if (schemaVersion === '1.3.0') {
return cell.image_data ? [cell.image_data.image_url] : [];
}
throw new Error(`Unsupported schema_version: ${schemaVersion}`);
}
// 使用示例
const response = await callApi({ schema_version: '1.3.1' });
response.cells.forEach(cell => {
const images = extractCellImages(cell, '1.3.1');
console.log(`单元格 (${cell.row}, ${cell.col}) 包含 ${images.length} 张图片`);
});
```
***
## 常见问题
**A:** 如果不指定 `schema_version`,API 默认返回 **v1.3.1**(最新版本)。
**A:** 暂时不计划下线 v1.3.0,我们会长期支持两个版本。如有变化会提前通知。
**A:** 不能。一个 API 请求只能指定一个 `schema_version`,整个响应都遵循该版本的格式。
**v1.3.0**
```python theme={null}
image_data = cell.get('image_data')
if image_data is None:
print("该单元格无图片")
```
**v1.3.1**
```python theme={null}
image_datas = cell.get('image_datas', [])
if not image_datas:
print("该单元格无图片")
```
**A:** 不会。指定 `schema_version=1.3.0` 的请求永远返回 v1.3.0 格式,保证向后兼容。
**A:** 通过检查单元格中是否存在 `image_data` 或 `image_datas` 字段:
* 有 `image_data`(Object)→ v1.3.0
* 有 `image_datas`(Array)→ v1.3.1
**A:** 返回 400 Bad Request 错误,错误信息会说明支持的版本列表。
```json theme={null}
{
"code": 400,
"message": "Invalid schema_version: 1.2.0. Supported versions: 1.3.0, 1.3.1"
}
```
***
## 迁移时间表
| 阶段 | 时间 | 内容 |
| -- | ------------- | -------------------- |
| 发布 | 2026-06-10 | v1.3.1 版本发布 |
| 过渡 | 2026-06-10 \~ | v1.3.0 和 v1.3.1 并行支持 |
| 下线 | 待定 | 如计划下线 v1.3.0 会提前通知 |
***
## 相关链接
5 分钟完成第一次文档解析
了解如何配置 schema\_version 参数
完整的返回数据结构说明
完整的 API 参数与响应 Schema
***
## 支持与反馈
遇到问题或需要帮助?
* 📧 技术支持:[support@textin.com](mailto:support@textin.com)
* 🐛 问题反馈:[GitHub Issues](https://github.com/textin/issues)
如有任何问题或遇到迁移困难,欢迎随时联系我们!
# CLI
Source: https://docs.textin.com/xparse/v1/cli
提供可直接复制运行的命令行工具,快速将 xParse 文档解析能力集成到开发环境中
基于 TextIn xParse API 的命令行工具,支持 PDF、图片、Office 文档等 20+ 种格式转换为 Markdown 及结构化数据。
## 一键安装
**Linux / macOS**
```bash theme={null}
source <(curl -fsSL https://dllf.intsig.net/download/2026/Solution/xparse-cli/install.sh)
```
**Windows (PowerShell)**
```powershell theme={null}
irm https://dllf.intsig.net/download/2026/Solution/xparse-cli/install.ps1 | iex
```
## 快速开始
### 1. 零配置解析(免登录, 每日 1000 页)
```bash theme={null}
# 输出 Markdown 到终端
xparse-cli parse report.pdf
# JSON 视图
xparse-cli parse report.pdf --view json
# 保存到目录
xparse-cli parse report.pdf --output ./output/
# 指定页码范围
xparse-cli parse report.pdf --page-range "1-5"
# 加密 PDF
xparse-cli parse secret.pdf --password mypassword
```
### 2. 付费 API(可选,支持更多格式和高级选项)
前往 [TextIn 控制台](https://www.textin.com/user/login?redirect=%252Fconsole%252Fdashboard%252Fsetting\&from=xparse-parse-skill) 获取凭证(`x-ti-app-id` 和 `x-ti-secret-code`),然后运行:
```bash theme={null}
xparse-cli auth
```
按提示输入 App ID 和 Secret Code,凭证将保存至 `~/.xparse-cli/config.yaml`。
也可通过环境变量配置(适合 CI/CD):
```bash theme={null}
export XPARSE_APP_ID=your_app_id
export XPARSE_SECRET_CODE=your_secret_code
```
```bash theme={null}
# 显式使用付费 API
xparse-cli parse report.pdf --api paid
```
## 命令一览
| 命令 | 说明 |
| --------------------- | ------------------------------- |
| `xparse-cli parse` | 解析文档,输出 Markdown / JSON |
| `xparse-cli auth` | 配置 API 凭证(交互式) |
| `xparse-cli config` | 管理配置(show / set / reset / path) |
| `xparse-cli download` | 下载解析结果中 elements 的图片 |
| `xparse-cli update` | 自更新 CLI 到最新版本 |
| `xparse-cli version` | 显示版本信息 |
## parse 命令参数
| 参数 | 默认值 | 说明 |
| --------------------------- | ---------- | ------------------------------------- |
| `--api` | *(auto)* | API 模式:`free`、`paid` |
| `--include-char-details` | `false` | 返回字符级详细信息 |
| `--include-hierarchy` | `true` | 返回元素间的层级与关联字段 |
| `--include-image-data` | `true` | 返回图片数据(URL、MIME 类型、Base64) |
| `--include-inline-objects` | `true` | 返回细粒度的行内对象(公式、手写、复选框、内嵌图片) |
| `--include-pages` | `true` | 返回页面元信息列表 |
| `--include-table-structure` | `true` | 返回表格的详细结构化信息 |
| `--include-title-tree` | `true` | 返回标题树(目录) |
| `--list` | | 从文件读取输入列表(每行一个路径),需配合 `--output` |
| `--output` | *(stdout)* | 输出文件路径或目录;省略则输出到终端 |
| `--page-range` | | 页码范围,例如 `"1-5"` 或 `"1-2,5-10"` |
| `--password` | | 加密文档密码 |
| `--table-view` | `html` | 表格在 Markdown 中的表达格式:`html`、`markdown` |
| `--view` | `markdown` | 输出视图:`markdown`、`json` |
**全局参数(所有命令均支持):**
| 参数 | 说明 |
| --------------- | ------------------------------- |
| `--app-id` | Textin App ID(覆盖环境变量和配置文件) |
| `--secret-code` | Textin Secret Code(覆盖环境变量和配置文件) |
| `--base-url` | API 地址(私有化部署时使用) |
| `--verbose` | 调试模式,打印 HTTP 请求详情 |
### API capabilities 默认值
CLI 默认开启以下能力,Agent 无需额外配置:
| 能力 | 默认 |
| ---------- | ----------------------------------- |
| 标题层级 | 开启 |
| 内嵌对象(图片) | 开启 |
| 图片数据 | 开启 |
| 表格结构(HTML) | 开启 |
| 分页结果 | 开启 |
| 目录树 | 开启 |
| 字符级详情 | **关闭**(`--include-char-details` 开启) |
## 使用示例
### 管道组合
```bash theme={null}
# 解析并搜索
xparse-cli parse report.pdf | grep "revenue"
# 解析并喂给 LLM
xparse-cli parse paper.pdf | llm "summarize this paper"
```
### 批量处理
```bash theme={null}
# 从文件列表读取
xparse-cli parse --list files.txt --output ./results/
```
### 下载图片
```bash theme={null}
# 从解析结果 JSON 中提取 elements 图片并下载
xparse-cli download --from result.json --output ./images/
# 直接下载图片 URL
xparse-cli download https://web-api.textin.com/ocr_image/external/abc123.jpg --output ./images/
```
## 凭证管理
| 优先级 | 方式 | 说明 |
| --- | ----- | -------------------------------------- |
| 1 | 命令行参数 | `--app-id` 和 `--secret-code` |
| 2 | 环境变量 | `XPARSE_APP_ID` 和 `XPARSE_SECRET_CODE` |
| 3 | 配置文件 | `~/.xparse-cli/config.yaml` |
## 支持的文件格式
| 类型 | 格式 |
| -- | ------------------------------- |
| 文档 | PDF, DOC, DOCX, TXT, RTF, OFD |
| 图片 | PNG, JPG, JPEG, BMP, TIFF, WebP |
| 表格 | XLS, XLSX, CSV |
| 演示 | PPT, PPTX |
| 网页 | HTML, MHTML |
限制:
| 限制项 | 免费 API | 付费 API |
| ------------ | ----------- | ------------------------ |
| 文件大小 | 10MB | 500MB |
| 页数 | 1000 页/日 | — |
| XLS/XLSX/CSV | — | 每 sheet ≤ 2000 行 × 100 列 |
| TXT | — | ≤ 100KB |
| 图片尺寸 | 20~20000 像素 | 20~20000 像素 |
了解更多:[查看 Github](https://github.com/intsig-textin/xparse-skills/tree/main/cli)
# RAG 与 Agent 框架
Source: https://docs.textin.com/xparse/v1/ecosystem/rag-agent
与主流 RAG 框架深度集成,为知识库提供高质量的结构化数据
通过 XParseLoader 将 xParse 强大文档解析能力无缝集成到 LangChain 应用中
[GitHub 地址](https://github.com/intsig-textin/langchain-xparse) · [PyPI 地址](https://pypi.org/project/langchain-xparse/)
xParse 与 Dify 联合研发的插件已在 Dify 市场上架,帮助用户搭建工作流,提供强大的文档解析和处理能力
[插件地址](https://marketplace.dify.ai/plugins/intsig-textin/xparse)
深度集成 RAGFlow 流程,提供强大的非结构化数据解析支持,助力构建精准的检索增强生成应用
[GitHub 地址](https://github.com/intsig-textin/xparse-ragflow)
TextIn xParse 插件已上架 Coze 插件市场,支持零代码搭建文档解析工作流。可将 PDF、图片等解析为结构化 Markdown,广泛应用于财报抽取、合同风险解析与知识库构建
[插件地址](https://www.coze.cn/store/plugin/7381354890590814208?from=plugin_card)
已支持:HiAgent、Dify、RagFlow、Langchain、Milvus、Pinecone、Qdrant、pgvector
敬请期待更多框架支持
# Skills & MCP
Source: https://docs.textin.com/xparse/v1/ecosystem/skills-mcp
为各类 AI Agent 框架提供标准化的文档解析能力封装,无需编写解析代码,Agent 通过自然语言即可调用
## Skills 资源与下载
开源代码仓库,查看完整源码和文档
官方托管平台,一键安装和部署
国内加速访问,提供稳定的镜像服务
ModelScope 技能市场
## 官方平台集成
在 OpenClaw、Claude Code 等 Agent 平台装上 xparse-parser Skill,只需要说一句话,它就能自动完成文档解析、格式转换全部流程。
**通过各类 Agent 或 Claw 安装**
在 Agent 对话框直接说:
```
1. 帮我从技能市场安装 intsig-textin/xparse-parser
2. 如果技能市场里没有,则通过 npx 安装:
npx skills add intsig-textin/xparse-skills --yes
3. 如果 npx 也没有,则可以从以下仓库里任选一个手动安装:
https://github.com/intsig-textin/xparse-skills
https://gitee.com/intsig-textin/xparse-skills
```
作为 OpenClaw SDK 官方签名的文档解析插件,已纳入主流 Node.js Agent 框架的推荐工具链
面向低代码及零代码 Agent 框架的轻量化解析 Skill,无需编写解析代码即可实现多格式文档的结构化信息抽取
嵌入式 Agent 场景下的最小解析单元,以微内核架构实现 PDF、DOCX 等文档的高效结构化抽取
Node.js 生态中轻量却不失完整的解析插件,为资源受限环境提供与 OpenClaw 同源的文档处理能力
专为边缘计算和函数计算场景裁剪的超轻量解析器,在百 KB 级体积内完成多格式文档的标准化输出
飞书原生 Agent 平台的官方解析插件,深度集成于飞书 aily 技能体系,让 Agent 像读取普通文本一样解析 PDF、PPT 与 DOCX 文档
腾讯官方出品的个人 AI 助手,已内置 TextIn 解析技能。用户通过自然语言即可让 QClaw 理解任意文档
钉钉"悟空"平台的内置解析技能,无需额外集成,Agent 开箱即用,具备企业级多格式文档理解能力
## MCP Server
实现大模型客户端与 TextIn 解析引擎的标准化通信,让模型能够"看懂"任意格式文档。TextIn 提供两种接入方式:**远程 MCP Server(HTTP,推荐)** 和 **本地 MCP Server(npx)**,可按需选择。
### 远程 MCP Server(HTTP,推荐)
官方托管的远程 MCP Server,云端运行,无需本地安装 Node 环境,支持标准 OAuth 2.1 认证。
**通过 Claude Code 一键添加**
```bash theme={null}
claude mcp add --scope user --transport http xparse-mcp https://api.textin.com/xparse-mcp
```
**手动配置**
在 MCP 客户端配置文件中添加,默认使用标准 OAuth 2.1 协议进行认证:
```json theme={null}
{
"xparse-mcp": {
"type": "http",
"url": "https://api.textin.com/xparse-mcp"
}
}
```
也可以手动指定 `x-ti-app-id` / `x-ti-secret-code` 进行认证(按[文档说明](/xparse/api-key)获取 APP\_ID 与 APP\_SECRET):
```json theme={null}
{
"xparse-mcp": {
"type": "http",
"url": "https://api.textin.com/xparse-mcp",
"headers": {
"x-ti-app-id": "你的真实APP_ID",
"x-ti-secret-code": "你的真实APP_SECRET"
}
}
}
```
### 本地 MCP Server(npx)
本地运行版本,通过 `npx` 启动,使用环境变量传入凭证。按照[文档说明](/xparse/api-key)获取 APP\_ID 与 APP\_SECRET,然后配置 MCP Server:
```json theme={null}
{
"mcpServers": {
"textin-ocr": {
"command": "npx",
"args": [
"-y",
"@intsig/server-textin"
],
"env": {
"APP_ID": "你的真实APP_ID",
"APP_SECRET": "你的真实APP_SECRET",
"MCP_SERVER_REQUEST_TIMEOUT": "600000"
},
"timeout": 600
}
}
}
```
了解更多:[查看 GitHub](https://github.com/intsig-textin/textin-mcp)
# 前端可视化
Source: https://docs.textin.com/xparse/v1/open-source/visualizer
xParse 提供的开源前端可视化 SDK,用于文档解析、分Chunk等场景结果溯源
[@xparse-kit/visualizer](https://github.com/intsig-textin/xparse-kit/tree/master/packages/visualizer) 是 xParse 提供的开源前端可视化 SDK,用于在浏览器中可视化文档解析、分块等场景的处理结果。通过该 SDK,您可以:
* **可视化文档元素**:在原始文档页面上显示解析出的元素位置和类型
* **结果溯源**:快速定位检索结果在原始文档中的位置
* **交互式浏览**:支持缩放、旋转、页面导航等操作
* **高亮显示**:支持高亮显示选中的元素,便于人工审查
## 快速体验
我们提供了一个可以直接运行的 [demo 示例代码](https://github.com/intsig-textin/xparse-kit/blob/master/packages/visualizer/docs/examples),您可以根据提示运行 demo,体验可视化的功能和效果。

## 快速开始
### 安装
```bash theme={null}
npm install @xparse-kit/visualizer
# 或
pnpm add @xparse-kit/visualizer
# 或
yarn add @xparse-kit/visualizer
```
### 基础示例
```typescript theme={null}
import { createSvgMark } from '@xparse-kit/visualizer';
import type { PageItem } from '@xparse-kit/visualizer';
// 准备页面数据
const pageList: PageItem[] = [
{
url: 'https://example.com/page1.jpg', // 页面图片地址
width: 1225,
height: 1718,
angle: 0,
blockList: [
{
id: 'block-1',
page: 1,
angle: 0,
blockStyle: {
fill: 'rgba(59, 130, 246, 0.15)', // 坐标框填充
stroke: '#3b82f6', // 坐标框边界线颜色
'stroke-width': 2.5, // 坐标框边界线宽度
},
text: '示例文本',
position: [0.1, 0.1, 0.5, 0.1, 0.5, 0.3, 0.1, 0.3], // 相对坐标(0-1之间)
type: 'Title',
meta: { type: 'Title' },
attrs: {},
},
],
},
];
// 创建实例
const instance = createSvgMark({
container: '#app',
pageList,
showTypeTag: true,
});
```
## 使用示例
### 将 xParse 返回数据转换为 SDK 需要的格式
xParse Parse API 返回的数据格式可以直接使用,因为 `coordinates` 字段已经是相对坐标(0-1 之间)。您只需要将 API 返回的元素数据转换为 SDK 所需的 `PageItem` 格式:
```typescript theme={null}
import { createSvgMark } from '@xparse-kit/visualizer';
import type { PageItem, BlockItem } from '@xparse-kit/visualizer';
// xParse Parse API 返回的元素类型
interface XParseElement {
element_id: string;
type: string;
text: string;
metadata: {
page_number: number;
page_width: number;
page_height: number;
page_image_url?: string;
coordinates: number[]; // 相对坐标,已经是 0-1 之间
};
}
// 将 xParse Pipeline 数据转换为 SDK 格式
function transformXParseDataToSvgMarkData(
elements: XParseElement[],
themeStyles?: Record
): PageItem[] {
const pageMap = new Map();
// 默认样式主题
const defaultStyles = {
Title: {
fill: 'rgba(59, 130, 246, 0.15)',
stroke: '#3b82f6',
'stroke-width': 2.5,
},
NarrativeText: {
fill: 'rgba(34, 197, 94, 0.15)',
stroke: '#22c55e',
'stroke-width': 2,
},
Table: {
fill: 'rgba(168, 85, 247, 0.15)',
stroke: '#a855f7',
'stroke-width': 2,
},
Image: {
fill: 'rgba(251, 146, 60, 0.15)',
stroke: '#fb923c',
'stroke-width': 2,
},
default: {
fill: 'rgba(156, 163, 175, 0.15)',
stroke: '#9ca3af',
'stroke-width': 2,
},
};
const styles = themeStyles || defaultStyles;
elements.forEach((element) => {
const { metadata, element_id, type, text } = element;
const pageNumber = metadata.page_number;
const pageWidth = metadata.page_width;
const pageHeight = metadata.page_height;
const url = metadata.page_image_url || '';
const coordinates = metadata.coordinates || [];
// 如果坐标数组长度不是 8,跳过该元素
if (coordinates.length !== 8) {
console.warn(`元素 ${element_id} 的坐标格式不正确,已跳过`);
return;
}
// 按页码分组
if (!pageMap.has(pageNumber)) {
pageMap.set(pageNumber, {
pageInfo: {
url,
angle: 0,
width: pageWidth,
height: pageHeight,
},
blocks: [],
});
}
const pageData = pageMap.get(pageNumber)!;
const blockStyle = styles[type] || styles.default;
const blockItem: BlockItem = {
id: element_id,
page: pageNumber,
angle: 0,
blockStyle,
text: text || '',
position: coordinates, // xParse Pipeline 返回的坐标已经是相对坐标,直接使用
type,
meta: {
element_id,
type,
text,
...metadata,
},
attrs: {},
};
pageData.blocks.push(blockItem);
});
// 转换为 PageItem 数组
const pageList = Array.from(pageMap.entries())
.sort(([a], [b]) => a - b)
.map(([, { pageInfo, blocks }]) => ({
...pageInfo,
blockList: blocks,
}));
return pageList;
}
// 使用示例
async function visualizeXParseResults() {
// 假设这是从 xParse Parse API 获取的数据
const xparseElements: XParseElement[] = [
{
element_id: 'element-1',
type: 'Title',
text: '第一章 简介',
metadata: {
page_number: 1,
page_width: 1191,
page_height: 1684,
page_image_url: 'https://example.com/page1.jpg',
coordinates: [0.1008, 0.1069, 0.8228, 0.1069, 0.8228, 0.1425, 0.1008, 0.1425],
},
},
{
element_id: 'element-2',
type: 'NarrativeText',
text: '这是正文内容...',
metadata: {
page_number: 1,
page_width: 1191,
page_height: 1684,
page_image_url: 'https://example.com/page1.jpg',
coordinates: [0.1822, 0.2316, 0.6717, 0.2316, 0.6717, 0.2732, 0.1822, 0.2732],
},
},
];
// 转换为 SDK 格式
const pageList = transformXParseDataToSvgMarkData(xparseElements);
// 创建可视化实例
const instance = createSvgMark({
container: '#app',
pageList,
showTypeTag: true,
onBlockClick: (block) => {
console.log('点击了元素:', block.id);
console.log('元素文本:', block.origin.text);
},
});
return instance;
}
```
### 处理其他数据源的绝对坐标
如果您使用的是其他数据源,且坐标是绝对坐标(像素值),需要先转换为相对坐标:
```typescript theme={null}
/**
* 将绝对坐标转换为相对坐标
* @param absolutePosition 绝对坐标数组 [x1, y1, x2, y2, x3, y3, x4, y4]
* @param imageWidth 图片宽度(像素)
* @param imageHeight 图片高度(像素)
* @returns 相对坐标数组(0-1之间)
*/
function convertAbsoluteToRelative(
absolutePosition: number[],
imageWidth: number,
imageHeight: number
): number[] {
if (absolutePosition.length !== 8) {
throw new Error('坐标数组长度必须为 8');
}
return [
absolutePosition[0] / imageWidth, // x1
absolutePosition[1] / imageHeight, // y1
absolutePosition[2] / imageWidth, // x2
absolutePosition[3] / imageHeight, // y2
absolutePosition[4] / imageWidth, // x3
absolutePosition[5] / imageHeight, // y3
absolutePosition[6] / imageWidth, // x4
absolutePosition[7] / imageHeight, // y4
];
}
// 使用示例
const absoluteCoords = [217, 390, 1336, 390, 1336, 460, 217, 460];
const pageWidth = 1225;
const pageHeight = 1718;
const relativeCoords = convertAbsoluteToRelative(absoluteCoords, pageWidth, pageHeight);
// 结果: [0.1771, 0.2270, 1.0906, 0.2270, 1.0906, 0.2677, 0.1771, 0.2677]
```
### React 集成示例
```tsx theme={null}
import React, { useEffect, useRef } from 'react';
import { createSvgMark } from '@xparse-kit/visualizer';
import type { PageItem } from '@xparse-kit/visualizer';
interface VisualizerProps {
pageList: PageItem[];
}
export const Visualizer: React.FC = ({ pageList }) => {
const containerRef = useRef(null);
const instanceRef = useRef | null>(null);
useEffect(() => {
if (!containerRef.current) return;
instanceRef.current = createSvgMark({
container: containerRef.current,
pageList,
showTypeTag: true,
onBlockClick: (block) => {
console.log('点击了元素:', block.id);
},
onPageChange: (page) => {
console.log('当前页面:', page);
},
});
return () => {
if (instanceRef.current) {
instanceRef.current.destroy();
}
};
}, [pageList]);
return ;
};
```
### Vue 集成示例
```vue theme={null}
```
## 核心功能
### 缩放和旋转
```typescript theme={null}
// 缩放
instance.scaleTo(1.5); // 放大到 150%
instance.scaleTo(1); // 恢复到 100%
// 旋转
instance.rotateTo(90); // 旋转到 90 度
instance.getAngle(); // 获取当前角度
```
### 页面导航
```typescript theme={null}
// 跳转页面
instance.scrollToPage(2);
// 获取当前页面
const currentPage = instance.getCurrentPage();
```
### 标记框管理
```typescript theme={null}
// 高亮显示选中的标记框
instance.setOptions({
activeBlockIds: ['block-1', 'block-2'],
});
// 添加新的标记框
const newBlock: BlockItem = {
id: 'new-block',
page: 1,
angle: 0,
blockStyle: {
fill: 'rgba(255, 0, 0, 0.2)',
stroke: '#ff0000',
'stroke-width': 2,
},
text: '新标记',
position: [0.2, 0.2, 0.6, 0.2, 0.6, 0.4, 0.2, 0.4],
type: 'Custom',
meta: { type: 'Custom' },
attrs: {},
};
const blockInstance = instance.addBlock(newBlock);
```
### 事件监听
```typescript theme={null}
const instance = createSvgMark({
container: '#app',
pageList,
onBlockClick: (block) => {
console.log('点击了标记框:', block.id);
instance.setOptions({ activeBlockIds: [block.id] });
},
onPageChange: (page) => {
console.log('页面变化:', page);
},
onScaleChange: (scale, origin) => {
console.log('缩放变化:', scale);
},
});
```
### 性能优化
对于大量页面的场景,可以使用虚拟列表功能:
```typescript theme={null}
const instance = createSvgMark({
container: '#app',
pageList, // 假设有 100 页
virtual: {
threshold: 3, // 同时加载 3 页
},
overscan: 1, // 提前加载 1 页
});
```
## 数据格式说明
### 坐标格式
SDK 使用的 `position` 字段必须是**相对坐标**(0-1 之间),格式为 `[x1, y1, x2, y2, x3, y3, x4, y4]`,表示四边形的四个顶点坐标:
```
坐标数组: [x1, y1, x2, y2, x3, y3, x4, y4]
↑左上 ↑右上 ↑右下 ↑左下
```
**重要说明**:
* **xParse Parse API 返回的 `coordinates` 字段已经是相对坐标**,可以直接使用,无需转换
* 如果使用其他数据源且坐标是绝对坐标(像素值),需要先转换为相对坐标
### PageItem 格式
```typescript theme={null}
interface PageItem {
url: string; // 页面图片 URL
width: number; // 页面宽度(像素)
height: number; // 页面高度(像素)
angle: number; // 页面旋转角度(0, 90, 180, 270)
blockList?: BlockItem[]; // 页面中的标记框列表
}
```
### BlockItem 格式
```typescript theme={null}
interface BlockItem {
id: string; // 唯一标识
page: number; // 页码(从 1 开始)
angle: number; // 旋转角度
blockStyle: BlockStyle; // 样式配置
text: string; // 文本内容
position: number[]; // 相对坐标数组(0-1之间)
type?: string; // 元素类型
meta: any; // 元信息
attrs: any; // 自定义属性
}
```
## 参考文档
* [使用指南](https://github.com/intsig-textin/xparse-kit/blob/master/packages/visualizer/docs/guide.md) - 完整的使用指南,包括快速开始、基础使用、核心功能和常见问题
* [API 文档](https://github.com/intsig-textin/xparse-kit/blob/master/packages/visualizer/docs/api.md) - 详细的 API 参考,包括所有类型定义、接口方法和配置选项
* [示例代码](https://github.com/intsig-textin/xparse-kit/blob/master/packages/visualizer/docs/examples/README.md) - 真实可运行的示例代码,包含主题切换、交互控制等功能演示
# 解析配置详解
Source: https://docs.textin.com/xparse/v1/parse-config
详细说明文档解析 API 的输入参数配置,包括能力开关、处理范围、高级引擎配置等
文档解析 API 支持通过 `config` 参数自定义解析行为。本文档详细说明所有可用的配置项。
## 配置结构总览
```json theme={null}
{
"document": {
"password": "example-pdf-password"
},
"capabilities": {
"include_hierarchy": true,
"include_inline_objects": false,
"include_char_details": false,
"include_image_data": false,
"include_table_structure": false,
"element_merge_mode": "separate",
"pages": false,
"title_tree": false,
"table_view": "html",
"remove_watermark": false,
"crop_dewarp": false
},
"scope": {
"page_range": "1-5"
},
"config": {
"force_engine": "textin",
"engine_params": {
"parse_mode": "vlm",
"formula_level": 0,
"image_output_type": "url",
"recognize_chemical": true
}
},
"exports": [
{
"format": "docx",
"config": {
"mode": "flow"
}
}
]
}
```
***
## document(文档相关配置)
配置文档本身的处理参数。
```json theme={null}
{
"document": {
"password": "example-pdf-password"
}
}
```
| 字段 | 类型 | 必填 | 说明 |
| ---------- | ------ | -- | -------------------- |
| `password` | string | 否 | 加密文档的密码(如加密的 PDF 文件) |
**使用场景**:
* 处理受密码保护的 PDF 文档
* 确保加密文档能够正常解析
***
## capabilities(解析策略与格式配置)
控制返回数据的详细程度和格式。开启更多能力会增加解析耗时和返回数据量。
### include\_hierarchy
是否返回元素间的层级与关联字段。
| 字段 | 类型 | 默认值 | 说明 |
| ------------------- | ------- | ------ | ---------------------- |
| `include_hierarchy` | boolean | `true` | 开启后,返回元素间的父子关系、引用关系等信息 |
**开启后返回的字段**:
* `parent_id`:父元素 ID
* `children_ids`:子元素 ID 列表
* `ref_element_id`:关联元素 ID(如图片/表格与其标题的关联)
**使用场景**:
* 需要构建文档的结构化关系图谱
* 需要理解元素之间的从属关系
* 需要追踪标题与内容的层级关系
```json theme={null}
{
"capabilities": {
"include_hierarchy": true
}
}
```
### include\_inline\_objects
是否返回细粒度的行内对象。
| 字段 | 类型 | 默认值 | 说明 |
| ------------------------ | ------- | ------- | ---------------------- |
| `include_inline_objects` | boolean | `false` | 开启后,文本类元素会返回其中包含的细粒度对象 |
**支持的行内对象类型**:
* `formula`:数学公式(LaTeX 格式)
* `handwriting`:手写内容
* `checkbox`:复选框
* `image`:内嵌图片
**使用场景**:
* 需要精确定位和提取公式
* 需要识别手写签名或批注
* 需要处理表单中的复选框
* 需要提取文本段落中的内嵌图片
```json theme={null}
{
"capabilities": {
"include_inline_objects": true
}
}
```
**返回示例**:
```json theme={null}
{
"element_id": "el_004",
"type": "NarrativeText",
"text": "设违约金函数 $f(x)=x^2+1$ 。",
"objects": [
{
"object_id": "obj_001",
"type": "formula",
"text": "$f(x)=x^2+1$",
"text_range": [7, 20],
"coordinates": [0.220000, 0.480000, 0.300000, 0.480000, 0.300000, 0.540000, 0.220000, 0.540000],
"metadata": {
"display_mode": "inline"
}
}
]
}
```
### include\_char\_details
是否返回字符级详细信息。
| 字段 | 类型 | 默认值 | 说明 |
| ---------------------- | ------- | ------- | ------------------ |
| `include_char_details` | boolean | `false` | 开启后,返回文本中每个字符的详细信息 |
**返回的字符信息包括**:
* 字符坐标
* 识别置信度
* 候选字符列表
**使用场景**:
* 需要字符级别的精确定位
* 需要评估识别质量
* 需要处理低置信度字符
* 需要实现字符级别的纠错
```json theme={null}
{
"capabilities": {
"include_char_details": true
}
}
```
**返回示例**:
```json theme={null}
{
"char_details": [
{
"index": 0,
"text": "概",
"coordinates": [0.100000, 0.120000, 0.140000, 0.120000, 0.140000, 0.160000, 0.100000, 0.160000],
"recognition": {
"confidence": 0.999,
"candidates": [
{"text": "概", "confidence": 0.999},
{"text": "槪", "confidence": 0.001}
]
}
}
]
}
```
### include\_image\_data
是否返回图片数据。
| 字段 | 类型 | 默认值 | 说明 |
| -------------------- | ------- | ------- | ------------------ |
| `include_image_data` | boolean | `false` | 开启后,图片元素将返回完整的图片数据 |
**返回的图片信息包括**:
* 图片 URL
* MIME 类型
* Base64 编码(可选)
**使用场景**:
* 需要下载或显示文档中的图片
* 需要对图片进行二次处理
* 需要获取图片的 Base64 编码用于嵌入
```json theme={null}
{
"capabilities": {
"include_image_data": true
}
}
```
**返回示例**:
```json theme={null}
{
"element_id": "el_020",
"type": "Image",
"image_data": {
"image_url": "https://example.com/images/xxx.png",
"mime_type": "image/png",
"base64": "iVBORw0KGgoAAAANSUhEUg..."
}
}
```
### include\_table\_structure
是否返回表格的详细结构化信息。
| 字段 | 类型 | 默认值 | 说明 |
| ------------------------- | ------- | ------- | --------------------------------- |
| `include_table_structure` | boolean | `false` | 开启后,以 JSON 格式返回表格的行、列以及每个单元格的详细信息 |
**返回的表格结构包括**:
* 行数和列数
* 每个单元格的位置(行、列)
* 单元格的跨行跨列信息
* 单元格内容类型(文本、公式、图片、混合)
* 单元格坐标
**使用场景**:
* 需要程序化处理表格数据
* 需要提取表格单元格的精确位置
* 需要处理复杂表格(合并单元格)
* 需要识别表格单元格中的公式或图片
```json theme={null}
{
"capabilities": {
"include_table_structure": true
}
}
```
**返回示例**:
```json theme={null}
{
"element_id": "el_010",
"type": "Table",
"table_structure": {
"rows": 2,
"cols": 2,
"cells": [
{
"cell_id": "tbl_001_r1_c1",
"row": 1,
"col": 1,
"row_span": 1,
"col_span": 1,
"content_type": "text",
"text": "姓名",
"coordinates": [0.100000, 0.300000, 0.300000, 0.300000, 0.300000, 0.340000, 0.100000, 0.340000]
}
]
}
}
```
### element\_merge\_mode
控制跨页表格的输出方式:按物理页分别输出,还是合并为一个逻辑表格。
| 字段 | 类型 | 默认值 | 可选值 | 说明 |
| -------------------- | ------ | ---------- | -------------------- | ----------------------------- |
| `element_merge_mode` | string | `separate` | `separate`, `merged` | 控制跨页表格按物理页分别输出,或合并为一个逻辑 Table |
**两种模式的行为**:
* `separate`:每个物理分页分别返回一个 Table 片段(fragment),通过 `metadata.is_continuation` 和 `metadata.continuation_of` 保留跨页续接关系。
* `merged`:同一张逻辑跨页表只返回一个合并后的 Table(Canonical Table),`text` 为完整的表格 HTML,并通过 `source_regions` 记录每个物理页的来源区域。
* 单页表格在两种模式下输出一致。
**使用场景**:
* 需要把跨页表格连续渲染为一张完整表格时,使用 `merged`
* 需要按物理页逐页定位、逐页处理表格片段时,使用 `separate`
```json theme={null}
{
"capabilities": {
"element_merge_mode": "merged"
}
}
```
**与 `include_table_structure` 的组合**:两个参数相互独立,可自由组合。
| `element_merge_mode` | `include_table_structure` | 输出 |
| -------------------- | ------------------------- | ---------------------------------------------------------- |
| `separate` | `false` | 每页一个 Table 片段,不返回单元格结构 |
| `separate` | `true` | 每页一个 Table 片段,各自返回单元格结构 |
| `merged` | `false` | 一个合并后的 Table,返回完整 HTML、`table_layout` 和表级 `source_regions` |
| `merged` | `true` | 一个合并后的 Table,并返回合并后的单元格结构及单元格来源映射 |
`table_view` 只控制 `data.markdown` 中表格的表达格式,不影响 `elements[]` 的跨页输出模式。
### pages
是否返回页面元信息列表。
| 字段 | 类型 | 默认值 | 说明 |
| ------- | ------- | ------- | -------------- |
| `pages` | boolean | `false` | 开启后,返回每一页的详细信息 |
**返回的页面信息包括**:
* 页码
* 页面宽高
* 旋转角度
* 渲染图片地址(`page_image_url`)
* 包含的元素列表(`element_ids`)
* DPI
* 处理状态
**使用场景**:
* 需要按页面组织文档内容
* 需要获取页面的预览图
* 需要了解页面的物理属性(宽高、DPI)
* 需要定位某个元素所在的页面
```json theme={null}
{
"capabilities": {
"pages": true
}
}
```
**返回示例**:
```json theme={null}
{
"pages": [
{
"page_number": 1,
"page_width": 1576,
"page_height": 1683,
"page_image_url": "https://example.com/page-1.jpg",
"element_ids": ["el_001", "el_002", "el_003"],
"dpi": 144,
"angle": 0,
"status": "Success"
}
]
}
```
### title\_tree
是否返回标题树(目录)。
| 字段 | 类型 | 默认值 | 说明 |
| ------------ | ------- | ------- | --------------- |
| `title_tree` | boolean | `false` | 开启后,返回文档的层级目录结构 |
**返回的目录信息包括**:
* 标题文本
* 标题层级(1 为最高级)
* 所在页码
* 嵌套的子标题
**使用场景**:
* 需要生成文档目录导航
* 需要按章节组织内容
* 需要理解文档的大纲结构
```json theme={null}
{
"capabilities": {
"title_tree": true
}
}
```
**返回示例**:
```json theme={null}
{
"title_tree": [
{
"element_id": "el_001",
"title": "第一章 概述",
"level": 1,
"page_number": 1,
"children": [
{
"element_id": "el_005",
"title": "1.1 背景",
"level": 2,
"page_number": 1,
"children": []
}
]
}
]
}
```
### table\_view
表格在 Markdown 中的表达格式。
| 字段 | 类型 | 默认值 | 可选值 | 说明 |
| ------------ | ------ | -------- | ------------------ | ---------------------- |
| `table_view` | string | `"html"` | `markdown`, `html` | 控制 Markdown 字段中表格的渲染格式 |
**格式对比**:
**Markdown 格式**(`table_view: "markdown"`):
```markdown theme={null}
| 姓名 | 年龄 |
|---|---|
| 张三 | 28 |
```
**HTML 格式**(`table_view: "html"`):
```html theme={null}
```
**使用场景**:
* 需要简洁的 Markdown 表格格式
* 需要支持复杂表格结构(合并单元格)时使用 HTML
### **remove\_watermark**(**去水印**)
是否对文档进行去水印预处理。
| 字段 | 类型 | 默认值 | 说明 |
| :----------------- | :------ | :------ | :---------------- |
| `remove_watermark` | boolean | `false` | 开启后,自动检测并去除文档中的水印 |
**使用场景**:
* 去除文档中的水印干扰,提升识别准确率
* 获取无水印的干净解析结果
```json theme={null}
{
"capabilities": {
"remove_watermark": true
}
}
```
### **crop\_dewarp(切边矫正)**
是否对文档进行切边矫正预处理。
| 字段 | 类型 | 默认值 | 说明 |
| :------------ | :------ | :------ | :-------------------- |
| `crop_dewarp` | boolean | `false` | 开启后,自动检测并对文档进行切边矫正预处理 |
**使用场景**:
* 扫描文档存在多余边框或页面倾斜
* 拍照文档存在透视畸变(如书页弯曲)
* 需要获得正向、紧凑的页面图像,提升版面分析质量
```json theme={null}
{
"capabilities": {
"crop_dewarp": true
}
}
```
***
## scope(处理范围控制)
控制解析的页面范围,减少不必要的处理。
```json theme={null}
{
"scope": {
"page_range": "1-5,10-15"
}
}
```
| 字段 | 类型 | 必填 | 说明 |
| ------------ | ------ | -- | ------------------- |
| `page_range` | string | 否 | 页码范围,从 1 开始,支持多个闭区间 |
**格式说明**:
* 单页:`"1"`
* 连续页:`"1-5"`
* 多个区间:`"1-2,3-4,5-10"`
**单文件页数限制说明**
当文件页数超过请求限制时,API 将返回错误。请参考以下限制和解决方案:
| 用户类型 | 同步接口限制 | 异步接口限制 | 可用解决方案 |
| ---- | ------ | ------- | -------------------------------------------------------------------------------------------------------- |
| 免费用户 | ≤100 页 | ≤100 页 | ① 使用 `page_range` 参数分段处理
② 升级为付费用户
③ 改用[异步 API](/api-reference/endpoint/xparse/v1/parse-async) |
| 付费用户 | ≤500 页 | ≤2000 页 | ① 使用 `page_range` 参数分段处理
② 若文件超过 500 页,建议改用[异步 API](/api-reference/endpoint/xparse/v1/parse-async) |
| 企业客户 | ≤500 页 | ≤5000 页 | ① 使用 `page_range` 参数分段处理
② 若文件超过 500 页,建议改用[异步 API](/api-reference/endpoint/xparse/v1/parse-async) |
**使用场景**:
* 仅处理文档的特定页面
* 减少处理时间和成本
* 分批处理大型文档
***
## exports(格式转换)
在解析文档的同时,额外将结果导出为 **docx / xlsx / pdf** 文件。解析结果(`markdown` / `elements` / `pages`)与导出文件在**同一次请求内**返回,各导出任务独立成败、互不影响。
不传 `exports` 时,响应与原解析接口完全一致(向后兼容)。导出文件通过下载接口获取,具体见[返回结构详解 - 格式转换结果](/xparse/v1/parse-response#格式转换结果(exports))。
```json theme={null}
{
"document": { "password": "加密文档密码" },
"scope": { "page_range": "1-10" },
"config": { "force_engine": "textin", "engine_params": {} },
"exports": [
{ "format": "docx", "config": { "mode": "flow", "handwritten_render": 0 } },
{ "format": "xlsx", "config": { "scope": "table", "sheet_mode": "multi" } },
{ "format": "pdf", "config": { "mode": "layout" } }
]
}
```
| 字段 | 必填 | 说明 |
| ------------------ | -- | ---------------------------------------- |
| `exports[].format` | 是 | 文件格式:`docx` / `xlsx` / `pdf`(每种格式最多出现一次) |
| `exports[].config` | 否 | 按格式区分的导出配置,缺省字段使用默认值 |
**各格式配置项**:
| 格式 | 配置项 | 取值 | 默认 |
| ---- | -------------------- | ------------------------------ | ---------- |
| docx | `mode` | `flow` / `layout` | `flow` |
| docx | `handwritten_render` | `0` / `1` / `2` | `0` |
| xlsx | `scope` | `document`(全部元素)/ `table`(仅表格) | `document` |
| xlsx | `sheet_mode` | `multi` / `single` | `multi` |
| pdf | `mode` | `layout` | `layout` |
**docx `handwritten_render`(手写体输出方式)**:
控制导出的 Word 文档中手写内容的呈现方式,适配不同的编辑与归档场景。
| 取值 | 说明 |
| --- | ------------- |
| `0` | 转为印刷体文字输出(默认) |
| `1` | 以图片形式保留手写内容原样 |
| `2` | 不输出手写内容 |
**xlsx 分表逻辑(`scope` × `sheet_mode`)**:
| scope | sheet\_mode | 行为 |
| ---------- | ----------- | --------------------- |
| `table` | `multi` | 每个表格一个 Sheet |
| `table` | `single` | 所有表格放入同一个 Sheet |
| `document` | `multi` | 每页一个 Sheet(文本段落 + 表格) |
| `document` | `single` | 全部内容放入同一个 Sheet |
**使用场景**:
* 解析后直接获得可下载的 Word / Excel / PDF 文件,无需自行二次转换
* 将表格批量导出为 Excel 便于数据处理
* 还原文档版面生成 PDF 用于归档或分享
***
## config(高级配置)
专家模式配置,用于强制指定解析引擎和引擎参数。
**谨慎使用**:这些配置仅供专业用户使用。不当的配置可能导致解析质量下降或失败。
### force\_engine
强制指定内部解析引擎。
| 字段 | 类型 | 可选值 | 说明 |
| -------------- | ------ | ---------------------- | ----------- |
| `force_engine` | string | `textin`, `textin_gui` | 强制使用特定的解析引擎 |
**引擎说明**:
* `textin`:TextIn 自研引擎,默认选项,综合性能最佳
* `textin_gui`:GUI 识别引擎,用于桌面/移动/网页应用界面截图识别
`textin_gui` 仅支持图片格式(JPEG、PNG、GIF、WebP),文件大小不超过 10MB,且返回结构有差异。详见 [GUI 识别引擎特别说明](/xparse/v1/parse-response#gui-识别引擎特别说明)
**使用场景**:
* 对比不同引擎的效果
* 特定场景下需要使用特定引擎
* 调试和测试
```json theme={null}
{
"config": {
"force_engine": "textin"
}
}
```
### engine\_params
引擎级自定义参数,不同引擎支持的参数不同。
| 字段 | 类型 | 说明 |
| --------------- | ------ | ------------- |
| `engine_params` | object | 传递给解析引擎的自定义参数 |
**常用参数示例**:
```json theme={null}
{
"config": {
"force_engine": "textin",
"engine_params": {
"parse_mode": "parse",
"formula_level": 0,
"image_output_type": "url",
"recognize_chemical": true
}
}
}
```
| 参数 | 类型 | 可选值 | 说明 |
| -------------------- | ------- | -------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------- |
| `parse_mode` | string | `auto`, `scan`, `parse`, `lite`, `vlm` | PDF 解析模式。
• `auto`:由引擎自动选择,适用范围最广
• `scan`:全当图片解析
• `parse`:仅电子档文字解析,速度最快
• `lite`:轻量版,只输出表格和文字结果
• `vlm`:视觉语言模型解析模式 |
| `formula_level` | int | `0`, `1` | 公式识别级别,0 为标准,1 为增强 |
| `image_output_type` | string | `url`, `base64` | 图片输出类型,`url` 或 `base64` |
| `recognize_chemical` | boolean | `true`, `false` | 获取文档中的化学分子式结构,仅在`vlm`模式下生效,打开后可在元素的 text 中查看结果 |
不同引擎支持的参数可能不同,具体参数请联系技术支持获取。
***
## 完整配置示例
### 基础配置(推荐)
适用于大多数场景的默认配置:
```json theme={null}
{
"capabilities": {
"include_hierarchy": true,
"title_tree": true,
"include_table_structure": true
}
}
```
### 最大化详细信息
返回所有可用的详细信息(会增加处理时间和数据量):
```json theme={null}
{
"capabilities": {
"include_hierarchy": true,
"include_inline_objects": true,
"include_char_details": true,
"include_image_data": true,
"include_table_structure": true,
"pages": true,
"title_tree": true,
"table_view": "html"
}
}
```
### 最小化配置
仅返回基本的元素和 Markdown:
```json theme={null}
{
"capabilities": {
"include_hierarchy": false
}
}
```
### 处理加密 PDF
```json theme={null}
{
"document": {
"password": "your-pdf-password"
},
"capabilities": {
"include_hierarchy": true,
"title_tree": true
}
}
```
### 仅处理前 10 页
```json theme={null}
{
"scope": {
"page_range": "1-10"
},
"capabilities": {
"include_hierarchy": true
}
}
```
***
## 性能优化建议
只开启必需的能力开关,避免返回不必要的数据。例如,如果不需要字符级详情,就不要开启 `include_char_details`。
对于大文档,可以先处理部分页面进行测试,确认效果后再处理全部页面。
对于超过 50 页的文档,建议使用异步 API,避免 HTTP 超时。
相同文档的重复处理会产生相同的 `file_id`,可以通过 `file_id` 实现结果缓存。
***
## 相关链接
5 分钟完成第一次文档解析
了解完整的返回数据结构
完整的 API 参数与响应 Schema
使用异步 API 处理大文件
# 返回结构详解
Source: https://docs.textin.com/xparse/v1/parse-response
了解文档解析 API 返回的 Elements、Markdown、坐标、表格结构等完整字段说明
文档解析 API 返回统一的 JSON 结构,包含文档的 Markdown 表示、结构化元素列表、页面元信息等。本文档详细说明返回结果的各个字段。
## 响应总览
```json theme={null}
{
"code": 200,
"message": "success",
"data": {
"schema_version": "1.3.0",
"file_id": "doc_7f3a2b",
"job_id": "job_x9k2m",
"success_count": 5,
"metadata": { ... },
"markdown": "# 标题\n\n正文内容...",
"elements": [ ... ],
"title_tree": [ ... ],
"pages": [ ... ],
"summary": { ... }
}
}
```
### 顶层字段
| 字段 | 类型 | 说明 |
| --------- | ------ | ------------ |
| `code` | int | 状态码,200 表示成功 |
| `message` | string | 状态信息 |
| `data` | object | 解析结果数据 |
### data 字段
| 字段 | 类型 | 说明 |
| ---------------- | ------ | -------------------------- |
| `schema_version` | string | 数据结构版本号,当前为 `"1.3.0"` |
| `file_id` | string | 文件唯一标识 |
| `job_id` | string | 任务唯一标识 |
| `success_count` | int | 成功解析的页数(计费依据) |
| `metadata` | object | 文件元信息 |
| `markdown` | string | 文档的 Markdown 表示 |
| `elements` | array | 文档元素列表 |
| `title_tree` | array | 文档目录树(需开启 `title_tree` 能力) |
| `pages` | array | 页面元信息列表(需开启 `pages` 能力) |
| `summary` | object | 处理耗时统计 |
***
## metadata(文件元信息)
```json theme={null}
{
"filename": "document.pdf",
"filetype": "application/pdf",
"page_count": 10,
"data_source": {
"record_locator": {
"protocol": "file",
"remote_file_path": "/path/to/document.pdf"
},
"url": "file:///path/to/document.pdf"
}
}
```
| 字段 | 类型 | 说明 |
| ------------- | ------ | ---------------- |
| `filename` | string | 文件名 |
| `filetype` | string | 文件 MIME 类型 |
| `page_count` | int | 文档总页数 |
| `data_source` | object | 数据源详细信息,包含协议、路径等 |
***
## elements(文档元素)
`elements` 是解析结果的核心,每个元素代表文档中的一个结构化单元(标题、段落、表格、图片等)。
**GUI 引擎差异**:使用 `force_engine: "textin_gui"` 时,elements 结构有所不同,包含 GUI 专属字段和元素类型。详见 [GUI 识别引擎特别说明](#gui-识别引擎特别说明)。
### 基本结构
```json theme={null}
{
"element_id": "el_001",
"type": "Title",
"text": "第一章 概述",
"page_number": 1,
"coordinates": [0.100000, 0.120000, 0.320000, 0.120000, 0.320000, 0.160000, 0.100000, 0.160000],
"metadata": {
"category_depth": 0,
"children_ids": ["el_002", "el_003"],
"is_continuation": false,
"data_source": {
"record_locator": {
"protocol": "file",
"remote_file_path": "/path/to/document.pdf"
},
"url": "file:///path/to/document.pdf"
}
}
}
```
### 基础字段
| 字段 | 类型 | 说明 |
| ----------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------ |
| `element_id` | string | 元素唯一标识 |
| `type` | string | 元素类型(见下方类型表) |
| `sub_type` | string | 元素子类型(可选),用于进一步细分。如 `Image` 可能有 `stamp`(印章)、`qrcode`(二维码)、`barcode`(条形码)、`chart`(图表)等子类型;`Table` 可能有 `bordered`(有框线)、`borderless`(无框线)等子类型 |
| `text` | string | 元素文本内容 |
| `page_number` | int | 所在页码(从 1 开始) |
| `coordinates` | array | 四点坐标,归一化到 \[0, 1],顺序为左上、右上、右下、左下 |
| `metadata` | object | 元素元信息 |
| `objects` | array | 元素内的行内对象列表(需开启 `include_inline_objects`,见下文) |
| `table_structure` | object | 表格结构详情(仅 `Table` 元素,需开启 `include_table_structure`,见下文) |
| `char_details` | array | 字符级详细信息(需开启 `include_char_details`,见下文) |
| `image_data` | object | 图片数据(仅 `Image` 元素,需开启 `include_image_data`,见下文) |
**GUI 引擎专属字段**:使用 GUI 引擎时,elements 还包含 `interactivity`(是否可交互)和 `description`(语义描述)字段。[查看详情](#gui-识别引擎特别说明)
### 元素类型
| 类型 | 说明 |
| ------------------- | ----- |
| `Title` | 标题 |
| `NarrativeText` | 正文段落 |
| `ListItem` | 列表项 |
| `Table` | 表格 |
| `TableCaption` | 表格标题 |
| `Image` | 图片 |
| `FigureCaption` | 图片标题 |
| `Formula` | 数学公式 |
| `Chemical` | 化学分子式 |
| `Header` | 页眉 |
| `Footer` | 页脚 |
| `PageNumber` | 页码 |
| `PageBreak` | 分页符 |
| `CodeSnippet` | 代码片段 |
| `UncategorizedText` | 未分类文本 |
上述元素类型适用于文档解析引擎。**GUI 引擎使用不同的元素类型**(如 button, input, checkbox 等),详见 [GUI 元素类型](#ui-元素类型(type))。
### metadata 字段
| 字段 | 类型 | 说明 |
| --------------------- | ------ | ---------------------------------------------- |
| `parent_id` | string | 父元素 ID(需开启 `include_hierarchy`) |
| `children_ids` | array | 子元素 ID 列表(需开启 `include_hierarchy`) |
| `category_depth` | int | 同类型元素的嵌套深度(如 Title 的 0 为一级标题,1 为二级标题) |
| `ref_element_id` | string | 关联元素 ID,如图片/表格与其标题的关联(需开启 `include_hierarchy`) |
| `is_continuation` | bool | 是否为跨页续接的元素 |
| `continuation_of` | string | 当 `is_continuation=true` 时,指向被续接的前一个元素 ID |
| `has_inline_objects` | bool | 是否包含行内对象(需开启 `include_inline_objects`) |
| `inline_object_types` | array | 行内对象类型列表,如 `["formula", "handwriting"]` |
| `width` | int | 图片宽度(仅 Image 元素) |
| `height` | int | 图片高度(仅 Image 元素) |
| `data_source` | object | 数据源详细信息 |
***
## 坐标系统
坐标使用归一化的四点表示法,每个坐标值在 `[0, 1]` 范围内,表示相对于页面宽高的比例。
```
coordinates: [x1, y1, x2, y2, x3, y3, x4, y4]
```
四个点的顺序为:
```
(x1,y1) -------- (x2,y2)
| |
| 元素区域 |
| |
(x4,y4) -------- (x3,y3)
```
坐标值保留六位小数,范围 \[0, 1],表示相对于页面宽高的比例。要将归一化坐标转换为像素坐标,需要乘以页面的实际宽高:
```python theme={null}
# 假设页面宽 595px, 高 842px (A4)
page_width, page_height = 595, 842
pixel_x1 = coordinates[0] * page_width
pixel_y1 = coordinates[1] * page_height
```
***
## 表格结构(table\_structure)
当开启 `include_table_structure` 能力时,类型为 `Table` 的元素会包含 `table_structure` 字段。
```json theme={null}
{
"element_id": "el_010",
"type": "Table",
"text": "| 姓名 | 年龄 |\n|---|---|\n| 张三 | 28 |",
"table_structure": {
"rows": 2,
"cols": 2,
"cells": [
{
"cell_id": "tbl_001_r1_c1",
"row": 1,
"col": 1,
"row_span": 1,
"col_span": 1,
"content_type": "text",
"text": "姓名",
"coordinates": [0.100000, 0.300000, 0.300000, 0.300000, 0.300000, 0.340000, 0.100000, 0.340000]
},
{
"cell_id": "tbl_001_r1_c2",
"row": 1,
"col": 2,
"row_span": 1,
"col_span": 1,
"content_type": "text",
"text": "年龄",
"coordinates": [0.300000, 0.300000, 0.500000, 0.300000, 0.500000, 0.340000, 0.300000, 0.340000]
},
{
"cell_id": "tbl_001_r2_c1",
"row": 2,
"col": 1,
"row_span": 1,
"col_span": 1,
"content_type": "text",
"text": "张三",
"coordinates": [0.100000, 0.340000, 0.300000, 0.340000, 0.300000, 0.380000, 0.100000, 0.380000]
},
{
"cell_id": "tbl_001_r2_c2",
"row": 2,
"col": 2,
"row_span": 1,
"col_span": 1,
"content_type": "text",
"text": "28",
"coordinates": [0.300000, 0.340000, 0.500000, 0.340000, 0.500000, 0.380000, 0.300000, 0.380000]
}
]
}
}
```
### 单元格字段
| 字段 | 类型 | 说明 |
| -------------- | ------ | ----------------------------------------------------------------------------------------------------------------- |
| `cell_id` | string | 单元格唯一标识 |
| `row` | int | 行索引(从 1 开始) |
| `col` | int | 列索引(从 1 开始) |
| `row_span` | int | 跨行数 |
| `col_span` | int | 跨列数 |
| `content_type` | string | 内容类型:`text`(文本)、`formula`(公式)、`image`(图片)、`mixed`(混合) |
| `text` | string | 单元格文本 |
| `coordinates` | array | 单元格四点坐标 |
| `image_datas` | array | 图片数据数组(当 `content_type` 为 `image` 时,需开启 `include_image_data`)。了解版本差异请参考 [Schema 版本迁移指南](/xparse/schema-migration) |
| `objects` | array | 单元格内嵌对象列表(需开启 `include_inline_objects`) |
| `char_details` | array | 字符级详情(需开启 `include_char_details`) |
当请求参数 `element_merge_mode` 为 `merged` 时,合并后的单元格还会返回 `source_regions`、`role`、`header_cell_ids`、`text_source_ranges` 等跨页来源字段,详见[跨页表格合并](#单元格新增字段(merged-模式))。
***
## 跨页表格合并(merged 模式)
当一张表格被分页切断、跨越多个物理页时,可通过请求参数 `element_merge_mode` 选择输出方式。默认 `separate` 沿用按页输出,`merged` 则把同一张逻辑表合并为一个 Table 元素。
`element_merge_mode` 的取值与配置方式,详见[解析配置详解](/xparse/v1/parse-config#element_merge_mode)。
### 两种模式对比
**`separate`(默认)**:每个物理分页分别返回一个 Table 片段,通过 `metadata.is_continuation` 和 `metadata.continuation_of` 建立续接关系。
```json theme={null}
[
{
"element_id": "table_fragment_p1",
"type": "Table",
"sub_type": "bordered",
"text": "",
"page_number": 1,
"coordinates": [0.1, 0.18, 0.9, 0.18, 0.9, 0.84, 0.1, 0.84],
"metadata": { "is_continuation": false }
},
{
"element_id": "table_fragment_p2",
"type": "Table",
"sub_type": "bordered",
"text": "",
"page_number": 2,
"coordinates": [0.1, 0.16, 0.9, 0.16, 0.9, 0.82, 0.1, 0.82],
"metadata": { "is_continuation": true, "continuation_of": "table_fragment_p1" }
}
]
```
**`merged`**:同一张逻辑跨页表只返回一个合并后的 Table,`text` 为完整表格 HTML(续页重复的表头只保留一份,跨页的 `rowspan`/`colspan` 合并为一个单元格),并通过 `metadata.source_regions` 记录各物理页的来源区域。合并后的 `is_continuation` 固定为 `false`,不返回 `continuation_of`。
```json theme={null}
{
"element_id": "table_merged_7b9a5d",
"type": "Table",
"sub_type": "bordered",
"text": "",
"page_number": 1,
"coordinates": [0.1, 0.18, 0.9, 0.18, 0.9, 0.84, 0.1, 0.84],
"metadata": {
"is_continuation": false,
"table_structure_status": "available",
"table_layout": {
"rows": 8,
"cols": 4,
"header_rows": [1]
},
"source_regions": [
{ "page_number": 1, "coordinates": [0.1, 0.18, 0.9, 0.18, 0.9, 0.84, 0.1, 0.84], "start_row": 1, "end_row": 4 },
{ "page_number": 2, "coordinates": [0.1, 0.16, 0.9, 0.16, 0.9, 0.82, 0.1, 0.82], "start_row": 5, "end_row": 8 }
]
},
"table_structure": {
"rows": 8,
"cols": 4,
"cells": ["..."]
}
}
```
`table_structure_status` 为 `available` 时,Table 必定带 `table_structure`(合并后的单元格结构,示例中的 `cells` 已省略,详见[单元格新增字段](#单元格新增字段(merged-模式)));为 `disabled` 或 `unavailable` 时则不返回 `table_structure`。
合并后的 Table 顶层 `page_number` 与 `coordinates` 只表示表格首页的位置(即 `source_regions[0]`)。要获取表格跨越的全部页面及各页坐标,请读取 `metadata.source_regions`。
### 表级新增字段(merged 模式)
`merged` 模式下,Table 元素的 `metadata` 会额外返回以下字段(无论是否开启 `include_table_structure`,`table_layout`、`source_regions`、`table_structure_status` 都必定返回)。
| 字段 | 类型 | 说明 |
| ------------------------------ | ------ | ------------------------------------------------------------------------------------------------------------------- |
| `table_layout` | object | 合并后表格的逻辑网格信息 |
| `table_layout.rows` | int | 合并表总行数(不含续页被去重的重复表头) |
| `table_layout.cols` | int | 合并表总列数 |
| `table_layout.header_rows` | int\[] | 表头所在行号(1 起、去重、升序),可为空;多级表头列出全部表头行 |
| `table_structure_status` | string | 单元格结构状态:`available`(已生成,存在 `table_structure`)、`disabled`(未开启 `include_table_structure`)、`unavailable`(已请求但引擎无法可靠生成) |
| `source_regions` | array | 各物理页来源区域,按页码和阅读顺序排列 |
| `source_regions[].page_number` | int | 物理页码(从 1 开始) |
| `source_regions[].coordinates` | array | 该页表格片段的归一化四点坐标 |
| `source_regions[].start_row` | int | 该片段贡献的首个合并表行号(1 起,闭区间) |
| `source_regions[].end_row` | int | 该片段贡献的末个合并表行号(1 起,闭区间)。各区间的行范围连续覆盖 `1` 到 `table_layout.rows`,互不重叠 |
### 单元格新增字段(merged 模式)
`merged` 且开启 `include_table_structure` 时,合并后的单元格(Canonical Cell)在[单元格字段](#单元格字段)基础上,额外返回跨页来源信息:
| 字段 | 类型 | 说明 |
| -------------------- | ------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `source_regions` | array | 该单元格在各物理页的来源区域,每项含 `page_number` 和归一化 `coordinates`;跨页 `rowspan` 单元格可有多个区域 |
| `role` | string | 单元格角色:`column_header`、`row_header`、`data`、`footer`;无法判断时可省略,此时可参照 `table_layout.header_rows` 判断是否表头 |
| `header_cell_ids` | array | 该单元格对应的表头单元格 ID 列表;多级表头或横跨多列时可引用多个;表头单元格自身为空或省略 |
| `text_source_ranges` | array | 把合并后 `text` 的字符区间映射回物理页。每项含 `start`/`end`(相对 `text` 的 `[start, end)` 半开区间,单位为 Unicode 码点)、`page_number`、`coordinates`;文本跨页的长单元格建议返回。多个区间按 `start` 升序且互不重叠;计算偏移前请勿对 `text` 做 trim、空白折叠或 Unicode 归一化,否则区间会错位 |
合并后单元格的 `coordinates` 只表示该单元格在首页的位置(即 `source_regions[0].coordinates`)。要获取单元格跨越的全部页面位置,请读取 `source_regions`。续页重复的表头不产生新单元格,其在各页出现的位置都并入同一个表头单元格的 `source_regions`。
### Cell 关闭时(include\_table\_structure=false)
`merged` + `include_table_structure=false` 时不返回 `table_structure`,但 `table_layout` 和表级 `source_regions` 仍会返回,`table_structure_status` 为 `disabled`:
```json theme={null}
{
"element_id": "table_merged_7b9a5d",
"type": "Table",
"sub_type": "bordered",
"text": "",
"page_number": 1,
"coordinates": [0.1, 0.18, 0.9, 0.18, 0.9, 0.84, 0.1, 0.84],
"metadata": {
"is_continuation": false,
"table_structure_status": "disabled",
"table_layout": { "rows": 12, "cols": 4, "header_rows": [1] },
"source_regions": [
{ "page_number": 1, "coordinates": [0.1, 0.18, 0.9, 0.18, 0.9, 0.84, 0.1, 0.84], "start_row": 1, "end_row": 6 },
{ "page_number": 2, "coordinates": [0.1, 0.18, 0.9, 0.18, 0.9, 0.84, 0.1, 0.84], "start_row": 7, "end_row": 12 }
]
}
}
```
此时仍可从 HTML 恢复逻辑行列,并按表级 `source_regions` 定位整段物理页区域;无法提供的是单元格级精确坐标、表头引用和字符级来源。
***
## 图片数据(image\_data)
当开启 `include_image_data` 能力时,类型为 `Image` 的元素会包含 `image_data` 字段。
```json theme={null}
{
"element_id": "el_020",
"type": "Image",
"text": "",
"image_data": {
"image_url": "https://example.com/images/xxx.png",
"mime_type": "image/png",
"base64": "iVBORw0KGgoAAAANSUhEUg..."
}
}
```
| 字段 | 类型 | 说明 |
| ----------- | ------ | ---------------- |
| `image_url` | string | 图片访问 URL |
| `mime_type` | string | 图片 MIME 类型 |
| `base64` | string | 图片 Base64 编码(可选) |
***
## 字符级详情(char\_details)
当开启 `include_char_details` 能力时,元素会包含 `char_details` 字段,提供字符级别的坐标和识别置信度。
```json theme={null}
{
"element_id": "el_001",
"type": "Title",
"text": "概述",
"char_details": [
{
"index": 0,
"text": "概",
"coordinates": [0.100000, 0.120000, 0.140000, 0.120000, 0.140000, 0.160000, 0.100000, 0.160000],
"recognition": {
"confidence": 0.999,
"candidates": [
{"text": "概", "confidence": 0.999},
{"text": "槪", "confidence": 0.001}
]
}
},
{
"index": 1,
"text": "述",
"coordinates": [0.140000, 0.120000, 0.180000, 0.120000, 0.180000, 0.160000, 0.140000, 0.160000],
"recognition": {
"confidence": 0.998,
"candidates": [
{"text": "述", "confidence": 0.998},
{"text": "迹", "confidence": 0.002}
]
}
}
]
}
```
| 字段 | 类型 | 说明 |
| ------------------------ | ------ | ----------- |
| `index` | int | 字符在文本中的位置索引 |
| `text` | string | 字符文本 |
| `coordinates` | array | 字符四点坐标 |
| `recognition.confidence` | float | 识别置信度 (0-1) |
| `recognition.candidates` | array | 候选识别结果 |
***
## 行内对象(objects)
当开启 `include_inline_objects` 能力时,包含行内对象的元素会返回 `objects` 字段,标识文本中的公式、手写体、复选框等行内元素。
```json theme={null}
{
"element_id": "el_004",
"type": "NarrativeText",
"text": "设违约金函数 $f(x)=x^2+1$ 。",
"objects": [
{
"object_id": "obj_001",
"type": "formula",
"text": "$f(x)=x^2+1$",
"text_range": [7, 20],
"coordinates": [0.220000, 0.480000, 0.300000, 0.480000, 0.300000, 0.540000, 0.220000, 0.540000],
"metadata": {
"display_mode": "inline"
}
}
]
}
```
| 字段 | 类型 | 说明 |
| ------------- | ------ | ---------------------------------------------------------------- |
| `object_id` | string | 对象唯一标识 |
| `type` | string | 对象类型:`formula`(公式)、`handwriting`(手写)、`checkbox`(复选框)、`image`(图片) |
| `sub_type` | string | 对象子类型(可选) |
| `text` | string | 对象文本内容 |
| `text_range` | array | 对象在父元素文本中的位置 `[start, end)`,0-based 半开区间 |
| `coordinates` | array | 对象四点坐标 |
| `image_data` | object | 图片数据(当 `type` 为 `image` 时) |
| `metadata` | object | 对象元信息,如公式的 `display_mode`(`inline` 或 `display`) |
***
## 目录树(title\_tree)
当开启 `title_tree` 能力时,返回文档的层级目录结构:
```json theme={null}
{
"title_tree": [
{
"element_id": "el_001",
"title": "第一章 概述",
"level": 1,
"page_number": 1,
"children": [
{
"element_id": "el_005",
"title": "1.1 背景",
"level": 2,
"page_number": 1,
"children": []
},
{
"element_id": "el_010",
"title": "1.2 目标",
"level": 2,
"page_number": 2,
"children": []
}
]
}
]
}
```
| 字段 | 类型 | 说明 |
| ------------- | ------ | ---------------- |
| `element_id` | string | 对应 Title 元素的 ID |
| `title` | string | 标题文本 |
| `level` | int | 标题层级,1 为最高(一级标题) |
| `page_number` | int | 所在页码 |
| `children` | array | 嵌套的子标题节点列表 |
***
## 页面信息(pages)
当开启 `pages` 能力时,返回每一页的元信息:
```json theme={null}
{
"pages": [
{
"page_number": 1,
"page_width": 1576,
"page_height": 1683,
"page_image_url": "https://example.com/page-1.jpg",
"element_ids": ["el_001", "el_002", "el_003"],
"spanning_element_ids": ["table_merged_7b9a5d"],
"dpi": 144,
"angle": 0,
"status": "Success"
}
]
}
```
| 字段 | 类型 | 说明 |
| ---------------------- | ------ | -------------------------------------------------------------------------------------------------------------------- |
| `page_number` | int | 页码(从 1 开始) |
| `page_width` | number | 页面宽度(像素) |
| `page_height` | number | 页面高度(像素) |
| `page_image_url` | string | 页面渲染图 URL |
| `element_ids` | array | 该页包含的元素 ID 列表,顺序与页面内默认阅读顺序一致 |
| `spanning_element_ids` | array | 跨页元素 ID 列表(仅 `element_merge_mode=merged` 时返回)。合并后的跨页表格只在首个来源页的 `element_ids` 中出现一次,其余来源页通过本字段引用,不在 `element_ids` 中重复 |
| `dpi` | int | 当前页转成图片所用的 DPI |
| `angle` | number | 页面旋转角度(0 度为正常阅读方向,顺时针旋转) |
| `status` | string | 页面处理状态 |
***
## 格式转换结果(exports)
当请求中配置了 [`exports`](/xparse/v1/parse-config#exports(格式转换)) 时,响应的 `data` 中会返回 `exports` 数组,包含各导出任务的状态与文件信息。
```json theme={null}
{
"data": {
"schema_version": "1.3.1",
"file_id": "doc_xxx",
"markdown": "# 文档标题...",
"elements": [],
"pages": [],
"exports": [
{
"format": "docx",
"status": "success",
"file": {
"file_id": "8bb84607d83b0115.docx",
"mime_type": "application/vnd.openxmlformats-officedocument.wordprocessingml.document",
"size": 174135,
"expires_at": "2026-08-23T17:48:15+08:00"
},
"warnings": []
}
]
}
}
```
**`data.exports[]` 字段**:
| 字段 | 类型 | 说明 |
| ---------- | ------ | ---------------------------------------------------------------------- |
| `format` | string | 导出格式:`docx` / `xlsx` / `pdf` |
| `status` | string | 单个导出任务状态:`success` / `fail` |
| `file` | object | `status=success` 时返回,含 `file_id` / `mime_type` / `size` / `expires_at` |
| `warnings` | array | 非致命降级信息(如部分图片下载失败) |
| `error` | object | `status=fail` 时返回错误信息(与 `file` 互斥) |
响应顶层 `code=200` 仅表示解析请求成功;每个导出文件是否成功以 `exports[].status` 为准。单个导出失败不影响其他导出与解析结果。
### 下载导出文件
使用 `exports[].file.file_id` 的**原值**(需带后缀,如 `8bb84607d83b0115.docx`)调用下载接口获取文件:
```
GET https://api.textin.com/export_file/download?file_id={file_id}
x-ti-app-id: YOUR_APP_ID
x-ti-secret-code: YOUR_SECRET
```
| 参数 | 说明 |
| --------- | --------------------------------------- |
| `file_id` | 解析响应里 `exports[].file.file_id` 的原值(含后缀) |
**响应**:直接返回文件**字节流**(HTTP 200,body 为文件二进制内容)。
**下载约束**
* **仅生成者可下载**:只能用生成该 `file_id` 的同一个 app 凭证下载,跨 app 下载返回 `404 image does not exist`。
* `file_id` 有过期时间(见 `expires_at`),过期后不可下载。
* 下载相关的错误码排查见[常见错误码](#常见错误码)。
***
## 处理摘要(summary)
返回本次解析的耗时统计:
```json theme={null}
{
"summary": {
"duration_ms": 812
}
}
```
| 字段 | 类型 | 说明 |
| ------------- | ------ | ------- |
| `duration_ms` | number | 总耗时(毫秒) |
***
## 错误响应
当 `code` 不为 200 时,表示请求出错。错误响应可能包含 `location` 字段,用于定位错误发生的位置:
```json theme={null}
{
"code": 40004,
"message": "参数错误,请查看技术文档,检查传参",
"location": {
"stage": "parse",
"page_number": 3,
"element_id": "el_045"
}
}
```
| 字段 | 类型 | 说明 |
| ------------- | ------ | ------- |
| `stage` | string | 出错阶段 |
| `page_number` | int | 出错页码 |
| `element_id` | string | 出错元素 ID |
### 常见错误码
| 错误码 | HTTP 状态码 | 说明 |
| ----- | -------- | -------------------------------------------------------------------- |
| 40101 | 200 | x-ti-app-id 或 x-ti-secret-code 为空 |
| 40102 | 200 | x-ti-app-id 或 x-ti-secret-code 无效,验证失败 |
| 40103 | 200 | 客户端IP不在白名单 |
| 40003 | 200 | 余额不足,请充值后再使用 |
| 40004 | 200 | 参数错误,请查看技术文档,检查传参 |
| 40007 | 200 | 机器人不存在或未发布 |
| 40008 | 200 | 机器人未开通,请至市场开通后重试 |
| 40301 | 200 | 图片类型不支持 |
| 40302 | 200 | 上传文件大小不符,文件大小不超过 500M |
| 40303 | 200 | 文件类型不支持,接口会返回实际检测到的文件类型,如"当前文件类型为.gif" |
| 40304 | 200 | 图片尺寸不符,长宽比小于2的图片宽高需在20~20000像素范围内,其他图片的宽高需在20~10000像素范围内 |
| 40305 | 200 | 识别文件未上传 |
| 40306 | 200 | qps超过限制 |
| 40307 | 200 | 今日免费额度已用完 |
| 40422 | 200 | 文件损坏(The file is corrupted.) |
| 40423 | 200 | PDF密码错误(Password required or incorrect password.) |
| 40424 | 200 | 页数设置超出文件范围(Page number out of range.) |
| 40425 | 200 | 文件格式不支持(The input file format is not supported.) |
| 40427 | 200 | DPI参数不在支持列表中(Input DPI is not in the allowed DPIs list(72,144,216).) |
| 40428 | 200 | word和ppt转pdf失败或者超时(Process office file failed.) |
| 40429 | 200 | 不支持的引擎(Unsupported Engine.) |
| 50207 | 200 | 部分页面解析失败(Partial failed) |
| 40400 | 200 | 无效的请求链接,请检查链接是否正确 |
| 30203 | 200 | 基础服务故障,请稍后重试 |
| 500 | 200 | 服务器内部错误 |
遇到错误时,可以通过响应头中的 `x-request-id` 联系技术支持排查问题。
**格式转换下载接口相关错误码**:
| 错误码 | 说明 | 排查方向 |
| ----- | ---------------------- | ----------------------------------------------------- |
| 200 | 请求成功 | 导出是否成功以 `exports[].status` 为准 |
| 400 | 参数错误 | 检查 `config` 的 JSON 格式是否合法;下载接口需传入 `file_id` 参数且值含文件后缀 |
| 40101 | app-id 为空 | 请求未携带鉴权 Header |
| 40102 | app-id / secret 无效 | 凭证错误;若解析接口调用正常、仅下载接口返回此错误,说明该 app 未在下载接口注册,请联系技术支持开通 |
| 404 | `image does not exist` | `file_id` 已过期(见 `expires_at`),或使用了非生成者的 app 凭证下载 |
导出任务自身的失败(如某个格式生成失败)不体现在错误码里,而是通过 `exports[].status` 为 `fail` 及其 `error` 字段返回。详见[格式转换结果](#格式转换结果(exports))。
***
## GUI 识别引擎特别说明
使用 `force_engine: "textin_gui"` 时,返回结构与普通文档解析基本一致,但 `elements` 的 `type` 字段值和 `metadata` 字段内容有所不同。
GUI 引擎仅支持图片格式输入(JPEG、PNG、GIF、WebP),文件大小不超过 10MB,不支持 PDF 等文档格式。配置方法详见 [解析配置 - force\_engine](/xparse/v1/parse-config#force_engine)。
### 基本结构
```json theme={null}
{
"element_id": "el_001",
"type": "button",
"text": "登录",
"page_number": 1,
"coordinates": [0.450000, 0.600000, 0.550000, 0.600000, 0.550000, 0.640000, 0.450000, 0.640000],
"metadata": {
"parent_id": "el_000",
"children_ids": [],
"is_continuation": false,
"interactivity": true,
"description": "登录按钮",
"data_source": {
"record_locator": {
"protocol": "file",
"remote_file_path": "/path/to/screenshot.png"
},
"url": "file:///path/to/screenshot.png"
}
}
}
```
### 基础字段
与文档解析引擎相同,包含以下字段:
| 字段 | 类型 | 说明 |
| ------------- | ------ | ----------------------------- |
| `element_id` | string | 元素唯一标识,同其他引擎 |
| `type` | string | **UI 元素类型**(见下方类型表,与文档解析引擎不同) |
| `text` | string | 元素的可见文本/标签内容,同其他引擎 |
| `page_number` | int | 所在页码(从 1 开始),同其他引擎 |
| `coordinates` | array | 坐标信息,同其他引擎 |
| `metadata` | object | 元素元信息(**包含 GUI 专属字段**,见下方) |
### UI 元素类型(type)
与文档解析引擎不同,GUI 引擎返回的 `type` 为 UI 组件类型:
| 元素类型 | 说明 | 示例 |
| ------------ | ---- | ----------- |
| `button` | 按钮 | 提交按钮、关闭按钮 |
| `input` | 输入框 | 文本框、密码框、搜索框 |
| `checkbox` | 复选框 | 多选框 |
| `dropdown` | 下拉菜单 | 选择器、下拉列表 |
| `link` | 链接 | 超链接、导航链接 |
| `tab` | 标签页 | 选项卡 |
| `text` | 静态文本 | 标签文本、说明文字 |
| `label` | 标签 | 表单标签、分类标签 |
| `title` | 标题 | 窗口标题、区域标题 |
| `icon` | 图标 | 功能图标、状态图标 |
| `image` | 图片 | 缩略图、背景图 |
| `menu` | 菜单 | 导航菜单、上下文菜单 |
| `navigation` | 导航栏 | 顶部导航、侧边导航 |
| `toolbar` | 工具栏 | 操作工具栏 |
| `statusbar` | 状态栏 | 底部状态栏 |
### metadata 字段
GUI 引擎的 `metadata` 包含与文档解析引擎相同的通用字段(parent\_id、children\_ids、is\_continuation、data\_source 等),以及以下专属字段:
| 字段 | 类型 | 说明 |
| --------------- | ------ | ------- |
| `interactivity` | bool | 是否可交互 |
| `description` | string | 元素的语义描述 |
***
## 相关链接
从零开始完成第一次文档解析
深入了解所有输入参数配置,自定义解析行为
完整的请求参数与响应 Schema
SDK 高级用法与最佳实践
# 快速入门
Source: https://docs.textin.com/xparse/v1/quickstart
5 分钟内完成第一次文档解析,使用 Python SDK 或 REST API 将文档转化为结构化数据。
推荐使用 **Python SDK** 快速上手。如果您更熟悉直接调用 REST API,可参考下方 [REST API 示例](#rest-api-示例)。
## 新版本核心升级
相比旧版文档解析,新版本带来以下核心改进:
采用标准化的 Element 模型,数据结构更简洁清晰,易于理解和使用。返回的 JSON 体积更小,传输更快。
统一的请求配置(Config)和响应结构(Schema),兼容多种解析引擎,便于集成和迁移。
支持多种解析引擎(TextIn 和 GUI),可根据场景选择最优引擎,或对比不同引擎效果。
新增异步解析接口,支持大文件和批量处理场景,避免 HTTP 超时。支持 Webhook 回调,无需轮询。
**新增 GUI 识别引擎,精准解析界面元素**
专门用于识别桌面、移动应用和网页截图,返回 UI 元素类型(按钮、输入框、复选框等)及其位置、文本、交互性等信息。解析效果如下:
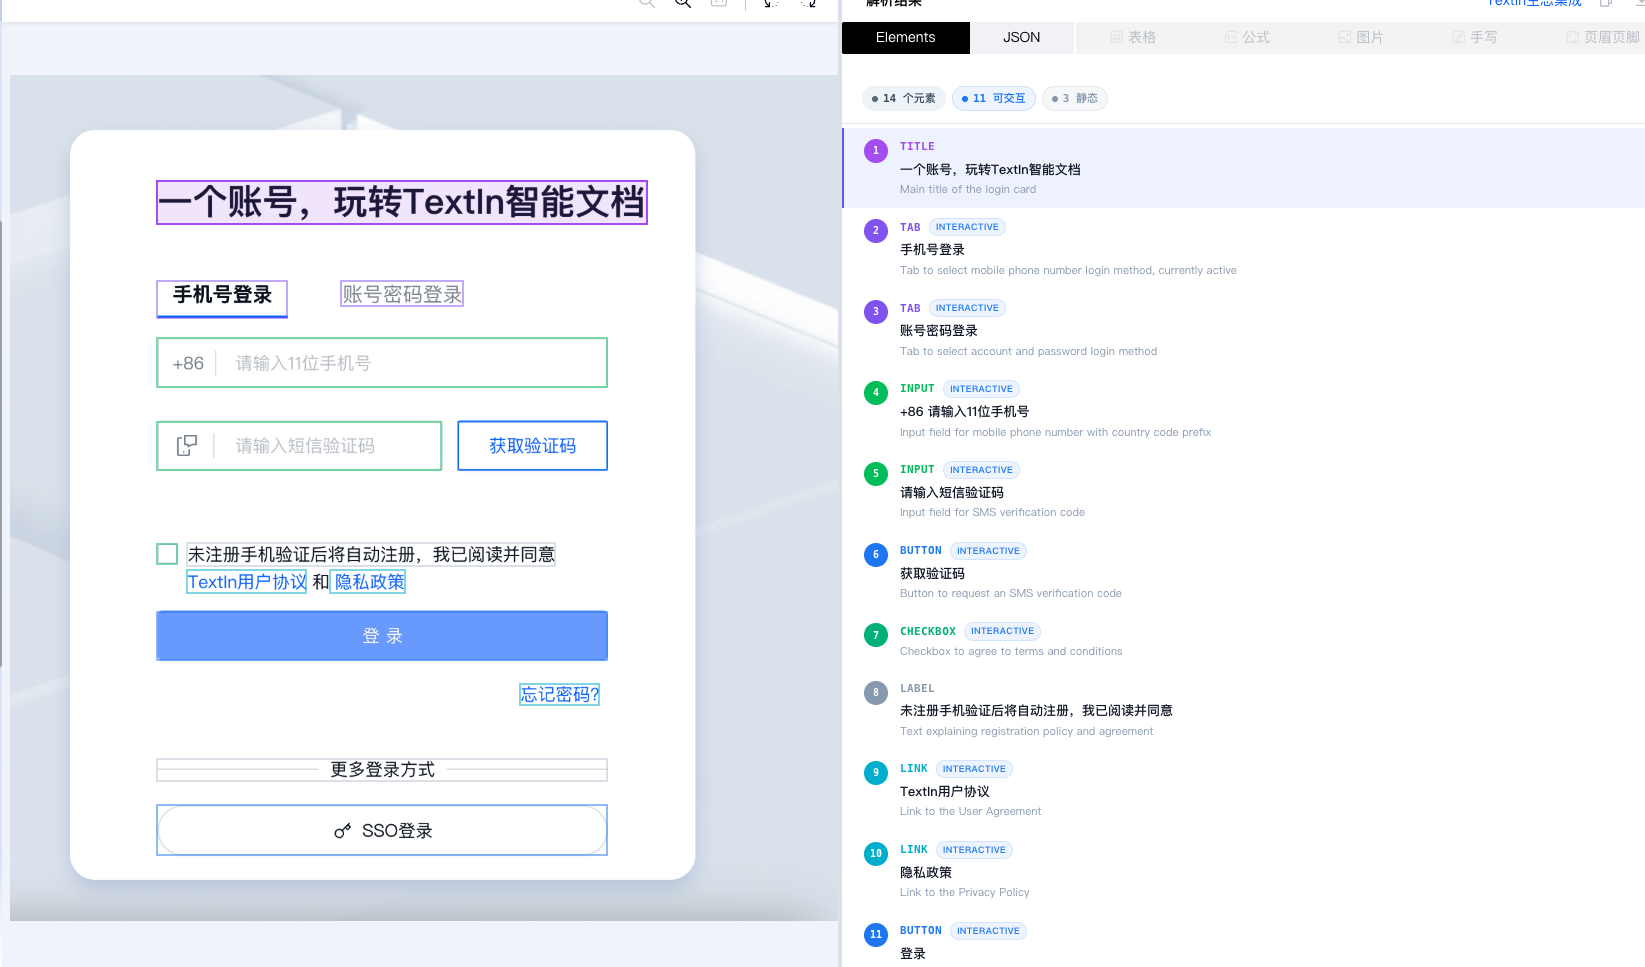
**了解更多**:[GUI 引擎配置详解](/xparse/v1/parse-config#force-engine)
***
## 准备工作
### 1. 获取 API Key
前往 [TextIn 工作台 - 账号与开发者信息](https://www.textin.com/console/dashboard/setting) 获取您的 `x-ti-app-id` 和 `x-ti-secret-code`。
详细步骤请参考 [API Key 获取指南](/xparse/api-key)。
### 2. 准备示例文件
您可以使用自己的文档,或下载我们提供的示例文件:[文档解析示例.pdf](https://dllf.intsig.net/download/2025/Solution/textin/sample/pdf_to_markdown/sample_02.pdf)
支持的文件格式:png, jpg, jpeg, pdf, bmp, tiff, webp, doc, docx, html, mhtml, xls, xlsx, csv, ppt, pptx, txt, ofd, rtf
文件大小限制:500MB
***
## 使用 Python SDK(推荐)
### Step 1:安装 SDK
```bash pip theme={null}
pip install xparse-client
```
```bash uv theme={null}
uv add xparse-client
```
### Step 2:配置环境变量
```bash theme={null}
export TEXTIN_APP_ID="your-app-id"
export TEXTIN_SECRET_CODE="your-secret-code"
```
### Step 3:解析文档
```python theme={null}
from xparse_client import XParseClient, ParseConfig, Capabilities
# 初始化客户端(自动读取环境变量)
client = XParseClient()
# 解析本地文件
with open("document.pdf", "rb") as f:
result = client.parse.run(
file=f,
filename="document.pdf",
config=ParseConfig(
capabilities=Capabilities(
include_table_structure=True,
title_tree=True,
),
),
)
```
上面的示例使用了简单的配置。你可以通过 `ParseConfig` 自定义更多能力,如字符详情、行内对象、图片数据等。详见 [解析配置详解](/xparse/v1/parse-config)。
### Step 4:查看结果
```python theme={null}
# 输出 Markdown
if result.markdown:
print(result.markdown)
# 遍历文档元素
for el in result.elements:
print(f"[{el.type}] {el.text[:80]}")
print(f"共解析 {len(result.elements)} 个元素")
```
### Step 5:保存结果
```python theme={null}
import json
# 保存为 Markdown 文件
with open("output.md", "w", encoding="utf-8") as f:
f.write(result.markdown)
# 保存完整 JSON 结果
with open("output.json", "w", encoding="utf-8") as f:
json.dump(result.model_dump(), f, ensure_ascii=False, indent=2)
```
### 完整代码(一键运行)
```python quickstart.py expandable theme={null}
"""
用法:
1. 安装依赖: pip install xparse-client
2. 设置环境变量 TEXTIN_APP_ID 和 TEXTIN_SECRET_CODE
3. python quickstart.py <文件路径>
"""
import json
import sys
from pathlib import Path
from xparse_client import XParseClient, ParseConfig, Capabilities
def main():
# 从命令行参数获取文件路径,默认使用 document.pdf
file_path = Path(sys.argv[1]) if len(sys.argv) > 1 else Path("document.pdf")
if not file_path.exists():
print(f"文件不存在: {file_path}")
sys.exit(1)
# Step 1: 初始化客户端(自动读取环境变量 TEXTIN_APP_ID, TEXTIN_SECRET_CODE)
client = XParseClient()
# Step 2: 解析文档
with open(file_path, "rb") as f:
result = client.parse.run(
file=f,
filename=file_path.name,
config=ParseConfig(
capabilities=Capabilities(
include_table_structure=True,
title_tree=True,
),
),
)
# Step 3: 打印解析概览
print(f"解析完成!共 {len(result.elements)} 个元素,{result.success_count} 页成功")
print("=" * 60)
# 输出 Markdown
if result.markdown:
print(result.markdown[:2000])
if len(result.markdown) > 2000:
print(f"\n... (Markdown 共 {len(result.markdown)} 字符,已截断)")
print("=" * 60)
# 遍历文档元素
for el in result.elements:
print(f" [{el.type:20s}] p{el.page_number}: {el.text[:60]}")
# Step 4: 保存结果
output_dir = Path("output")
output_dir.mkdir(exist_ok=True)
stem = file_path.stem
md_path = output_dir / f"{stem}.md"
with open(md_path, "w", encoding="utf-8") as f:
f.write(result.markdown)
print(f"\nMarkdown 已保存: {md_path}")
json_path = output_dir / f"{stem}.json"
with open(json_path, "w", encoding="utf-8") as f:
json.dump(result.model_dump(), f, ensure_ascii=False, indent=2)
print(f"JSON 已保存: {json_path}")
if __name__ == "__main__":
main()
```
更多 SDK 用法请参考 [Python SDK 文档](/xparse/v1/sdk-python)。
***
## REST API 示例
如果您不使用 Python SDK,可以直接调用 [REST API](/api-reference/endpoint/xparse/v1/parse-sync)。
### 同步解析
```python Python theme={null}
import requests
import json
app_id = "your-app-id"
secret_code = "your-secret-code"
with open("document.pdf", "rb") as f:
response = requests.post(
"https://api.textin.com/api/v1/xparse/parse/sync",
headers={
"x-ti-app-id": app_id,
"x-ti-secret-code": secret_code,
},
files={"file": ("document.pdf", f)},
data={
"config": json.dumps({
"capabilities": {
"include_table_structure": True,
"title_tree": True
}
})
},
)
result = response.json()
print(result["data"]["markdown"])
```
```bash cURL theme={null}
curl -X POST "https://api.textin.com/api/v1/xparse/parse/sync" \
-H "x-ti-app-id: your-app-id" \
-H "x-ti-secret-code: your-secret-code" \
-F "file=@document.pdf" \
-F 'config={"capabilities":{"include_table_structure":true,"title_tree":true}}'
```
`config` 参数支持丰富的配置选项,包括层级关系、字符详情、行内对象、图片数据等。完整配置说明请参考 [解析配置详解](/xparse/v1/parse-config)。
### 异步解析(适用于大文件)
对于大文件或需要批量处理的场景,建议使用异步 API:
```python theme={null}
import requests
import json
import time
app_id = "your-app-id"
secret_code = "your-secret-code"
headers = {
"x-ti-app-id": app_id,
"x-ti-secret-code": secret_code,
}
# Step 1: 创建异步任务
with open("large_document.pdf", "rb") as f:
response = requests.post(
"https://api.textin.com/api/v1/xparse/parse/async",
headers=headers,
files={"file": ("large_document.pdf", f)},
)
job_id = response.json()["data"]["job_id"]
print(f"任务已创建: {job_id}")
# Step 2: 轮询查询任务状态
while True:
status_resp = requests.get(
f"https://api.textin.com/api/v1/xparse/parse/async/{job_id}",
headers=headers,
)
status_data = status_resp.json()["data"]
if status_data["status"] == "completed":
print("解析完成!")
print(status_data)
# Step 3: 通过 result_url 获取实际结果
result_url = status_data["result_url"]
result_resp = requests.get(result_url, headers=headers)
result_data = result_resp.json()
# 输出元素信息
print(f"共解析 {len(result_data['elements'])} 个元素")
for element in result_data["elements"][:5]:
print(f"[{element['type']}] {element['text'][:50]}")
break
elif status_data["status"] == "failed":
print(f"解析失败: {status_data.get('message', '未知错误')}")
break
print(f"状态: {status_data['status']},等待中...")
time.sleep(5)
```
异步 API 还支持 `webhook` 回调通知,无需轮询。详见 [异步解析 API 文档](/api-reference/endpoint/xparse/v1/parse-async)。
***
## 理解返回结果
解析成功后,返回的核心数据结构如下:
```json theme={null}
{
"code": 200,
"message": "success",
"data": {
"schema_version": "1.3.0",
"file_id": "doc_7f3a2b",
"job_id": "job_x9k2m",
"success_count": 5,
"metadata": {
"filename": "document.pdf",
"filetype": "application/pdf",
"page_count": 5,
"data_source": {
"record_locator": {
"protocol": "file",
"remote_file_path": "/path/to/document.pdf"
},
"url": "file:///path/to/document.pdf"
}
},
"markdown": "# 文档标题\n\n这是正文内容...\n\n| 列1 | 列2 |\n|---|---|\n| 值1 | 值2 |",
"elements": [
{
"element_id": "el_001",
"type": "Title",
"text": "文档标题",
"page_number": 1,
"coordinates": [0.100000, 0.120000, 0.320000, 0.120000, 0.320000, 0.160000, 0.100000, 0.160000],
"metadata": {
"category_depth": 0,
"children_ids": ["el_002"],
"is_continuation": false,
"data_source": {
"record_locator": {
"protocol": "file",
"remote_file_path": "/path/to/document.pdf"
},
"url": "file:///path/to/document.pdf"
}
}
},
{
"element_id": "el_002",
"type": "NarrativeText",
"text": "这是正文内容...",
"page_number": 1,
"coordinates": [0.100000, 0.180000, 0.900000, 0.180000, 0.900000, 0.220000, 0.100000, 0.220000],
"metadata": {
"parent_id": "el_001",
"is_continuation": false,
"data_source": {
"record_locator": {
"protocol": "file",
"remote_file_path": "/path/to/document.pdf"
},
"url": "file:///path/to/document.pdf"
}
}
}
]
}
}
```
| 字段 | 说明 |
| ---------------- | ------------------------------ |
| `schema_version` | 数据结构版本号,当前为 `"1.3.0"` |
| `file_id` | 文件唯一标识 |
| `job_id` | 任务唯一标识 |
| `success_count` | 成功解析的页数(计费依据) |
| `metadata` | 文件元信息(文件名、类型、页数、数据源等) |
| `markdown` | 文档的 Markdown 表示,可直接用于 LLM 输入 |
| `elements` | 文档元素列表,每个元素包含类型、文本、坐标、元信息等详细信息 |
更详细的返回结构说明请参考 [返回结构详解](/xparse/v1/parse-response)。
***
## 下一步
深入了解所有输入参数配置,包括能力开关、处理范围、引擎选择等
了解 Elements、坐标、表格结构等完整返回字段
SDK 高级用法:异步任务、错误处理、自定义配置
完整的 API 参数与响应说明
使用异步 API 处理大文件和批量任务
了解定价与计费规则
# Python SDK
Source: https://docs.textin.com/xparse/v1/sdk-python
使用 xparse-client Python SDK 快速集成文档解析能力
`xparse-client` 是 TextIn xParse 的官方 Python SDK,提供同步解析、异步任务管理、类型安全的响应模型和完善的错误处理,基于[最新版 API](/api-reference/endpoint/xparse/v1/parse-sync) 封装。
* PyPI: [xparse-client](https://pypi.org/project/xparse-client/)
## 安装
```bash pip theme={null}
pip install xparse-client
```
```bash uv theme={null}
uv add xparse-client
```
**系统要求:** Python >= 3.9
## 认证与初始化
SDK 支持多种认证方式(优先级:构造参数 > 环境变量 > .env 文件):
```python 环境变量(推荐) theme={null}
import os
os.environ["TEXTIN_APP_ID"] = "your-app-id"
os.environ["TEXTIN_SECRET_CODE"] = "your-secret-code"
from xparse_client import XParseClient
client = XParseClient()
```
```python 直接传参 theme={null}
from xparse_client import XParseClient
client = XParseClient(
app_id="your-app-id",
secret_code="your-secret-code",
)
```
```python .env 文件 theme={null}
# 需要安装 dotenv 扩展: pip install xparse-client[dotenv]
# .env 文件内容:
# TEXTIN_APP_ID=your-app-id
# TEXTIN_SECRET_CODE=your-secret-code
from xparse_client import XParseClient
client = XParseClient()
```
推荐使用环境变量方式,避免在代码中硬编码密钥。
## API 概览
| 方法 | 说明 | 返回类型 |
| --------------------------- | ---------- | ------------------- |
| `client.parse.run()` | 同步解析文档 | `ParseResponse` |
| `client.parse.create_job()` | 创建异步解析任务 | `AsyncJobResponse` |
| `client.parse.get_job()` | 查询异步任务状态 | `JobStatusResponse` |
| `client.parse.wait_job()` | 轮询等待异步任务完成 | `JobStatusResponse` |
## 同步解析
适用于一般大小的文档,直接返回解析结果。
```python theme={null}
from xparse_client import XParseClient, ParseConfig, Capabilities, Scope
client = XParseClient()
with open("document.pdf", "rb") as f:
result = client.parse.run(
file=f,
filename="document.pdf",
config=ParseConfig(
capabilities=Capabilities(
include_table_structure=True, # 返回表格详细结构
include_image_data=True, # 返回图片数据
title_tree=True, # 返回目录树
pages=True, # 返回页面元信息
),
scope=Scope(page_range="1-10"), # 指定解析页面范围
),
)
# 输出 Markdown
print(result.markdown)
# 遍历元素
for el in result.elements:
print(f"[{el.type}] p{el.page_number}: {el.text[:60]}")
```
### 解析配置参数
`ParseConfig` 支持以下配置:
| 参数 | 类型 | 说明 |
| -------------------------------------- | ------------------------ | ----------------------- |
| `capabilities.include_hierarchy` | bool | 返回元素父子关系 |
| `capabilities.include_inline_objects` | bool | 返回行内对象(公式、手写体、复选框) |
| `capabilities.include_char_details` | bool | 返回字符级坐标和置信度 |
| `capabilities.include_image_data` | bool | 返回图片 URL、MIME 类型、OCR 文本 |
| `capabilities.include_table_structure` | bool | 返回表格行/列/单元格详细结构 |
| `capabilities.pages` | bool | 返回页面元信息列表 |
| `capabilities.title_tree` | bool | 返回文档目录树 |
| `capabilities.table_view` | `"markdown"` \| `"html"` | 表格视图格式 |
| `scope.page_range` | string | 解析页面范围,如 `"1-10"` |
| `document.password` | string | 加密 PDF 的密码 |
## 异步解析
适用于大文件或批量处理场景。
### 创建任务并等待结果
```python theme={null}
client = XParseClient()
# 创建异步任务
with open("large_document.pdf", "rb") as f:
job = client.parse.create_job(
file=f,
filename="large_document.pdf",
webhook="https://example.com/callback", # 可选:完成后回调通知
)
print(f"任务已创建: {job.job_id}")
# 等待任务完成(自动轮询)
result = client.parse.wait_job(
job_id=job.job_id,
timeout=300.0, # 超时时间(秒)
poll_interval=5.0, # 轮询间隔(秒)
)
if result.is_completed:
# 异步任务返回 result_url,需单独下载获取解析结果
import httpx
resp = httpx.get(result.result_url)
print(resp.json())
```
### 手动查询任务状态
```python theme={null}
status = client.parse.get_job(job_id="your-job-id")
print(f"状态: {status.status}") # pending | in_progress | completed | failed
```
## 错误处理
SDK 提供了完善的错误分类,方便您精确处理不同的异常情况。
### 错误类型
| 错误类 | 说明 |
| -------------------------- | ----------------------------- |
| `XParseClientError` | 基础错误类,捕获所有 SDK 错误 |
| `ValidationError` | 客户端参数校验失败 |
| `AuthenticationError` | 认证失败(app-id 或 secret-code 错误) |
| `PermissionDeniedError` | IP 不在白名单 |
| `InsufficientBalanceError` | 余额不足 |
| `InvalidParameterError` | 参数错误 |
| `UnsupportedFileTypeError` | 不支持的文件类型 |
| `FileSizeError` | 文件超过 500MB 限制 |
| `CorruptedFileError` | 文件损坏 |
| `PasswordProtectedError` | PDF 需要密码 |
| `ServerError` | 服务端错误(HTTP 5xx) |
| `ServiceUnavailableError` | 服务暂时不可用 |
### 错误处理示例
```python theme={null}
from xparse_client.exceptions import (
XParseClientError,
BusinessError,
AuthenticationError,
APIError,
)
try:
with open("document.pdf", "rb") as f:
result = client.parse.run(file=f, filename="document.pdf")
except AuthenticationError as e:
print(f"认证失败: {e.message}")
except BusinessError as e:
print(f"业务错误 [{e.business_code}]: {e.message}")
print(f"请求ID: {e.x_request_id}") # 用于技术支持排查
except APIError as e:
print(f"API错误 [HTTP {e.status_code}]: {e.message}")
except XParseClientError as e:
print(f"SDK错误: {e.message}")
```
### 获取请求 ID
每个 API 请求都会返回 `x_request_id`,可用于联系技术支持排查问题:
```python theme={null}
result = client.parse.run(file=f, filename="document.pdf")
print(f"请求ID: {result.x_request_id}")
```
## 高级配置
### 超时与重试
```python theme={null}
client = XParseClient(
timeout=120.0, # 请求超时(秒),默认 630
max_retries=3, # 最大重试次数,默认 3
)
```
### 自定义 API 地址
```python theme={null}
client = XParseClient(
server_url="https://custom-api.example.com"
)
```
### 自定义 HTTP 客户端
支持代理、自定义 SSL 证书等场景:
```python theme={null}
import httpx
http_client = httpx.Client(
proxy="http://proxy.example.com:8080",
verify="/path/to/custom-ca.pem",
)
client = XParseClient(
app_id="your-app-id",
secret_code="your-secret-code",
http_client=http_client,
)
```
### 资源管理
使用上下文管理器自动关闭连接:
```python theme={null}
with XParseClient() as client:
result = client.parse.run(...)
# 退出时自动关闭连接
```
## 调试日志
启用 DEBUG 级别日志查看请求详情:
```python theme={null}
import logging
logging.getLogger("xparse_client").setLevel(logging.DEBUG)
```
## 常见问题
| 问题 | 解决方案 |
| --------------------- | ---------------------------------------------- |
| `AuthenticationError` | 检查 `TEXTIN_APP_ID` 和 `TEXTIN_SECRET_CODE` 是否正确 |
| `FileSizeError` | 文件大小限制为 500MB |
| `TimeoutException` | 增大超时时间:`XParseClient(timeout=300.0)` |
## 相关链接
* [PyPI 主页](https://pypi.org/project/xparse-client/)
* [API 参考:同步解析](/api-reference/endpoint/xparse/v1/parse-sync)
* [API 参考:异步解析](/api-reference/endpoint/xparse/v1/parse-async)
# 智能文档助手 Agent:自动解析与智能问答
Source: https://docs.textin.com/xparse/v1/tutorials/agent-tutorial
使用 xParse SDK + LangChain Agent 构建智能文档助手,实现文档自动解析、知识库更新和智能问答的一体化流程。
本教程将展示如何构建一个智能文档助手,它能够:
* 自动解析新上传的文档并更新知识库
* 根据用户问题智能检索相关文档内容
* 自动决定何时需要解析新文档,何时直接检索回答
## 什么是智能文档助手?
想象这样一个场景:你的团队每天都会上传新的合同、FAQ、产品手册等文档到云存储。你希望有一个 AI 助手能够:
1. **自动处理新文档**:当有新文档上传时,自动解析并存入知识库
2. **智能回答问题**:当用户提问时,自动从知识库中找到相关内容并回答
3. **自动判断**:如果知识库中没有相关信息,自动触发文档解析;如果有,直接检索回答
这就是我们要构建的智能文档助手。
## 工作原理
整个系统的工作流程如下:
```
用户提问:"最新版本的新功能有哪些?"
↓
[LangChain Agent] 分析问题
↓
Agent 判断:需要先检索知识库
↓
[Tool: vector_search] 在向量库中搜索
↓
结果:没找到最新版本的信息
↓
Agent 判断:需要解析新文档
↓
[Tool: run_xparse_client] 调用 xParse SDK 解析文档,LangChain 分块+向量化后更新知识库
↓
再次检索,找到相关内容
↓
Agent 组织回答并返回给用户
```
## 环境准备
首先安装必要的依赖:
```bash theme={null}
python -m venv .venv && source .venv/bin/activate
pip install xparse-client langchain langchain-community langchain-core langchain-text-splitters langchain-milvus \
python-dotenv dashscope
```
创建 `.env` 文件存储配置:
```bash theme={null}
# .env
TEXTIN_APP_ID=your-app-id
TEXTIN_SECRET_CODE=your-secret-code
MILVUS_DB_PATH=./agent_vectors.db
DASHSCOPE_API_KEY=your-dashscope-key
```
> 提示:`TEXTIN_APP_ID` 与 `TEXTIN_SECRET_CODE` 参考 [API Key](/xparse/api-key),请登录 [Textin 工作台](https://www.textin.com/console/dashboard/setting) 获取。示例中使用 `通义千问` 的大模型能力,其他模型用法类似。
## 完整代码示例
```python expandable theme={null}
import os
import glob
from dotenv import load_dotenv
from xparse_client import XParseClient
from langchain_text_splitters import MarkdownHeaderTextSplitter, RecursiveCharacterTextSplitter
from langchain_core.tools import Tool
from langchain_core.documents import Document
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
from langchain_classic.agents import AgentType, initialize_agent
from langchain_community.chat_models import ChatTongyi
# 加载环境变量
load_dotenv()
# ========== Step 1: 初始化 xParse SDK 客户端 ==========
DOCS_DIR = "/your/doc/folder"
client = XParseClient()
headers_to_split_on = [("#", "header1"), ("##", "header2"), ("###", "header3")]
markdown_splitter = MarkdownHeaderTextSplitter(headers_to_split_on=headers_to_split_on)
text_splitter = RecursiveCharacterTextSplitter(chunk_size=1500, chunk_overlap=80)
def process_single_file(file_path: str) -> str:
"""处理单个文件并存入知识库"""
try:
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
md_docs = markdown_splitter.split_text(result.markdown)
for doc in md_docs:
doc.metadata["filename"] = os.path.basename(file_path)
chunks = text_splitter.split_documents(md_docs)
embedding = DashScopeEmbeddings(model="text-embedding-v4")
Milvus.from_documents(
documents=chunks,
embedding=embedding,
collection_name="agent_docs",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
return f"✅ 成功处理文件 {file_path} 并已存入知识库。"
except Exception as e:
return f"❌ 处理文件 {file_path} 时出错:{str(e)}"
def build_knowledge_base() -> str:
"""解析目录中的所有文档并构建知识库"""
try:
all_chunks = []
for file_path in glob.glob(os.path.join(DOCS_DIR, "*")):
if not os.path.isfile(file_path):
continue
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
md_docs = markdown_splitter.split_text(result.markdown)
for doc in md_docs:
doc.metadata["filename"] = os.path.basename(file_path)
chunks = text_splitter.split_documents(md_docs)
all_chunks.extend(chunks)
embedding = DashScopeEmbeddings(model="text-embedding-v4")
Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="agent_docs",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
return f"✅ 已处理所有文件并已存入知识库。"
except Exception as e:
return f"❌ 构建知识库时出错:{str(e)}"
# ========== Step 2: 初始化向量数据库 ==========
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus(
embedding_function=embedding,
collection_name="agent_docs",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
# ========== Step 3: 构建 LangChain Tools ==========
def pipeline_tool_fn(doc_hint: str) -> str:
"""
文档处理工具:根据输入决定处理单个文件还是整个目录
输入示例:
- "处理 contracts/2025Q1/contract.pdf" -> 处理单个文件
- "更新所有文档" 或 "同步文档库" -> 处理整个目录
"""
if doc_hint and ("/" in doc_hint or "\\" in doc_hint):
file_path = doc_hint.strip()
return process_single_file(file_path)
else:
return build_knowledge_base()
def search_tool_fn(query: str) -> str:
"""
向量检索工具:在知识库中搜索相关内容
返回格式化的检索结果,包含文档来源和内容
"""
docs = vector_store.similarity_search(query, k=4)
if not docs:
return "❌ 在知识库中未找到相关内容。建议先运行文档解析工具更新知识库。"
results = []
for i, doc in enumerate(docs, 1):
filename = doc.metadata.get('filename', '未知文件')
header1 = doc.metadata.get('header1', '')
header2 = doc.metadata.get('header2', '')
section = f" > {header1}" if header1 else ""
section += f" > {header2}" if header2 else ""
content = doc.page_content[:500]
results.append(f"[{i}] 来源:{filename}{section}\n内容:{content}...")
return "\n\n".join(results)
# 定义工具列表
tools = [
Tool(
name="run_xparse_client",
description="当需要解析新文档或更新知识库时使用此工具。输入可以是文件路径(如 'contracts/doc.pdf')或更新指令(如 '更新所有文档')。",
func=pipeline_tool_fn
),
Tool(
name="vector_search",
description="当需要基于知识库内容回答问题时使用此工具。输入是用户的自然语言问题,工具会在知识库中搜索相关内容。",
func=search_tool_fn
)
]
# ========== Step 4: 初始化 Agent ==========
llm = ChatTongyi(
model="qwen-max",
top_p=0.8,
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY")
)
agent = initialize_agent(
tools=tools,
llm=llm,
agent=AgentType.ZERO_SHOT_REACT_DESCRIPTION,
verbose=True, # 显示 Agent 的思考过程
)
# ========== Step 5: 使用示例 ==========
if __name__ == "__main__":
# 示例 1: 用户提问,Agent 会自动检索知识库
print("=" * 60)
print("示例 1: 用户提问")
print("=" * 60)
response = agent.invoke({
"input": "如何安装milvus?"
})
print(response["output"])
print()
# 示例 2: 用户要求更新文档,Agent 会调用解析工具
print("=" * 60)
print("示例 2: 更新文档库")
print("=" * 60)
response = agent.invoke({
"input": "请更新所有文档到知识库"
})
print(response["output"])
print()
# 示例 3: 用户提问但知识库中没有,Agent 会先解析再检索
print("=" * 60)
print("示例 3: 智能判断")
print("=" * 60)
response = agent.invoke({
"input": "最新版本的新功能有哪些?如果没有相关信息,请先解析 Milvus_DEVELOPMENT.pdf"
})
print(response["output"])
```
## 代码说明
### Step 1: xParse SDK 客户端初始化
`XParseClient` 用于初始化 xParse 客户端,它会从环境变量中读取 `TEXTIN_APP_ID` 和 `TEXTIN_SECRET_CODE` 进行认证。调用 `client.parse.run()` 即可将文档解析为 Markdown,然后使用 LangChain 的 `MarkdownHeaderTextSplitter` 按标题层级分块,再用 `RecursiveCharacterTextSplitter` 控制块的大小,最后通过 `DashScopeEmbeddings` 向量化后存入 Milvus。
**重要**:`XParseClient` 只需要初始化一次,可以在全局复用。
### Step 2: 向量数据库
向量数据库用于存储文档的向量表示,支持语义搜索。**关键点**:检索时必须使用与构建知识库时相同的 embedding 模型,否则语义空间不一致,检索效果会变差。
### Step 3: LangChain Tools
Tools 是 Agent 可以调用的函数。我们定义了两个工具:
1. **`run_xparse_client`**:处理文档的工具
* 如果输入是文件路径,处理单个文件
* 如果输入是更新指令,处理整个目录
2. **`vector_search`**:检索知识库的工具
* 根据用户问题在向量库中搜索相关内容
* 返回格式化的结果,包含文档来源
### Step 4: Agent 初始化
Agent 是"大脑",它会:
* 理解用户的问题
* 决定调用哪个工具
* 根据工具返回结果组织最终回答
### Step 5: 使用
Agent 会自动判断:
* 用户提问 → 先检索知识库
* 知识库没有答案 → 调用解析工具更新知识库,再检索
* 用户要求更新 → 直接调用解析工具
## 实际应用场景
### 场景 1: 客服助手
**需求**:客服团队经常收到产品相关问题,需要快速从 FAQ 和产品手册中找到答案。
**实现**:
* 将 FAQ 和产品手册放在 `./documents/faqs/` 目录
* 用户提问时,Agent 自动检索并回答
* 有新版本文档时,Agent 自动更新知识库
### 场景 2: 合同管理
**需求**:法务团队需要快速查找合同中的特定条款。
**实现**:
* 将合同文档放在 `./documents/contracts/` 目录
* xParse 解析后按 Markdown 标题分块,保持章节完整性
* 用户提问"违约条款",Agent 自动检索相关章节
### 场景 3: 知识库维护
**需求**:定期更新知识库,确保信息是最新的。
**实现**:
* 设置定时任务,定期调用 `build_knowledge_base()`
* 或者通过 Agent 接口,用户说"更新文档库",Agent 自动处理
## 进阶优化
### 1. 添加对话历史
让 Agent 记住之前的对话:
```python theme={null}
from langchain.memory import ConversationBufferMemory
# 创建记忆组件
memory = ConversationBufferMemory(memory_key="chat_history", return_messages=True)
# 在初始化 Agent 时添加记忆
agent = initialize_agent(
tools=tools,
llm=llm,
agent=AgentType.ZERO_SHOT_REACT_DESCRIPTION,
verbose=True,
memory=memory # 添加记忆组件
)
def chat_with_agent(query: str):
"""Agent 会自动使用 memory 记住对话历史"""
response = agent.invoke({
"input": query
})
return response["output"]
```
### 2. 添加限流保护
避免频繁调用文档解析:
```python theme={null}
import time
from datetime import datetime, timedelta
last_run_time = None
MIN_INTERVAL = timedelta(minutes=10) # 最小间隔10分钟
def pipeline_tool_fn(doc_hint: str) -> str:
global last_run_time
# 检查是否在冷却期
if last_run_time and datetime.now() - last_run_time < MIN_INTERVAL:
return "⚠️ 文档解析刚刚运行过,请稍后再试(建议间隔10分钟以上)。"
# 执行处理
result = process_single_file(doc_hint) if "/" in doc_hint else build_knowledge_base()
last_run_time = datetime.now()
return result
```
### 3. 添加引用来源
在回答中标注信息来源:
```python theme={null}
def search_tool_fn(query: str) -> str:
docs = vector_store.similarity_search(query, k=4)
if not docs:
return "❌ 在知识库中未找到相关内容。"
results = []
sources = [] # 收集来源信息
for i, doc in enumerate(docs, 1):
filename = doc.metadata.get('filename', '未知文件')
header1 = doc.metadata.get('header1', '')
sources.append(f"{filename}#{header1}")
results.append(f"[{i}] {filename} ({header1})\n{doc.page_content[:500]}...")
# 在结果末尾添加来源列表
results.append(f"\n📚 参考来源:{', '.join(sources)}")
return "\n\n".join(results)
```
## 常见问题
**Q: 长文档解析时间长,会影响用户体验吗?**
A: 是的,如果文档很大,解析可能需要一些时间。建议:
* 对于大文档,使用异步处理,先返回"任务已提交"
* 或者限制单次处理的文件数量
**Q: 如何让 Agent 只检索,不自动触发解析?**
A: 修改 Tool 的 description,明确说明使用场景,或者添加一个开关参数。
**Q: 向量数据库中的数据会过期吗?**
A: 不会自动过期。如果需要更新,需要重新调用 `build_knowledge_base()` 构建知识库,新数据会追加到向量库中。
**Q: 可以使用其他 LLM 吗?**
A: 可以。LangChain 支持多种 LLM,只需替换 `ChatTongyi`(通义千问) 为对应的类,如 `ChatOpenAI`(OpenAI)、`ChatZhipuAI`(智谱AI)等。
**Q: 如何实现增量处理?**
A: 可以通过 `process_single_file()` 逐个处理新增文档,也可以自行维护已处理文件列表来实现增量逻辑。
## 总结
通过本教程,你已经学会了如何构建一个智能文档助手。核心思路是:
1. **xParse SDK 负责解析**:调用 `client.parse.run()` 将文档解析为 Markdown,再通过 LangChain 进行分块、向量化并存入数据库
2. **Agent 负责决策**:根据用户问题,决定调用哪个工具
3. **Tools 负责执行**:具体的文档处理和检索操作
这样,你就有了一个"能自己跑文档"的 AI 助手!
# xParse + LangGraph 构建 Agentic RAG
Source: https://docs.textin.com/xparse/v1/tutorials/agentic-rag-tutorial
使用 xParse SDK + LangGraph 构建 Agentic RAG,智能重写问题、检索与回答,实现更准确的企业知识问答
本教程将带您了解如何使用 [xParse SDK](/xparse/v1/sdk-python) + LangGraph 构建 Agentic RAG,智能重写问题、检索与回答,实现更准确的企业知识问答。
## 什么是 Agentic RAG?
Agentic RAG(Retrieval-Augmented Generation)是一种结合信息检索和生成式 AI 的技术。与传统的 RAG 不同,Agentic RAG 通过智能决策机制,能够:
1. **智能判断**:判断问题是否需要检索,还是可以直接回答
2. **问题重写**:当检索结果不相关时,自动重写问题以获取更好的结果
3. **相关性评估**:评估检索到的文档片段是否与问题相关
4. **迭代优化**:通过多轮检索和重写,逐步优化答案质量
Agentic RAG 的核心流程包括:
1. **文档处理**:将非结构化文档转换为向量表示
2. **向量存储**:将向量数据存储到向量数据库
3. **智能检索**:根据用户问题智能检索相关文档片段
4. **问题重写**:当检索结果不相关时,重写问题再次检索
5. **生成回答**:基于检索到的相关上下文生成高质量答案
## Agentic RAG 工作流程
```
用户问题:"如何配置数据库连接池?"
↓
[LangGraph 工作流] ← [xParse SDK]
↓
[判断节点] 是否需要检索?
├─ 是 → [检索节点] 向量检索
│ ↓
│ [评估节点] 检索结果是否相关?
│ ├─ 相关 → [生成节点] 生成答案
│ └─ 不相关 → [重写节点] 重写问题
│ ↓
│ [检索节点] 再次检索
│ ↓
│ [评估节点] 再次评估
│ ↓
│ [生成节点] 生成答案
└─ 否 → [生成节点] 直接生成答案
```
## 环境准备
首先安装必要的依赖:
```bash theme={null}
python -m venv .venv && source .venv/bin/activate
pip install xparse-client langchain langchain-community langchain-core \
langchain-text-splitters langgraph langchain-milvus python-dotenv
```
创建 `.env` 文件存储配置:
```bash theme={null}
# .env
TEXTIN_APP_ID=your-app-id
TEXTIN_SECRET_CODE=your-secret-code
MILVUS_DB_PATH=./agentic_rag_vectors.db
DASHSCOPE_API_KEY=your-dashscope-key
```
> 提示:`TEXTIN_APP_ID` 与 `TEXTIN_SECRET_CODE` 参考 [API Key](/xparse/api-key),请登录 [Textin 工作台](https://www.textin.com/console/dashboard/setting) 获取。示例中使用 `通义千问` 的大模型能力,其他模型用法类似。
下面我们将分步骤构建 Agentic RAG 系统。首先导入必要的库:
```python theme={null}
import os
import glob
from typing import TypedDict, Annotated
from dotenv import load_dotenv
from xparse_client import XParseClient
from langchain_text_splitters import MarkdownHeaderTextSplitter, RecursiveCharacterTextSplitter
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
from langchain_community.chat_models import ChatTongyi
from langchain_core.documents import Document
from langgraph.graph import StateGraph, END
from langgraph.graph.message import add_messages
from langchain_core.messages import HumanMessage, BaseMessage
load_dotenv()
```
### Step 1: 使用 xParse SDK 构建知识库
首先,我们需要使用 [xParse SDK](/xparse/v1/sdk-python) 解析文档,再通过 LangChain 进行分块和向量化,最终存入 Milvus 向量数据库。这是知识库构建的基础步骤。
初始化 xParse 客户端并构建知识库:
```python theme={null}
client = XParseClient()
def build_knowledge_base():
"""构建知识库"""
print("开始构建知识库...")
docs_dir = "./knowledge_base"
headers_to_split_on = [("#", "header1"), ("##", "header2"), ("###", "header3")]
markdown_splitter = MarkdownHeaderTextSplitter(headers_to_split_on=headers_to_split_on)
text_splitter = RecursiveCharacterTextSplitter(chunk_size=1500, chunk_overlap=80)
all_chunks = []
for file_path in glob.glob(os.path.join(docs_dir, "*")):
if not os.path.isfile(file_path):
continue
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
md_docs = markdown_splitter.split_text(result.markdown)
for doc in md_docs:
doc.metadata["filename"] = os.path.basename(file_path)
chunks = text_splitter.split_documents(md_docs)
all_chunks.extend(chunks)
embedding = DashScopeEmbeddings(model="text-embedding-v4")
Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="agentic_rag_docs",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
print("知识库构建完成!")
```
### Step 2: 初始化向量数据库和大模型
接下来,我们需要初始化向量数据库和大模型。**重要**:向量数据库必须使用与构建知识库时相同的 embedding 模型,以确保语义空间一致。
```python theme={null}
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus(
embedding_function=embedding,
collection_name="agentic_rag_docs",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
llm = ChatTongyi(
model="qwen-max",
top_p=0.8,
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY")
)
```
### Step 3: 定义状态结构
LangGraph 使用状态来管理工作流中的数据流。我们需要定义一个 `GraphState` 来存储工作流中的各种信息:
```python theme={null}
class GraphState(TypedDict):
"""工作流状态"""
messages: Annotated[list[BaseMessage], add_messages]
question: str # 原始问题
rewritten_question: str # 重写后的问题
documents: list # 检索到的文档
generation: str # 生成的答案
next: str # 下一步操作
retrieval_count: int # 检索次数
```
状态字段说明:
* `question`:用户提出的原始问题
* `rewritten_question`:重写后的问题(用于优化检索)
* `documents`:检索到的相关文档片段
* `generation`:最终生成的答案
* `next`:指示下一步应该执行哪个节点
* `retrieval_count`:检索次数(用于防止无限循环)
### Step 4: 定义节点函数
工作流由多个节点组成,每个节点负责特定的任务。让我们逐个实现这些节点:
#### 4.1 判断是否需要检索
`should_retrieve` 节点使用 LLM 判断问题是否需要从知识库检索信息:
```python theme={null}
def should_retrieve(state: GraphState) -> GraphState:
"""判断是否需要检索"""
question = state["question"]
prompt = f"""判断以下问题是否需要从知识库中检索信息才能回答。
问题:{question}
如果问题需要特定的文档、数据或知识库信息才能回答,返回 "retrieve"。
如果问题是一般性对话、问候或不需要特定信息的简单问题,返回 "generate"。
只返回 "retrieve" 或 "generate",不要返回其他内容。"""
response = llm.invoke([HumanMessage(content=prompt)])
decision = response.content.strip().lower()
next_step = "retrieve" if "retrieve" in decision else "generate"
return {
**state,
"next": next_step
}
```
#### 4.2 检索相关文档
`retrieve` 节点使用向量检索在知识库中查找相关内容:
```python theme={null}
def retrieve(state: GraphState) -> GraphState:
"""检索相关文档"""
question = state.get("rewritten_question") or state["question"]
retrieval_count = state.get("retrieval_count", 0)
docs = vector_store.similarity_search(question, k=5)
documents = []
for doc in docs:
documents.append({
"content": doc.page_content,
"metadata": doc.metadata
})
return {
**state,
"documents": documents,
"retrieval_count": retrieval_count + 1
}
```
注意:这里优先使用 `rewritten_question`(如果存在),否则使用原始问题。每次检索后,`retrieval_count` 会增加 1。
#### 4.3 评估检索结果的相关性
`grade_documents` 节点评估检索到的文档是否与问题相关:
```python theme={null}
def grade_documents(state: GraphState) -> GraphState:
"""评估检索结果的相关性"""
question = state.get("rewritten_question") or state["question"]
documents = state["documents"]
retrieval_count = state.get("retrieval_count", 0)
if retrieval_count >= 2:
return {
**state,
"next": "generate"
}
if not documents:
return {
**state,
"next": "rewrite"
}
docs_text = "\n\n".join([
f"文档 {i+1}:\n{doc['content'][:300]}..."
for i, doc in enumerate(documents[:3])
])
prompt = f"""评估以下检索到的文档是否与问题相关。
问题:{question}
检索到的文档:
{docs_text}
如果文档与问题高度相关,能够回答问题,返回 "generate"。
如果文档与问题不相关或相关性很低,返回 "rewrite"。
只返回 "generate" 或 "rewrite",不要返回其他内容。"""
response = llm.invoke([HumanMessage(content=prompt)])
decision = response.content.strip().lower()
next_step = "generate" if "generate" in decision else "rewrite"
return {
**state,
"next": next_step
}
```
如果文档不相关,将触发问题重写。为了避免无限循环,当检索次数达到 2 次时,即使文档不相关也会强制生成答案。
#### 4.4 重写问题
`rewrite_question` 节点基于检索结果或原始问题,生成更优化的查询:
```python theme={null}
def rewrite_question(state: GraphState) -> GraphState:
"""重写问题"""
question = state["question"]
documents = state.get("documents", [])
if documents:
docs_summary = "\n".join([
f"- {doc['content'][:200]}..."
for doc in documents[:2]
])
prompt = f"""原始问题:{question}
当前检索到的文档摘要:
{docs_summary}
这些文档与问题不够相关。请重写问题,使其能够更好地匹配知识库中的内容。
重写时应该:
1. 保持问题的核心意图
2. 使用更具体的关键词
3. 考虑知识库可能使用的术语
只返回重写后的问题,不要返回其他内容。"""
else:
prompt = f"""原始问题:{question}
请重写这个问题,使其更具体、更清晰,便于在知识库中检索相关信息。
重写时应该:
1. 保持问题的核心意图
2. 使用更具体的关键词
3. 考虑知识库可能使用的术语
只返回重写后的问题,不要返回其他内容。"""
response = llm.invoke([HumanMessage(content=prompt)])
rewritten = response.content.strip()
return {
**state,
"rewritten_question": rewritten
}
```
#### 4.5 生成答案
`generate` 节点基于检索结果或直接生成答案:
```python theme={null}
def generate(state: GraphState) -> GraphState:
"""生成答案"""
question = state["question"]
documents = state.get("documents", [])
if documents:
context = "\n\n".join([
f"文档来源:{doc['metadata'].get('filename', '未知')}\n内容:{doc['content']}"
for i, doc in enumerate(documents)
])
prompt = f"""基于以下文档内容回答用户问题。
文档内容:
{context}
用户问题:{question}
请基于文档内容回答问题。如果文档中没有相关信息,请说明。
在回答中引用具体的文档来源。"""
else:
prompt = f"""回答以下问题:{question}"""
response = llm.invoke([HumanMessage(content=prompt)])
return {
**state,
"generation": response.content
}
```
### Step 5: 构建 LangGraph 工作流
现在我们将所有节点组合成一个完整的工作流:
```python theme={null}
workflow = StateGraph(GraphState)
workflow.add_node("should_retrieve", should_retrieve)
workflow.add_node("retrieve", retrieve)
workflow.add_node("grade_documents", grade_documents)
workflow.add_node("rewrite_question", rewrite_question)
workflow.add_node("generate", generate)
workflow.set_entry_point("should_retrieve")
workflow.add_conditional_edges(
"should_retrieve",
lambda state: state.get("next", "generate"),
{
"retrieve": "retrieve",
"generate": "generate"
}
)
workflow.add_edge("retrieve", "grade_documents")
workflow.add_conditional_edges(
"grade_documents",
lambda state: state.get("next", "generate"),
{
"generate": "generate",
"rewrite": "rewrite_question"
}
)
workflow.add_edge("rewrite_question", "retrieve")
workflow.add_edge("generate", END)
app = workflow.compile()
```
工作流逻辑:
1. 从 `should_retrieve` 开始
2. 如果需要检索,进入 `retrieve` → `grade_documents`
3. 如果文档相关,进入 `generate`;如果不相关,进入 `rewrite_question` → `retrieve`(循环)
4. 如果不需要检索,直接进入 `generate`
### Step 6: 使用示例
创建一个便捷的提问函数:
```python theme={null}
def ask_question(question: str) -> str:
"""提问并获取答案"""
initial_state = {
"messages": [HumanMessage(content=question)],
"question": question,
"rewritten_question": "",
"documents": [],
"generation": "",
"next": "",
"retrieval_count": 0
}
result = app.invoke(initial_state)
return result["generation"]
```
使用示例:
```python theme={null}
if __name__ == "__main__":
build_knowledge_base()
questions = [
"如何配置数据库连接池?",
"产品的定价策略是什么?",
"你好"
]
for question in questions:
print("=" * 60)
print(f"问题:{question}")
print("=" * 60)
answer = ask_question(question)
print(f"回答:{answer}\n")
```
## 完整代码示例
下面是一个完整的、可以直接运行的示例:
```python expandable theme={null}
import os
import glob
from typing import TypedDict, Annotated, Literal
from dotenv import load_dotenv
from xparse_client import XParseClient
from langchain_text_splitters import MarkdownHeaderTextSplitter, RecursiveCharacterTextSplitter
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
from langchain_community.chat_models import ChatTongyi
from langchain_core.documents import Document
from langgraph.graph import StateGraph, END
from langgraph.graph.message import add_messages
from langchain_core.messages import HumanMessage, AIMessage, BaseMessage
load_dotenv()
# ========== Step 1: 使用 xParse SDK 构建知识库 ==========
client = XParseClient()
def build_knowledge_base():
"""构建知识库"""
print("开始构建知识库...")
docs_dir = "./knowledge_base"
headers_to_split_on = [("#", "header1"), ("##", "header2"), ("###", "header3")]
markdown_splitter = MarkdownHeaderTextSplitter(headers_to_split_on=headers_to_split_on)
text_splitter = RecursiveCharacterTextSplitter(chunk_size=1500, chunk_overlap=80)
all_chunks = []
for file_path in glob.glob(os.path.join(docs_dir, "*")):
if not os.path.isfile(file_path):
continue
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
md_docs = markdown_splitter.split_text(result.markdown)
for doc in md_docs:
doc.metadata["filename"] = os.path.basename(file_path)
chunks = text_splitter.split_documents(md_docs)
all_chunks.extend(chunks)
embedding = DashScopeEmbeddings(model="text-embedding-v4")
Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="agentic_rag_docs",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
print("知识库构建完成!")
# ========== Step 2: 初始化向量数据库和大模型 ==========
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus(
embedding_function=embedding,
collection_name="agentic_rag_docs",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
llm = ChatTongyi(
model="qwen-max",
top_p=0.8,
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY")
)
# ========== Step 3: 定义状态结构 ==========
class GraphState(TypedDict):
"""工作流状态"""
messages: Annotated[list[BaseMessage], add_messages]
question: str # 原始问题
rewritten_question: str # 重写后的问题
documents: list # 检索到的文档
generation: str # 生成的答案
next: str # 下一步操作
retrieval_count: int # 检索次数
# ========== Step 4: 定义节点函数 ==========
def should_retrieve(state: GraphState) -> GraphState:
"""判断是否需要检索"""
question = state["question"]
prompt = f"""判断以下问题是否需要从知识库中检索信息才能回答。
问题:{question}
如果问题需要特定的文档、数据或知识库信息才能回答,返回 "retrieve"。
如果问题是一般性对话、问候或不需要特定信息的简单问题,返回 "generate"。
只返回 "retrieve" 或 "generate",不要返回其他内容。"""
response = llm.invoke([HumanMessage(content=prompt)])
decision = response.content.strip().lower()
next_step = "retrieve" if "retrieve" in decision else "generate"
return {
**state,
"next": next_step
}
def retrieve(state: GraphState) -> GraphState:
"""检索相关文档"""
question = state.get("rewritten_question") or state["question"]
retrieval_count = state.get("retrieval_count", 0)
docs = vector_store.similarity_search(question, k=5)
documents = []
for doc in docs:
documents.append({
"content": doc.page_content,
"metadata": doc.metadata
})
return {
**state,
"documents": documents,
"retrieval_count": retrieval_count + 1
}
def grade_documents(state: GraphState) -> GraphState:
"""评估检索结果的相关性"""
question = state.get("rewritten_question") or state["question"]
documents = state["documents"]
retrieval_count = state.get("retrieval_count", 0)
if retrieval_count >= 2:
return {
**state,
"next": "generate"
}
if not documents:
return {
**state,
"next": "rewrite"
}
docs_text = "\n\n".join([
f"文档 {i+1}:\n{doc['content'][:300]}..."
for i, doc in enumerate(documents[:3])
])
prompt = f"""评估以下检索到的文档是否与问题相关。
问题:{question}
检索到的文档:
{docs_text}
如果文档与问题高度相关,能够回答问题,返回 "generate"。
如果文档与问题不相关或相关性很低,返回 "rewrite"。
只返回 "generate" 或 "rewrite",不要返回其他内容。"""
response = llm.invoke([HumanMessage(content=prompt)])
decision = response.content.strip().lower()
next_step = "generate" if "generate" in decision else "rewrite"
return {
**state,
"next": next_step
}
def rewrite_question(state: GraphState) -> GraphState:
"""重写问题"""
question = state["question"]
documents = state.get("documents", [])
previous_rewrite = state.get("rewritten_question", "")
if documents:
docs_summary = "\n".join([
f"- {doc['content'][:200]}..."
for doc in documents[:2]
])
prompt = f"""原始问题:{question}
当前检索到的文档摘要:
{docs_summary}
这些文档与问题不够相关。请重写问题,使其能够更好地匹配知识库中的内容。
重写时应该:
1. 保持问题的核心意图
2. 使用更具体的关键词
3. 考虑知识库可能使用的术语
只返回重写后的问题,不要返回其他内容。"""
else:
prompt = f"""原始问题:{question}
请重写这个问题,使其更具体、更清晰,便于在知识库中检索相关信息。
重写时应该:
1. 保持问题的核心意图
2. 使用更具体的关键词
3. 考虑知识库可能使用的术语
只返回重写后的问题,不要返回其他内容。"""
response = llm.invoke([HumanMessage(content=prompt)])
rewritten = response.content.strip()
return {
**state,
"rewritten_question": rewritten
}
def generate(state: GraphState) -> GraphState:
"""生成答案"""
question = state["question"]
documents = state.get("documents", [])
if documents:
context = "\n\n".join([
f"文档来源:{doc['metadata'].get('filename', '未知')}\n内容:{doc['content']}"
for i, doc in enumerate(documents)
])
prompt = f"""基于以下文档内容回答用户问题。
文档内容:
{context}
用户问题:{question}
请基于文档内容回答问题。如果文档中没有相关信息,请说明。
在回答中引用具体的文档来源。"""
else:
prompt = f"""回答以下问题:{question}"""
response = llm.invoke([HumanMessage(content=prompt)])
return {
**state,
"generation": response.content
}
# ========== Step 5: 构建 LangGraph 工作流 ==========
workflow = StateGraph(GraphState)
workflow.add_node("should_retrieve", should_retrieve)
workflow.add_node("retrieve", retrieve)
workflow.add_node("grade_documents", grade_documents)
workflow.add_node("rewrite_question", rewrite_question)
workflow.add_node("generate", generate)
workflow.set_entry_point("should_retrieve")
workflow.add_conditional_edges(
"should_retrieve",
lambda state: state.get("next", "generate"),
{
"retrieve": "retrieve",
"generate": "generate"
}
)
workflow.add_edge("retrieve", "grade_documents")
workflow.add_conditional_edges(
"grade_documents",
lambda state: state.get("next", "generate"),
{
"generate": "generate",
"rewrite": "rewrite_question"
}
)
workflow.add_edge("rewrite_question", "retrieve")
workflow.add_edge("generate", END)
app = workflow.compile()
# ========== Step 6: 使用示例 ==========
def ask_question(question: str) -> str:
"""提问并获取答案"""
initial_state = {
"messages": [HumanMessage(content=question)],
"question": question,
"rewritten_question": "",
"documents": [],
"generation": "",
"next": "",
"retrieval_count": 0
}
result = app.invoke(initial_state)
return result["generation"]
if __name__ == "__main__":
build_knowledge_base()
questions = [
"如何配置数据库连接池?",
"产品的定价策略是什么?",
"你好"
]
for question in questions:
print("=" * 60)
print(f"问题:{question}")
print("=" * 60)
answer = ask_question(question)
print(f"回答:{answer}\n")
```
## 与普通 RAG 的区别
### 普通 RAG
```
用户问题 → 向量检索 → 生成答案
```
### Agentic RAG
```
用户问题 → 判断是否需要检索
├─ 需要 → 检索 → 评估相关性
│ ├─ 相关 → 生成答案
│ └─ 不相关 → 重写问题 → 重新检索 → ...
└─ 不需要 → 直接生成答案
```
**核心优势**:
1. **智能决策**:自动判断是否需要检索,避免不必要的检索
2. **质量保证**:评估检索结果的相关性,确保答案质量
3. **迭代优化**:通过问题重写,逐步优化检索结果
4. **灵活应对**:能够处理简单问题和复杂问题
## 实际应用场景
### 场景 1: 企业知识库问答
**需求**:员工可以通过自然语言提问,快速找到产品文档、技术文档等信息。
**实现**:
* 使用 xParse SDK 解析企业文档,通过 LangChain 分块和向量化
* Agentic RAG 自动判断问题类型
* 智能检索和重写,确保找到最相关的信息
### 场景 2: 客服助手
**需求**:客服团队需要快速回答客户问题,从 FAQ 和产品手册中找到答案。
**实现**:
* 将 FAQ 和产品手册存入知识库
* Agentic RAG 能够:
* 识别简单问候,直接回答
* 识别需要检索的问题,智能检索
* 当检索结果不相关时,自动优化查询
### 场景 3: 技术文档问答
**需求**:开发者可以通过自然语言提问,快速找到 API 文档、使用示例等。
**实现**:
* 使用 xParse SDK 解析文档后,通过 MarkdownHeaderTextSplitter 按标题层级分块,保持文档结构
* Agentic RAG 能够理解技术术语,重写查询以匹配文档中的关键词
## 进阶优化
### 1. 添加检索次数限制
避免无限循环重写和检索:
```python theme={null}
class GraphState(TypedDict):
# ... 其他字段
retrieval_count: int # 检索次数
def grade_documents(state: GraphState) -> GraphState:
"""评估检索结果的相关性"""
if state.get("retrieval_count", 0) >= 2:
return {
**state,
"next": "generate"
}
# ... 原有的评估逻辑
```
### 2. 添加对话历史
支持多轮对话:
```python theme={null}
class GraphState(TypedDict):
# ... 其他字段
chat_history: list[BaseMessage] # 对话历史
def generate(state: GraphState) -> GraphState:
"""生成答案"""
messages = state.get("chat_history", []) + [
HumanMessage(content=state["question"])
]
# ... 生成逻辑
```
### 3. 混合检索策略
结合向量检索和关键词检索:
```python theme={null}
def retrieve(state: GraphState) -> GraphState:
"""检索相关文档"""
question = state.get("rewritten_question") or state["question"]
vector_docs = vector_store.similarity_search(question, k=3)
# keyword_docs = keyword_search(question, k=2)
documents = []
for doc in vector_docs:
documents.append({
"content": doc.page_content,
"metadata": doc.metadata,
"source": "vector"
})
return {
**state,
"documents": documents
}
```
### 4. 添加引用来源
在答案中标注信息来源:
```python theme={null}
def generate(state: GraphState) -> GraphState:
"""生成答案"""
# ... 生成逻辑
if documents:
sources = [
doc['metadata'].get('filename', '未知')
for doc in documents
]
generation_with_sources = f"{generation}\n\n参考来源:{', '.join(set(sources))}"
return {
**state,
"generation": generation_with_sources
}
```
## 常见问题
**Q: Agentic RAG 比普通 RAG 慢吗?**
A: 可能会稍慢一些,因为增加了判断和评估步骤。但通过智能决策,可以避免不必要的检索,整体效率可能更高。
**Q: 如何控制重写次数?**
A: 在 `grade_documents` 函数中添加检索次数限制,避免无限循环。
**Q: 可以使用其他 LLM 吗?**
A: 可以。LangChain 支持多种 LLM,只需替换 `ChatTongyi` 为对应的类,如 `ChatOpenAI`(OpenAI)、`ChatZhipuAI`(智谱AI)等。
**Q: 如何提高检索质量?**
A:
1. 优化分块策略,确保文档块大小和重叠合适
2. 使用高质量的 embedding 模型(如 `text-embedding-v4`)
3. 调整检索数量(`k` 值)
4. 优化问题重写的提示词
**Q: 如何处理多轮对话?**
A: 在状态中添加 `chat_history` 字段,在生成答案时考虑历史对话上下文。
## 总结
通过本教程,您已经学会了如何构建一个 Agentic RAG 系统。核心思路是:
1. **xParse SDK 负责文档解析**:使用 [xParse SDK](/xparse/v1/sdk-python) 将文档转换为 Markdown,再通过 LangChain 分块和向量化构建知识库
2. **LangGraph 负责工作流**:构建智能的检索和生成流程
3. **智能决策**:通过判断、评估、重写等步骤,逐步优化答案质量
相比普通 RAG,Agentic RAG 能够:
* 智能判断是否需要检索
* 评估检索结果的相关性
* 自动重写问题以优化检索
* 生成更准确、更相关的答案
这样,您就有了一个"会思考"的 RAG 系统!
## 下一步
* **查看 [RAG 教程](/xparse/v1/tutorials/rag-tutorial)**:了解基础 RAG 的实现
* **查看 [Agent 教程](/xparse/v1/tutorials/agent-tutorial)**:了解如何使用 LangChain Agent
* **阅读 [xParse SDK 文档](/xparse/v1/quickstart)**:了解 xParse SDK 的详细使用方式
# 财务审计 Agent:自动化合规审核与异常检测
Source: https://docs.textin.com/xparse/v1/tutorials/audit-agent-tutorial
使用 xParse SDK + LangChain 构建智能财务审计 Agent,实现财务报表解析、合规性检查和异常检测的自动化流程
本教程面向财务审计、合规审核等场景,展示如何利用 xParse 作为数据底座,构建能够自动解析财务文档、提取关键信息、进行合规性检查和异常检测的智能 Agent。
## 场景介绍
### 业务痛点
在企业财务审计和合规审核场景中,审计人员面临以下挑战:
* **文档量大**:需要处理大量财务报表、合同、发票、银行对账单等文档
* **信息提取繁琐**:需要从非结构化文档中提取关键财务指标(金额、日期、合同条款等)
* **合规性检查复杂**:需要对照法规和内部政策,检查合同条款、财务数据是否符合规范
* **异常检测困难**:需要识别金额异常、日期冲突、数据不一致等问题
* **追溯困难**:发现问题后,需要追溯到原始文档的具体位置进行验证
### 解决方案
通过构建财务审计 Agent,我们可以实现:
* **自动化文档解析**:使用 [xParse SDK](/xparse/v1/sdk-python) 自动解析各类财务文档,构建向量知识库
* **智能信息提取**:使用 [xParse Extract API](/api-reference/endpoint/extract-v3) 从原始文档中结构化提取关键财务数据
* **合规性自动检查**:基于知识库和历史案例,自动检查合规性
* **异常自动检测**:识别金额异常、日期冲突等异常情况
* **结果可追溯**:Extract API 支持引用溯源,保留原始元素和坐标信息
## 架构设计
```
财务文档(PDF/Excel/图片)
↓
xParse SDK 解析(构建向量知识库)
├─ RecursiveCharacterTextSplitter
└─ DashScopeEmbeddings
↓
向量数据库(Milvus/Zilliz)
↓
xParse Extract API(结构化提取)
└─ 从原始文档提取金额、日期、
合同信息、发票信息等
↓
LangChain Agent
├─ Tool 1: extract_financial_data(Extract 结构化提取)
├─ Tool 2: check_compliance(合规性检查)
├─ Tool 3: detect_anomalies(异常检测)
└─ Tool 4: vector_search(检索历史案例)
↓
审计报告(含引用和追溯信息)
```
## 环境准备
```bash theme={null}
python -m venv .venv && source .venv/bin/activate
pip install xparse-client langchain langchain-core langchain-text-splitters \
langchain_milvus langchain-community \
pymilvus python-dotenv requests dashscope milvus_lite
export TEXTIN_APP_ID=your-app-id # 在 TextIn 官网注册获取
export TEXTIN_SECRET_CODE=your-secret-code # 在 TextIn 官网注册获取
export DASHSCOPE_API_KEY=your-dashscope-api-key # 本教程使用通义千问大模型,也可以替换成其他大模型
```
> 提示:`TEXTIN_APP_ID` 与 `TEXTIN_SECRET_CODE` 参考 [API Key](/xparse/api-key),请登录 [Textin 工作台](https://www.textin.com/console/dashboard/setting) 获取。示例中使用 `通义千问` 的大模型能力,其他模型用法类似。
## Step 1:使用 xParse SDK 解析文档
针对财务审计场景,我们使用 xParse SDK 解析文档,再通过 LangChain 进行分块和向量化:
* **分块策略**:按页面分组后使用 `RecursiveCharacterTextSplitter` 分块,保持页面完整性,便于追溯
* **向量化**:使用 `DashScopeEmbeddings` 进行向量化
```python theme={null}
from xparse_client import XParseClient
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_community.embeddings import DashScopeEmbeddings
from langchain_milvus import Milvus
from langchain_core.documents import Document
from collections import defaultdict
import os, glob
from dotenv import load_dotenv
load_dotenv()
client = XParseClient()
def run_audit_pipeline():
"""处理审计文档"""
text_splitter = RecursiveCharacterTextSplitter(chunk_size=2048, chunk_overlap=100)
all_chunks = []
patterns = ["*.pdf", "*.xlsx", "*.xls", "*.png", "*.jpg", "*.txt", "*.docx", "*.doc"]
for pattern in patterns:
for file_path in glob.glob(os.path.join("./audit_documents", pattern)):
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
page_texts = defaultdict(list)
for el in result.elements:
page_texts[el.page_number].append(el.text)
page_docs = [
Document(
page_content="\n\n".join(texts),
metadata={"filename": os.path.basename(file_path), "page_number": pn}
)
for pn, texts in sorted(page_texts.items())
]
chunks = text_splitter.split_documents(page_docs)
all_chunks.extend(chunks)
embedding = DashScopeEmbeddings(model="text-embedding-v3")
Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="audit_documents",
connection_args={"uri": "./audit_vectors.db"},
)
```
## Step 2:构建 LangChain Tools
### Extract 提取工具
使用 xParse Extract API 直接从原始文档中结构化提取财务数据,无需依赖正则匹配:
```python theme={null}
from langchain_core.tools import Tool
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
import base64
import requests
import re
import json
import os
import glob
import time
EXTRACT_API_URL = "https://api.textin.com/ai/service/v3/entity_extraction"
FINANCIAL_SCHEMA = {
"type": "object",
"properties": {
"金额列表": {
"type": "array",
"description": "文档中的所有金额信息",
"items": {
"type": "object",
"properties": {
"金额": {"type": ["string", "null"], "description": "金额数值"},
"说明": {"type": ["string", "null"], "description": "金额对应的描述或用途"}
},
"required": ["金额","说明"]
}
},
"日期列表": {
"type": "array",
"description": "文档中的所有日期信息",
"items": {
"type": "object",
"properties": {
"日期": {"type": ["string", "null"], "description": "日期"},
"说明": {"type": ["string", "null"], "description": "日期对应的描述"}
},
"required": ["日期","说明"]
}
},
"合同信息": {
"type": "object",
"description": "合同相关信息",
"properties": {
"甲方": {"type": ["string", "null"], "description": "甲方名称"},
"乙方": {"type": ["string", "null"], "description": "乙方名称"},
"合同编号": {"type": ["string", "null"], "description": "合同编号"},
"合同金额": {"type": ["string", "null"], "description": "合同总金额"}
}
},
"发票信息": {
"type": "object",
"description": "发票相关信息",
"properties": {
"发票号码": {"type": ["string", "null"], "description": "发票号码"},
"税号": {"type": ["string", "null"], "description": "纳税人识别号"},
"价税合计": {"type": ["string", "null"], "description": "价税合计金额"}
}
}
},
"required": ["金额列表", "日期列表", "合同信息", "发票信息"]
}
def extract_from_file(file_path: str, schema: dict, generate_citations: bool = False) -> dict:
with open(file_path, "rb") as f:
file_base64 = base64.b64encode(f.read()).decode("utf-8")
payload = {
"file": {"file_base64": file_base64, "file_name": os.path.basename(file_path)},
"schema": schema,
"extract_options": {"generate_citations": generate_citations}
}
headers = {
"x-ti-app-id": os.getenv("TEXTIN_APP_ID"),
"x-ti-secret-code": os.getenv("TEXTIN_SECRET_CODE"),
"Content-Type": "application/json"
}
response = requests.post(EXTRACT_API_URL, json=payload, headers=headers)
result = response.json()
if result.get("code") != 200:
raise Exception(f"Extract API 错误: {result.get('message', '未知错误')}")
return result["result"]
embedding = DashScopeEmbeddings(
model="text-embedding-v3",
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY"),
)
vector_store = Milvus(
embedding_function=embedding,
collection_name="audit_documents",
connection_args={"uri": "./audit_vectors.db"},
)
def extract_financial_data(query: str) -> str:
"""从财务文档中提取关键财务数据"""
docs_dir = "./audit_documents"
results = []
if "文件:" in query:
filename = query.split("文件:")[-1].strip()
file_path = os.path.join(docs_dir, filename)
if os.path.exists(file_path):
try:
result = extract_from_file(file_path, FINANCIAL_SCHEMA, generate_citations=True)
results.append({
"file": filename,
"data": result["extracted_schema"],
"citations": result.get("citations", {})
})
except Exception as e:
results.append({"file": filename, "error": str(e)})
else:
for pattern in ["*.pdf", "*.xlsx", "*.png", "*.jpg", "*.docx"]:
for file_path in glob.glob(os.path.join(docs_dir, pattern)):
try:
result = extract_from_file(file_path, FINANCIAL_SCHEMA, generate_citations=True)
results.append({
"file": os.path.basename(file_path),
"data": result["extracted_schema"]
})
time.sleep(0.5) # 每次请求间隔 500ms,避免触发 API 速率限制
except Exception as e:
results.append({"file": os.path.basename(file_path), "error": str(e)})
return json.dumps(results, ensure_ascii=False, indent=2)
```
### Tool 2: 合规性检查
```python theme={null}
def check_compliance(query: str) -> str:
"""
检查文档是否符合合规要求
检查项包括:
- 合同条款是否符合法规要求
- 财务数据是否符合会计准则
- 发票信息是否完整
- 审批流程是否合规
"""
docs = vector_store.similarity_search(query, k=3)
compliance_checks = []
for doc in docs:
text = doc.page_content
metadata = doc.metadata
checks = {
"file": metadata.get("filename", "unknown"),
"page": metadata.get("page_number", "unknown"),
"issues": []
}
amounts = re.findall(r'[\d,]+\.?\d*', text)
for amount_str in amounts:
try:
amount = float(amount_str.replace(',', ''))
if amount > 1000000:
checks["issues"].append(f"金额 {amount_str} 超过100万,需要特殊审批")
except:
pass
dates = re.findall(r'\d{4}[-年]\d{1,2}[-月]\d{1,2}[日]?', text)
for date_str in dates:
pass
required_terms = ["违约责任", "争议解决", "合同期限"]
missing_terms = [term for term in required_terms if term not in text]
if missing_terms:
checks["issues"].append(f"缺少关键条款: {', '.join(missing_terms)}")
if checks["issues"]:
compliance_checks.append(checks)
if not compliance_checks:
return "✅ 未发现合规性问题"
return json.dumps(compliance_checks, ensure_ascii=False, indent=2)
```
### Tool 3: 异常检测
```python theme={null}
def detect_anomalies(query: str) -> str:
"""
检测财务数据中的异常
检测项包括:
- 金额异常(过大、过小、负数等)
- 日期冲突(付款日期早于合同日期等)
- 数据不一致(同一合同在不同文档中金额不同)
"""
docs = vector_store.similarity_search(query, k=5)
anomalies = []
all_amounts = []
all_dates = []
for doc in docs:
text = doc.page_content
metadata = doc.metadata
amounts = re.findall(r'[\d,]+\.?\d*', text)
for amount_str in amounts:
try:
amount = float(amount_str.replace(',', ''))
all_amounts.append({
"value": amount,
"source": metadata.get("filename", "unknown"),
"page": metadata.get("page_number", "unknown")
})
except:
pass
dates = re.findall(r'\d{4}[-年]\d{1,2}[-月]\d{1,2}[日]?', text)
all_dates.extend([{
"value": date,
"source": metadata.get("filename", "unknown"),
"page": metadata.get("page_number", "unknown")
} for date in dates])
if all_amounts:
positive_amounts = [a for a in all_amounts if a["value"] > 0]
if len(positive_amounts) >= 2:
amounts_values = [a["value"] for a in positive_amounts]
max_amount = max(amounts_values)
min_amount = min(amounts_values)
if min_amount > 0:
ratio = max_amount / min_amount
if ratio > 1000:
anomalies.append({
"type": "金额差异异常",
"description": f"金额差异异常:最大金额 {max_amount:,.2f} 元与最小金额 {min_amount:,.2f} 元的比例达到 {ratio:.2f},超过1000倍",
"details": [a for a in positive_amounts if a["value"] in [max_amount, min_amount]]
})
negative_amounts = [a for a in all_amounts if a["value"] < 0]
if negative_amounts:
anomalies.append({
"type": "负数金额异常",
"description": "发现负数金额,可能是录入错误",
"details": negative_amounts
})
if not anomalies:
return "✅ 未发现异常"
return json.dumps(anomalies, ensure_ascii=False, indent=2)
```
### Tool 4: 检索历史案例
```python theme={null}
def search_historical_cases(query: str) -> str:
"""检索历史审计案例"""
docs = vector_store.similarity_search(query, k=5)
results = []
for i, doc in enumerate(docs, 1):
results.append({
f"案例 {i}": {
"文件": doc.metadata.get("filename", "unknown"),
"页码": doc.metadata.get("page_number", "unknown"),
"内容": doc.page_content[:300] + "...",
"相似度": "高" if i <= 2 else "中"
}
})
return json.dumps(results, ensure_ascii=False, indent=2)
```
### 组装所有Tools
```python theme={null}
tools = [
Tool(
name="extract_financial_data",
description="从财务文档中提取关键财务数据(金额、日期、合同条款、发票信息等)。输入可以是 '提取所有文档的财务数据' 或 '提取财务数据 文件:合同.pdf'。",
func=extract_financial_data
),
Tool(
name="check_compliance",
description="检查文档是否符合合规要求,包括合同条款合规性、财务数据合规性、发票信息完整性等。输入应为要检查的合规项描述。",
func=check_compliance
),
Tool(
name="detect_anomalies",
description="检测财务数据中的异常,包括金额异常、日期冲突、数据不一致等。输入应为要检测的异常类型描述。",
func=detect_anomalies
),
Tool(
name="search_historical_cases",
description="检索历史审计案例,用于参考和对比。输入应为要检索的案例类型或关键词。",
func=search_historical_cases
),
Tool(
name="vector_search",
description="基于语义检索相关文档片段。输入应为自然语言查询。",
func=lambda q: "\n\n".join([
f"[{i+1}] {doc.metadata.get('filename', 'unknown')}\n{doc.page_content[:300]}..."
for i, doc in enumerate(vector_store.similarity_search(q, k=3))
])
)
]
```
## Step 3:配置 LangChain Agent
```python theme={null}
from langchain_classic.agents import AgentType, initialize_agent
from langchain_community.chat_models import ChatTongyi
import os
llm = ChatTongyi(
model="qwen-max",
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY"),
temperature=0,
)
agent = initialize_agent(
tools=tools,
llm=llm,
agent=AgentType.ZERO_SHOT_REACT_DESCRIPTION,
verbose=True,
)
```
## Step 4:完整示例代码
```python expandable theme={null}
#!/usr/bin/env python
# -*- coding: utf-8 -*-
"""
财务审计Agent完整示例
"""
import os
import re
import json
import glob
import base64
import time
from collections import defaultdict
from dotenv import load_dotenv
import requests
from xparse_client import XParseClient
from langchain_core.tools import Tool
from langchain_core.documents import Document
from langchain_classic.agents import AgentType, initialize_agent
from langchain_community.chat_models import ChatTongyi
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
from langchain_text_splitters import RecursiveCharacterTextSplitter
load_dotenv()
EXTRACT_API_URL = "https://api.textin.com/ai/service/v3/entity_extraction"
FINANCIAL_SCHEMA = {
"type": "object",
"properties": {
"金额列表": {
"type": "array",
"description": "文档中的所有金额信息",
"items": {
"type": "object",
"properties": {
"金额": {"type": ["string", "null"], "description": "金额数值"},
"说明": {"type": ["string", "null"], "description": "金额对应的描述或用途"}
},
"required": ["金额", "说明"]
}
},
"日期列表": {
"type": "array",
"description": "文档中的所有日期信息",
"items": {
"type": "object",
"properties": {
"日期": {"type": ["string", "null"], "description": "日期"},
"说明": {"type": ["string", "null"], "description": "日期对应的描述"}
},
"required": ["日期", "说明"]
}
},
"合同信息": {
"type": "object",
"description": "合同相关信息",
"properties": {
"甲方": {"type": ["string", "null"], "description": "甲方名称"},
"乙方": {"type": ["string", "null"], "description": "乙方名称"},
"合同编号": {"type": ["string", "null"], "description": "合同编号"},
"合同金额": {"type": ["string", "null"], "description": "合同总金额"}
}
},
"发票信息": {
"type": "object",
"description": "发票相关信息",
"properties": {
"发票号码": {"type": ["string", "null"], "description": "发票号码"},
"税号": {"type": ["string", "null"], "description": "纳税人识别号"},
"价税合计": {"type": ["string", "null"], "description": "价税合计金额"}
}
}
},
"required": ["金额列表", "日期列表", "合同信息", "发票信息"]
}
class AuditAgent:
"""财务审计Agent"""
def __init__(self):
self.client = XParseClient()
self.setup_vector_store()
self.setup_agent()
def setup_vector_store(self):
"""配置向量数据库"""
self.embedding = DashScopeEmbeddings(
model="text-embedding-v3",
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY"),
)
self.vector_store = Milvus(
embedding_function=self.embedding,
collection_name="audit_documents",
connection_args={"uri": "./audit_vectors.db"},
)
def extract_from_file(self, file_path: str, schema: dict, generate_citations: bool = False) -> dict:
with open(file_path, "rb") as f:
file_base64 = base64.b64encode(f.read()).decode("utf-8")
payload = {
"file": {"file_base64": file_base64, "file_name": os.path.basename(file_path)},
"schema": schema,
"extract_options": {"generate_citations": generate_citations}
}
headers = {
"x-ti-app-id": os.getenv("TEXTIN_APP_ID"),
"x-ti-secret-code": os.getenv("TEXTIN_SECRET_CODE"),
"Content-Type": "application/json"
}
response = requests.post(EXTRACT_API_URL, json=payload, headers=headers)
result = response.json()
if result.get("code") != 200:
raise Exception(f"Extract API 错误: {result.get('message', '未知错误')}")
return result["result"]
def setup_agent(self):
"""配置Agent和Tools"""
tools = [
Tool(
name="extract_financial_data",
description="从财务文档中提取关键财务数据(金额、日期、合同条款、发票信息等)。输入可以是 '提取所有文档的财务数据' 或 '提取财务数据 文件:合同.pdf'。",
func=self.extract_financial_data
),
Tool(
name="check_compliance",
description="检查合规性:合同条款、财务数据合规性等",
func=self.check_compliance
),
Tool(
name="detect_anomalies",
description="检测异常:金额异常、日期冲突等",
func=self.detect_anomalies
),
Tool(
name="vector_search",
description="语义检索相关文档",
func=lambda q: "\n\n".join([
f"[{i+1}] {doc.metadata.get('filename', 'unknown')}\n{doc.page_content[:300]}..."
for i, doc in enumerate(self.vector_store.similarity_search(q, k=3))
])
)
]
llm = ChatTongyi(
model="qwen-max",
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY"),
temperature=0,
)
self.agent = initialize_agent(
tools=tools,
llm=llm,
agent=AgentType.ZERO_SHOT_REACT_DESCRIPTION,
verbose=True,
)
def extract_financial_data(self, query: str) -> str:
"""从财务文档中提取关键财务数据"""
docs_dir = "./audit_documents"
results = []
if "文件:" in query:
filename = query.split("文件:")[-1].strip()
file_path = os.path.join(docs_dir, filename)
if os.path.exists(file_path):
try:
result = self.extract_from_file(file_path, FINANCIAL_SCHEMA, generate_citations=True)
results.append({
"file": filename,
"data": result["extracted_schema"],
"citations": result.get("citations", {})
})
except Exception as e:
results.append({"file": filename, "error": str(e)})
else:
for pattern in ["*.pdf", "*.xlsx", "*.png", "*.jpg", "*.docx"]:
for file_path in glob.glob(os.path.join(docs_dir, pattern)):
try:
result = self.extract_from_file(file_path, FINANCIAL_SCHEMA, generate_citations=True)
results.append({
"file": os.path.basename(file_path),
"data": result["extracted_schema"]
})
time.sleep(0.5) # 每次请求间隔 500ms,避免触发 API 速率限制
except Exception as e:
results.append({"file": os.path.basename(file_path), "error": str(e)})
return json.dumps(results, ensure_ascii=False, indent=2)
def check_compliance(self, query: str) -> str:
"""合规性检查"""
docs = self.vector_store.similarity_search(query, k=3)
issues = []
for doc in docs:
text = doc.page_content
amounts = re.findall(r'[\d,]+\.?\d*', text)
for amount_str in amounts:
try:
amount = float(amount_str.replace(',', ''))
if amount > 1000000:
issues.append({
"file": doc.metadata.get("filename", "unknown"),
"page": doc.metadata.get("page_number", "unknown"),
"issue": f"金额 {amount_str} 超过100万,需要特殊审批"
})
except:
pass
return json.dumps(issues, ensure_ascii=False, indent=2) if issues else "✅ 未发现合规性问题"
def detect_anomalies(self, query: str) -> str:
"""异常检测"""
docs = self.vector_store.similarity_search(query, k=5)
anomalies = []
all_amounts = []
for doc in docs:
amounts = re.findall(r'[\d,]+\.?\d*', doc.page_content)
for amount_str in amounts:
try:
amount = float(amount_str.replace(',', ''))
if amount > 0:
all_amounts.append(amount)
except:
pass
if len(all_amounts) >= 2:
min_amount = min(all_amounts)
max_amount = max(all_amounts)
if min_amount > 0:
ratio = max_amount / min_amount
if ratio > 1000:
anomalies.append(f"金额差异异常:最大金额 {max_amount:,.2f} 元与最小金额 {min_amount:,.2f} 元的比例达到 {ratio:.2f},超过1000倍")
elif max_amount > 0:
anomalies.append(f"发现零金额异常:存在金额为0的记录,同时存在金额为 {max_amount:,.2f} 元的记录")
return json.dumps(anomalies, ensure_ascii=False, indent=2) if anomalies else "✅ 未发现异常"
def process_documents(self):
"""处理文档"""
print("=" * 60)
print("开始处理审计文档...")
print("=" * 60)
text_splitter = RecursiveCharacterTextSplitter(chunk_size=2048, chunk_overlap=100)
all_chunks = []
patterns = ["*.pdf", "*.xlsx", "*.xls", "*.png", "*.jpg", "*.txt", "*.docx", "*.doc"]
for pattern in patterns:
for file_path in glob.glob(os.path.join("./audit_documents", pattern)):
with open(file_path, "rb") as f:
result = self.client.parse.run(file=f, filename=os.path.basename(file_path))
page_texts = defaultdict(list)
for el in result.elements:
page_texts[el.page_number].append(el.text)
page_docs = [
Document(
page_content="\n\n".join(texts),
metadata={"filename": os.path.basename(file_path), "page_number": pn}
)
for pn, texts in sorted(page_texts.items())
]
chunks = text_splitter.split_documents(page_docs)
all_chunks.extend(chunks)
Milvus.from_documents(
documents=all_chunks,
embedding=self.embedding,
collection_name="audit_documents",
connection_args={"uri": "./audit_vectors.db"},
)
print("\n文档处理完成!")
def query(self, question: str) -> str:
"""查询Agent"""
response = self.agent.invoke({
"input": question
})
return response["output"]
def main():
"""主函数"""
agent = AuditAgent()
# 1. 处理文档(首次运行)
agent.process_documents()
# 2. 查询示例
questions = [
"提取所有合同中的金额和签署日期",
"检查这些合同是否符合合规要求",
"检测是否有金额异常的情况",
"检索类似的历史审计案例"
]
for question in questions:
print(f"\n{'='*60}")
print(f"问题: {question}")
print(f"{'='*60}")
answer = agent.query(question)
print(f"\n回答:\n{answer}")
if __name__ == "__main__":
main()
```
## 使用示例
### 示例1:提取财务数据
```python theme={null}
agent = AuditAgent()
response = agent.query("从财务报表中提取所有超过10万的金额和对应的日期")
print(response)
```
### 示例2:提取指定文件的财务数据
```python theme={null}
response = agent.query("提取财务数据 文件:合同_2024Q1.pdf")
print(response)
```
### 示例3:合规性检查
```python theme={null}
response = agent.query("检查所有合同是否符合以下要求:1) 金额超过100万需要特殊审批 2) 必须包含违约责任条款")
print(response)
```
### 示例4:异常检测
```python theme={null}
response = agent.query("检测财务报表中是否有异常:金额为负数、日期不合理、同一合同金额不一致等")
print(response)
```
## 最佳实践
1. **文档预处理**:确保文档格式统一,命名规范(如:`合同_2024Q1_供应商A.pdf`)
2. **分块策略**:按页面分组后使用 `RecursiveCharacterTextSplitter` 分块,保持页面完整性,便于追溯
3. **向量化配置**:使用 `DashScopeEmbeddings` 的 `text-embedding-v3` 模型获得更好的语义理解
4. **结构化提取**:使用 Extract API 定义精确的 Schema,提取结构化财务数据,避免正则匹配的局限性
5. **引用溯源**:开启 `generate_citations` 获取提取结果的原文引用,便于审计追溯
6. **合规规则配置**:将合规规则存储在配置文件中,便于更新和维护
7. **异常阈值设置**:根据业务需求设置合理的异常检测阈值
8. **结果追溯**:在 Agent 回答中包含文档名称和页码,便于人工验证
## 常见问题
**Q: 如何处理加密的PDF文档?**\
A: 在调用 `client.parse.run()` 时添加 `pdf_pwd` 参数,或在处理前先解密文档。
**Q: 如何提高提取准确率?**\
A: 1) 使用 Extract API 进行结构化提取,定义精确的 Schema;2) 使用 `text-embedding-v3` 模型进行向量检索;3) 开启 `generate_citations` 验证提取结果。
**Q: Extract API 支持哪些文件格式?**\
A: 支持 PDF、Word(docx)、Excel(xlsx)、图片(PNG/JPG)等常见格式,文件通过 base64 编码上传。
**Q: 如何集成到现有审计系统?**\
A: 可以将 Agent 封装为 REST API,通过HTTP接口调用,或集成到现有的审计工作流中。
## 相关文档
* [快速启动](/xparse/v1/quickstart) - 了解 xParse SDK 基本使用方法
* [文档元素和元数据](/xparse/v1/parse-response) - 了解数据结构
* [结果回溯与可视化](/xparse/v1/parse-response) - 了解如何追溯结果
* [Agent教程](/xparse/v1/tutorials/agent-tutorial) - 了解通用Agent构建方法
# 利用 xParse 优化 Dify 知识库的文档解析效果
Source: https://docs.textin.com/xparse/v1/tutorials/dify-rag-tutorial
使用 Dify + xParse 通过知识流水线构建知识库,并创建 RAG 应用实现智能问答。
本教程将带您了解如何使用 Dify + xParse 通过知识流水线构建知识库,并创建 Chatflow 应用实现基于知识库的智能问答。
## 什么是 Dify + xParse RAG?
**RAG(Retrieval-Augmented Generation,检索增强生成)** 是一种结合信息检索和生成式 AI 的技术。通过 RAG,大模型可以基于企业知识库进行回答,而不是仅依赖训练数据,从而提供更准确、更相关的答案。
**Dify + xParse** 结合了 Dify 强大的工作流能力和 xParse 专业的文档解析能力,让您能够:
* **构建高质量知识库**:使用 xParse 的智能解析引擎,准确提取文档内容,保留语义结构
* **智能分块处理**:通过父子文本分块策略,保持文档章节完整性,提升检索效果
* **快速搭建 RAG 应用**:通过 Dify 的 Chatflow 功能,快速构建基于知识库的智能问答系统
## 前置准备
在开始之前,您需要完成以下准备工作。
### 第一步:获取 API Key
在使用 xParse Dify 插件之前,您需要获取 xParse 的 API Key。
1. 前往 [TextIn 工作台 - 账号与开发者信息](https://www.textin.com/console/dashboard/setting)
2. 获取您的 `x-ti-app-id` 和 `x-ti-secret-code`
> 提示:详细获取方式请参考 [API Key 文档](/xparse/api-key)
### 第二步:搜索和安装 xParse Dify 插件
1. 登录 Dify 平台,进入插件市场
2. 在搜索框中输入 "xParse"
3. 找到 xParse 插件(由 intsig-textin 提供)
4. 点击"安装"按钮
![搜索 xParse 插件]()
![安装 xParse 插件]() ### 第三步:配置插件 API 信息
安装完成后,需要配置插件的 API 信息。
1. 进入插件管理页面
2. 找到已安装的 xParse 插件
3. 点击"配置"或"设置"
4. 填写以下信息:
* **x-ti-app-id**:xParse 的应用 ID,必填
* **x-ti-secret-code**:xParse 的密钥,必填
![插件配置示例]() > 提示:请确保 API Key 信息填写正确,否则插件将无法正常工作。
## 创建知识库(通过知识流水线)
接下来,我们将通过 Dify 的知识流水线功能创建知识库。知识流水线提供了更灵活的配置选项,可以精确控制文档处理的每个环节。
### 第一步:创建知识流水线
1. 在 Dify 平台中,进入"知识库"页面
2. 选择"通过知识流水线创建"选项
3. 选择"空白知识流水线"模板
![创建知识流水线]() ### 第二步:配置数据源节点
1. 在知识流水线编辑器中,添加第一个节点
2. 选择节点类型为"数据源"或"File"
3. 配置数据源节点:
* 节点名称:可命名为"文件输入"或"数据源"
* 文件类型:支持文档和图片格式
![配置数据源节点]() ### 第三步:配置 xParse 文档解析节点
1. 添加第二个节点,选择"工具"节点,选择 xParse -> 文档解析
* **文件输入**:选择数据源节点的 `file` 输出
2. 配置解析参数:
* **解析引擎**:可选择 `Textin`(推荐)、`Textin Lite`、`GUI` 等
* **预处理**:可选择 `切边矫正`、`去水印` 等(根据文档类型选择)
![配置 xParse 解析节点]() xParse 插件支持以下配置选项:
* **文件输入**:选择要解析的文件(必填)
* **解析引擎**:可选择 `Textin`(推荐)、`Textin Lite`、`GUI` 等(陆续接入中)
* **预处理**:可选择 `切边矫正`、`去水印` 等
> 提示:其他参数详情可参考 [插件说明文档](https://marketplace.dify.ai/plugins/intsig-textin/xparse)
### 第四步:配置父子文本分块节点
1. 添加第三个节点,选择 Dify 官方的"父子文本分块"节点
2. 配置输入变量:
* **文本输入**:选择 xParse 文档解析节点输出的 `text`
* 其他分块参数可根据需要调整
![配置分块节点]() 父子文本分块策略能够保持文档的章节结构,确保相关内容的完整性,这对于提升检索效果非常重要。
### 第五步:配置知识库节点
1. 添加第四个节点,选择"知识库"节点
2. 配置知识库参数:
* **知识库名称**:如"xparse知识库"
* **分段结构**:选择"父子分块"
* **分块配置**:选择上一步父子文本分块节点的 `result` 输出
* **Embedding 模型**:根据需要选择,如 OpenAI 的 `text-embedding-3-large`
* **检索设置**:选择"混合检索" -> "权重设置"(根据需要调整权重参数或选择Rerank模型)
![配置知识库节点]() > 提示:混合检索结合了向量检索的语义理解能力和关键词检索的精确匹配能力,能够提供更好的检索效果。
### 第六步:测试运行和发布
1. 配置完成后,点击"测试运行"或"运行"按钮
2. 检查各节点的输出是否正确:
* 数据源节点:确认文件输入正常
* xParse 解析节点:确认文档解析成功,输出 `text` 字段
* 分块节点:确认文本分块正常,输出 `result` 字段
* 知识库节点:确认知识库创建成功
3. 如果测试通过,点击"发布"或"发布更新"按钮
![测试运行]() ### 第七步:上传文档到知识库
知识流水线发布后,您可以开始上传文档。
1. 前往"知识库"页面
2. 找到刚创建的"xparse知识库"
3. 点击"上传文件"或"添加文件"
4. 选择要上传的文档文件
![上传文档]() 支持的文件格式包括:
* PDF 文档
* Word 文档(.docx)
* Excel 表格(.xlsx)
* PowerPoint 演示文稿(.pptx)
* 图片文件(JPG、PNG 等)
上传后,文档将自动通过知识流水线进行处理:解析 → 分块 → 向量化 → 存入知识库。
![文档处理中]() ## 创建 Chatflow 演示应用
知识库创建完成后,我们将创建一个 Chatflow 应用来演示知识库的问答效果。
### 第一步:创建 Chatflow 应用
1. 在 Dify 平台中,进入"工作室"或"应用"页面,选择 "Chatflow"
2. 点击"创建空白应用"
3. 填写应用信息:
* **应用名称**:如"xparse rag demo"
* **应用描述**:如"基于 xparse知识库的 RAG 问答演示"
![创建 Chatflow 应用]() ### 第二步:配置知识库检索节点
1. 在 Chatflow 编辑器中,添加"知识检索"节点
2. 配置检索参数:
* **知识库选择**:选择已经创建好的知识库(如"xparse知识库")
* 其他参数根据需要配置
![配置知识库检索节点]() ### 第三步:配置 LLM 节点
1. 添加"LLM"节点
2. 配置模型:
* 选择可用的 LLM 模型(如 GPT-4、Claude 等)
* 如果没有模型可用,需要先在插件市场安装对应的模型插件
3. 配置上下文:
* **上下文**:选择知识库检索节点的输出(通常是 `result` 或 `context`)
4. 配置系统提示词:
* 在"SYSTEM"区域填写提示词,例如:
```
你是一个智能助手,能够基于提供的知识库内容回答用户的问题。
请仔细阅读知识库中的相关内容,并基于这些内容给出准确、详细的回答。
如果知识库中没有相关信息,请如实告知用户。
```
5. 配置用户提示词
* 在"USER"区域增加上下文变量,例如:`知识检索 {result}`
![配置 LLM 节点]() ### 第四步:连接节点
将各个节点按照以下顺序连接:
1. **开始节点** → **知识库检索节点**
* 开始节点的用户输入传递给知识库检索节点
2. **知识库检索节点** → **LLM 节点**
* 检索到的知识库内容作为上下文传递给 LLM
3. **LLM 节点** → **回复节点**
* LLM 生成的回答返回给用户
![连接节点]() 数据流程:
```
用户问题
↓
知识库检索(从 xparse知识库 中检索相关内容)
↓
LLM 生成(基于检索到的内容生成回答)
↓
返回答案给用户
```
### 第五步:预览和测试
1. 点击"预览"按钮,进入预览模式
2. 在预览界面中输入问题,测试问答效果
3. 观察以下内容:
* 知识库检索是否正常工作
* 检索到的内容是否相关
* LLM 生成的回答是否准确
![预览 Chatflow]() ### 第六步:发布应用
测试通过后,可以发布应用供实际使用。
1. 点击"发布"或"保存并发布"按钮
2. 发布成功后,可以通过 API 或 Web 界面访问应用
![发布应用]() ## 总结
通过本教程,您已经学会了:
1. **前置准备**:获取 API Key、安装和配置 xParse Dify 插件
2. **创建知识库**:通过知识流水线创建知识库,配置数据源、xParse 解析、文本分块和知识库节点
3. **创建 RAG 应用**:通过 Chatflow 创建基于知识库的智能问答应用
**核心优势**:
* **xParse 智能解析**:准确提取文档内容,保留语义结构
* **父子文本分块**:保持文档章节完整性,提升检索效果
* **混合检索**:结合向量检索和关键词检索,提供更好的检索效果
* **快速搭建**:通过 Dify 的可视化界面,快速构建 RAG 应用
现在,您可以开始构建自己的知识库和 RAG 应用了!
## 常见问题
### Q: 如何选择合适的解析引擎?
A:
* **Textin**:适合大多数场景,速度和准确性俱佳(推荐)
* **Textin Lite**:适合纯文本、表格图片、电子档 PDF 等场景,速度更快,价格更低
* **GUI**:适合桌面/移动应用和网页界面截图识别,能识别按钮、输入框等 UI 元素
### Q: 为什么选择父子文本分块?
A: 父子文本分块能够保持文档的章节结构,确保相关内容的完整性。这对于 RAG 应用非常重要,因为检索到的内容如果是完整的章节,能够提供更准确的上下文信息。
### Q: 混合检索和向量检索有什么区别?
A:
* **向量检索**:基于语义相似度进行检索,能够理解问题的语义含义
* **混合检索**:结合向量检索和关键词检索,既能理解语义,又能精确匹配关键词,通常效果更好
### Q: 如何优化检索效果?
A:
* 确保文档解析质量:选择合适的解析引擎和预处理选项
* 优化分块策略:根据文档类型选择合适的分块策略
* 调整 Top K 值:根据实际效果调整返回的文档片段数量
* 优化系统提示词:让 LLM 更好地利用检索到的内容
## 相关资源
* [xParse 产品文档](/xparse/overview)
* [API 参考文档](/api-reference/endpoint/xparse/v1/parse-sync)
* [快速启动指南](/xparse/v1/quickstart)
* [Dify 官网](https://dify.ai/zh)
* [xParse Dify 插件](https://marketplace.dify.ai/plugins/intsig-textin/xparse)
* [TextIn xParse 产品介绍](https://www.textin.com/market/detail/xparse)
# 单据录入 Agent:发票合同订单自动化处理
Source: https://docs.textin.com/xparse/v1/tutorials/document-extraction-agent-tutorial
使用 xParse Extract API + LangChain 构建单据提取 Agent,实现发票、合同、订单等单据的自动化信息提取和数据验证
本教程面向单据处理场景,展示如何利用 [xParse Extract API](/api-reference/endpoint/extract-v3) 直接从单据文档中抽取结构化信息,并通过 Agent 进行数据验证。
## 场景介绍
### 业务痛点
在财务和采购场景中,企业面临以下挑战:
* **单据量大**:需要处理大量发票、合同、订单、收据等单据
* **信息提取繁琐**:需要从单据中提取关键信息(金额、税号、日期、商品明细等)
* **数据验证困难**:需要验证数据的完整性和准确性(金额计算、日期合理性等)
* **格式多样**:单据格式不统一,有PDF、图片、扫描件等
* **人工成本高**:手动录入和核对效率低,容易出错
### 解决方案
通过构建单据提取Agent,我们可以实现:
* **一步完成解析与抽取**:使用 [xParse Extract API](/api-reference/endpoint/extract-v3),通过定义 Schema 直接从文档中提取结构化数据,无需先解析再用大模型抽取
* **Schema 驱动**:为发票、合同、订单分别定义抽取 Schema,精确控制提取字段
* **数据验证**:自动验证提取的数据(金额校验、日期检查、必填项检查等)
* **批量处理**:支持批量处理大量单据
## 架构设计
```
单据文档(PDF/图片/扫描件)
↓
[xParse Extract API]
└─ 解析 + 结构化抽取(一步完成)
↓
[LangChain Agent]
├─ Tool 1: extract_invoice_info(发票抽取 Schema)
├─ Tool 2: extract_contract_info(合同抽取 Schema)
├─ Tool 3: extract_order_info(订单抽取 Schema)
└─ Tool 4: validate_data(数据验证)
↓
结构化数据(JSON)+ 验证报告
```
**核心思路**:xParse Extract API 通过 Schema 定义一步完成文档解析与结构化抽取,Agent 负责根据用户意图选择合适的抽取工具和执行验证。
## 环境准备
首先安装必要的依赖:
```bash theme={null}
python -m venv .venv && source .venv/bin/activate
pip install requests langchain langchain-community langchain-core python-dotenv dashscope
```
创建 `.env` 文件存储配置:
```bash theme={null}
# .env
TEXTIN_APP_ID=your-app-id
TEXTIN_SECRET_CODE=your-secret-code
DASHSCOPE_API_KEY=your-dashscope-key
```
> 提示:`TEXTIN_APP_ID` 与 `TEXTIN_SECRET_CODE` 参考 [API Key](/xparse/api-key),请登录 [Textin 工作台](https://www.textin.com/console/dashboard/setting) 获取。示例中使用 `通义千问` 的大模型能力,其他模型用法类似。
## 完整代码示例
下面是一个完整的、可以直接运行的示例:
```python expandable theme={null}
import os
import json
import base64
import glob
import re
from datetime import datetime
from dotenv import load_dotenv
import requests
from langchain_core.tools import Tool
from langchain_classic.agents import AgentType, initialize_agent
from langchain_community.chat_models import ChatTongyi
load_dotenv()
# ========== Step 1: Extract API 配置 ==========
DOCS_DIR = "/your/doc/folder"
EXTRACT_API_URL = "https://api.textin.com/ai/service/v3/entity_extraction"
def extract_from_file(file_path: str, schema: dict, generate_citations: bool = False, stamp: bool = False) -> dict:
with open(file_path, "rb") as f:
file_base64 = base64.b64encode(f.read()).decode("utf-8")
payload = {
"file": {"file_base64": file_base64, "file_name": os.path.basename(file_path)},
"schema": schema,
"extract_options": {"generate_citations": generate_citations, "stamp": stamp}
}
headers = {
"x-ti-app-id": os.getenv("TEXTIN_APP_ID"),
"x-ti-secret-code": os.getenv("TEXTIN_SECRET_CODE"),
"Content-Type": "application/json"
}
response = requests.post(EXTRACT_API_URL, json=payload, headers=headers)
result = response.json()
if result.get("code") != 200:
raise Exception(f"Extract API 错误: {result.get('message', '未知错误')}")
return result["result"]
# ========== Step 2: 定义抽取 Schema ==========
INVOICE_SCHEMA = {
"type": "object",
"properties": {
"发票号码": {"type": ["string", "null"], "description": "发票号码"},
"发票代码": {"type": ["string", "null"], "description": "发票代码"},
"开票日期": {"type": ["string", "null"], "description": "开票日期"},
"销售方名称": {"type": ["string", "null"], "description": "销售方名称"},
"销售方税号": {"type": ["string", "null"], "description": "销售方纳税人识别号"},
"购买方名称": {"type": ["string", "null"], "description": "购买方名称"},
"购买方税号": {"type": ["string", "null"], "description": "购买方纳税人识别号"},
"商品明细": {
"type": "array", "description": "商品明细列表",
"items": {
"type": "object",
"properties": {
"名称": {"type": ["string", "null"], "description": "商品名称"},
"规格型号": {"type": ["string", "null"], "description": "规格型号"},
"数量": {"type": ["string", "null"], "description": "数量"},
"单价": {"type": ["string", "null"], "description": "单价"},
"金额": {"type": ["string", "null"], "description": "金额"},
"税率": {"type": ["string", "null"], "description": "税率"}
},
"required": ["名称", "金额","规格型号","数量","单价","税率"]
}
},
"合计金额": {"type": ["string", "null"], "description": "合计金额"},
"税额": {"type": ["string", "null"], "description": "税额"},
"价税合计": {"type": ["string", "null"], "description": "价税合计"}
},
"required": ["发票号码", "合计金额","开票日期", "商品明细", "价税合计","发票代码","销售方名称","销售方税号","购买方名称","购买方税号","税额"]
}
CONTRACT_SCHEMA = {
"type": "object",
"properties": {
"合同编号": {"type": ["string", "null"], "description": "合同编号"},
"签署日期": {"type": ["string", "null"], "description": "签署日期"},
"生效日期": {"type": ["string", "null"], "description": "生效日期"},
"到期日期": {"type": ["string", "null"], "description": "到期日期"},
"甲方名称": {"type": ["string", "null"], "description": "甲方名称"},
"乙方名称": {"type": ["string", "null"], "description": "乙方名称"},
"甲方联系方式": {"type": ["string", "null"], "description": "甲方联系方式"},
"乙方联系方式": {"type": ["string", "null"], "description": "乙方联系方式"},
"合同总价": {"type": ["string", "null"], "description": "合同总价"},
"付款方式": {"type": ["string", "null"], "description": "付款方式"},
"付款期限": {"type": ["string", "null"], "description": "付款期限"},
"违约责任": {"type": ["string", "null"], "description": "违约责任条款"},
"争议解决": {"type": ["string", "null"], "description": "争议解决方式"},
"合同期限": {"type": ["string", "null"], "description": "合同期限"}
},
"required": ["合同编号","违约责任", "合同期限","争议解决","付款期限","付款方式","签署日期", "甲方名称", "乙方名称", "合同总价","生效日期","到期日期","甲方联系方式","乙方联系方式"]
}
ORDER_SCHEMA = {
"type": "object",
"properties": {
"订单号": {"type": ["string", "null"], "description": "订单号"},
"下单日期": {"type": ["string", "null"], "description": "下单日期"},
"交货日期": {"type": ["string", "null"], "description": "交货日期"},
"客户名称": {"type": ["string", "null"], "description": "客户名称"},
"联系方式": {"type": ["string", "null"], "description": "联系方式"},
"地址": {"type": ["string", "null"], "description": "地址"},
"商品明细": {
"type": "array", "description": "商品明细列表",
"items": {
"type": "object",
"properties": {
"名称": {"type": ["string", "null"], "description": "商品名称"},
"规格": {"type": ["string", "null"], "description": "规格"},
"数量": {"type": ["string", "null"], "description": "数量"},
"单价": {"type": ["string", "null"], "description": "单价"},
"金额": {"type": ["string", "null"], "description": "金额"}
},
"required": ["名称", "金额","规格","数量","单价"]
}
},
"订单总额": {"type": ["string", "null"], "description": "订单总额"},
"运费": {"type": ["string", "null"], "description": "运费"},
"优惠金额": {"type": ["string", "null"], "description": "优惠金额"},
"实付金额": {"type": ["string", "null"], "description": "实付金额"}
},
"required": ["订单号", "优惠金额","订单总额","运费","下单日期", "商品明细", "实付金额","交货日期","客户名称","联系方式","地址"]
}
VALIDATION_SCHEMA = {
"type": "object",
"properties": {
"发票号码": {"type": ["string", "null"], "description": "发票号码"},
"发票代码": {"type": ["string", "null"], "description": "发票代码"},
"开票日期": {"type": ["string", "null"], "description": "开票日期"},
"销售方税号": {"type": ["string", "null"], "description": "销售方纳税人识别号"},
"购买方税号": {"type": ["string", "null"], "description": "购买方纳税人识别号"},
"合计金额": {"type": ["string", "null"], "description": "合计金额"},
"税额": {"type": ["string", "null"], "description": "税额"},
"价税合计": {"type": ["string", "null"], "description": "价税合计"},
"合同编号": {"type": ["string", "null"], "description": "合同编号"},
"签署日期": {"type": ["string", "null"], "description": "签署日期"},
"合同总价": {"type": ["string", "null"], "description": "合同总价"},
"订单号": {"type": ["string", "null"], "description": "订单号"},
"下单日期": {"type": ["string", "null"], "description": "下单日期"},
"实付金额": {"type": ["string", "null"], "description": "实付金额"},
"商品明细": {
"type": "array", "description": "商品明细列表",
"items": {
"type": "object",
"properties": {
"名称": {"type": ["string", "null"], "description": "商品名称"},
"金额": {"type": ["string", "null"], "description": "金额"}
},
"required": ["名称","金额"]
}
}
},
"required": ["发票号码","实付金额","商品明细","下单日期","订单号","合同总价","签署日期","发票代码","开票日期","销售方税号","购买方税号","合计金额","税额","价税合计","合同编号"]
}
# ========== Step 3: 初始化大模型 ==========
llm = ChatTongyi(
model="qwen-max",
top_p=0.8,
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY")
)
# ========== Step 4: 构建 LangChain Tools ==========
def extract_invoice_info(query: str) -> str:
"""从发票中提取结构化信息"""
filename = query.split("文件:")[-1].strip() if "文件:" in query else None
if not filename:
return "❌ 请提供文件名,格式:提取发票信息 文件:发票.pdf"
file_path = os.path.join(DOCS_DIR, filename)
if not os.path.exists(file_path):
return f"❌ 文件不存在: {file_path}"
try:
result = extract_from_file(file_path, INVOICE_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
except Exception as e:
return f"❌ 提取信息时出错:{str(e)}"
def extract_contract_info(query: str) -> str:
"""从合同中提取关键信息"""
filename = query.split("文件:")[-1].strip() if "文件:" in query else None
if not filename:
return "❌ 请提供文件名,格式:提取合同信息 文件:合同.pdf"
file_path = os.path.join(DOCS_DIR, filename)
if not os.path.exists(file_path):
return f"❌ 文件不存在: {file_path}"
try:
result = extract_from_file(file_path, CONTRACT_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
except Exception as e:
return f"❌ 提取信息时出错:{str(e)}"
def extract_order_info(query: str) -> str:
"""从订单中提取信息"""
filename = query.split("文件:")[-1].strip() if "文件:" in query else None
if not filename:
return "❌ 请提供文件名,格式:提取订单信息 文件:订单.pdf"
file_path = os.path.join(DOCS_DIR, filename)
if not os.path.exists(file_path):
return f"❌ 文件不存在: {file_path}"
try:
result = extract_from_file(file_path, ORDER_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
except Exception as e:
return f"❌ 提取信息时出错:{str(e)}"
def validate_data(query: str) -> str:
"""验证提取的数据"""
filename = query.split("文件:")[-1].strip() if "文件:" in query else None
if not filename:
return "❌ 请提供文件名,格式:验证数据 文件:发票.pdf"
file_path = os.path.join(DOCS_DIR, filename)
if not os.path.exists(file_path):
return f"❌ 文件不存在: {file_path}"
try:
result = extract_from_file(file_path, VALIDATION_SCHEMA, generate_citations=True)
data = result["extracted_schema"]
citations = result.get("citations", {})
checks = []
if "发票" in filename:
required_fields = ["发票号码", "开票日期", "价税合计"]
elif "合同" in filename or "contract" in filename:
required_fields = ["合同编号", "签署日期", "合同总价"]
elif "订单" in filename or "order" in filename:
required_fields = ["订单号", "下单日期", "实付金额"]
else:
required_fields = []
missing = [f for f in required_fields if not data.get(f)]
checks.append({
"type": "必填项检查",
"status": "fail" if missing else "pass",
"message": f"缺少: {', '.join(missing)}" if missing else "所有必填项已填写"
})
amount_status = "pass"
amount_message = "金额校验通过"
subtotal = data.get("合计金额") or data.get("订单总额")
tax = data.get("税额")
total = data.get("价税合计") or data.get("实付金额") or data.get("合同总价")
if subtotal and tax and total:
try:
s = float(re.sub(r"[^\d.]", "", subtotal))
t = float(re.sub(r"[^\d.]", "", tax))
tot = float(re.sub(r"[^\d.]", "", total))
if abs(s + t - tot) > 0.01:
amount_status = "warning"
amount_message = f"合计金额({s}) + 税额({t}) = {s+t},与价税合计({tot})不一致"
except ValueError:
amount_status = "warning"
amount_message = "金额字段包含非数字内容,无法自动校验"
else:
amount_status = "warning"
amount_message = "部分金额字段缺失,无法校验"
checks.append({"type": "金额计算验证", "status": amount_status, "message": amount_message})
date_status = "pass"
date_message = "日期格式合理"
date_fields = ["开票日期", "签署日期", "下单日期", "交货日期", "生效日期", "到期日期"]
for field in date_fields:
val = data.get(field)
if val:
for fmt in ["%Y-%m-%d", "%Y年%m月%d日", "%Y/%m/%d", "%Y.%m.%d"]:
try:
dt = datetime.strptime(val, fmt)
if dt > datetime.now():
date_status = "warning"
date_message = f"{field}({val}) 为未来日期"
break
except ValueError:
continue
checks.append({"type": "日期合理性检查", "status": date_status, "message": date_message})
format_status = "pass"
format_message = "格式验证通过"
for tax_field in ["销售方税号", "购买方税号"]:
val = data.get(tax_field)
if val and not re.match(r"^[A-Za-z0-9]{15,20}$", val):
format_status = "warning"
format_message = f"{tax_field}({val}) 格式可能不正确"
break
checks.append({"type": "格式验证", "status": format_status, "message": format_message})
overall = "pass"
if any(c["status"] == "fail" for c in checks):
overall = "fail"
elif any(c["status"] == "warning" for c in checks):
overall = "warning"
return json.dumps({
"file": filename,
"checks": checks,
"overall_status": overall,
"extracted_data": data
}, ensure_ascii=False, indent=2)
except Exception as e:
return f"❌ 验证数据时出错:{str(e)}"
def process_documents(query: str) -> str:
"""批量提取所有单据"""
patterns = ["*.pdf", "*.png", "*.jpg", "*.jpeg"]
results = {}
count = 0
for pattern in patterns:
for file_path in glob.glob(os.path.join(DOCS_DIR, pattern)):
fname = os.path.basename(file_path)
try:
if "发票" in fname or "invoice" in fname:
result = extract_from_file(file_path, INVOICE_SCHEMA)
elif "合同" in fname or "contract" in fname:
result = extract_from_file(file_path, CONTRACT_SCHEMA)
elif "订单" in fname or "order" in fname:
result = extract_from_file(file_path, ORDER_SCHEMA)
else:
result = extract_from_file(file_path, INVOICE_SCHEMA)
results[fname] = result["extracted_schema"]
count += 1
except Exception as e:
results[fname] = f"提取失败: {str(e)}"
return json.dumps({"total": count, "results": results}, ensure_ascii=False, indent=2)
tools = [
Tool(
name="process_documents",
description="批量提取所有单据文档的结构化信息。输入:'提取所有文档' 或文件名。",
func=process_documents
),
Tool(
name="extract_invoice_info",
description="从发票中提取结构化信息,包括发票号码、开票日期、销售方信息、购买方信息、商品明细、金额信息等。输入格式:提取发票信息 文件:发票.pdf",
func=extract_invoice_info
),
Tool(
name="extract_contract_info",
description="从合同中提取关键信息,包括合同编号、签署日期、签约方信息、合同金额、关键条款等。输入格式:提取合同信息 文件:合同.pdf",
func=extract_contract_info
),
Tool(
name="extract_order_info",
description="从订单中提取信息,包括订单号、下单日期、客户信息、商品明细、金额信息等。输入格式:提取订单信息 文件:订单.pdf",
func=extract_order_info
),
Tool(
name="validate_data",
description="验证提取的数据,包括必填项检查、金额计算验证、日期合理性检查、格式验证等。输入格式:验证数据 文件:发票.pdf",
func=validate_data
)
]
# ========== Step 5: 初始化 Agent ==========
agent = initialize_agent(
tools=tools,
llm=llm,
agent=AgentType.ZERO_SHOT_REACT_DESCRIPTION,
verbose=True,
agent_kwargs={
"prefix": """你是一个专业的单据处理助手。你的任务是帮助用户:
1. 从发票、合同、订单中提取关键信息
2. 验证提取的数据完整性和准确性
3. 检查数据格式和合理性
在回答时,请:
- 选择合适的工具提取信息
- 提供结构化的提取结果(JSON格式)
- 明确标注验证结果(通过/失败/警告)
- 如果发现问题,说明具体的问题和建议
- 使用工具获取准确的信息,不要猜测
"""
}
)
# ========== Step 6: 使用示例 ==========
if __name__ == "__main__":
print("=" * 60)
print("示例 1: 提取发票信息")
print("=" * 60)
response = agent.invoke({
"input": "从发票中提取发票号码、开票日期、金额和商品明细 文件:invoice.pdf"
})
print(response["output"])
print()
print("=" * 60)
print("示例 2: 提取合同信息")
print("=" * 60)
response = agent.invoke({
"input": "从合同中提取合同编号、签署日期、签约方和合同金额 文件:contract.pdf"
})
print(response["output"])
print()
print("=" * 60)
print("示例 3: 提取订单信息")
print("=" * 60)
response = agent.invoke({
"input": "从订单中提取订单号、下单日期、客户信息和商品明细 文件:order.pdf"
})
print(response["output"])
print()
print("=" * 60)
print("示例 4: 数据验证")
print("=" * 60)
response = agent.invoke({
"input": "验证发票数据:检查必填项、金额计算、日期合理性、税号格式 文件:invoice.pdf"
})
print(response["output"])
```
## 代码说明
### Step 1: Extract API 配置
`extract_from_file` 是核心辅助函数,负责:
* 读取文件并编码为 Base64
* 构建请求体(文件 + Schema + 选项)
* 调用 Extract API,一步完成文档解析与结构化抽取
* 通过 `x-ti-app-id` 和 `x-ti-secret-code` 请求头进行认证
### Step 2: Schema 定义
为每种单据类型定义抽取 Schema:
* **INVOICE\_SCHEMA**:发票信息(发票号码、销售方/购买方、商品明细、金额等)
* **CONTRACT\_SCHEMA**:合同信息(合同编号、签约方、金额、关键条款等)
* **ORDER\_SCHEMA**:订单信息(订单号、客户信息、商品明细、金额等)
* **VALIDATION\_SCHEMA**:验证用的通用 Schema,覆盖各类单据的关键字段
Schema 遵循 JSON Schema 规范,通过 `type`、`description`、`required` 精确定义提取字段。
### Step 3: 信息提取 Tools
每个 Tool 的工作流程:
1. 从查询中提取文件名
2. 调用 `extract_from_file` 传入对应的 Schema
3. Extract API 直接返回结构化 JSON 结果
**关键点**:不再需要先解析文档再用大模型抽取,Extract API 一步完成。
### Step 4: Agent 配置
Agent 会自动:
* 根据用户意图选择合适的 Tool
* 调用 Extract API 提取信息
* 组织最终的回答
## 使用示例
### 示例 1:提取发票信息
```python theme={null}
response = agent.invoke({
"input": "从发票中提取发票号码、开票日期、销售方税号、购买方税号、商品明细和金额 文件:invoice.pdf"
})
print(response["output"])
```
### 示例 2:提取合同信息
```python theme={null}
response = agent.invoke({
"input": "从合同中提取合同编号、签署日期、甲方、乙方、合同金额和违约责任条款 文件:contract.pdf"
})
print(response["output"])
```
### 示例 3:提取订单信息
```python theme={null}
response = agent.invoke({
"input": "从订单中提取订单号、下单日期、客户信息和商品明细 文件:order.pdf"
})
print(response["output"])
```
### 示例 4:数据验证
```python theme={null}
response = agent.invoke({
"input": "验证提取的发票数据:检查必填项、金额计算、日期合理性、税号格式 文件:invoice.pdf"
})
print(response["output"])
```
## 最佳实践
1. **Schema 设计**:根据实际业务需求定义 Schema 字段,使用 `required` 标记必要字段,使用 `description` 提供清晰的字段说明
2. **文档质量**:对于扫描件和图片,确保分辨率足够,Extract API 内置高精度 OCR 引擎
3. **坐标引用**:开启 `generate_citations` 可获取字段在文档中的位置坐标,便于人工核对
4. **数据验证**:提取后立即验证,确保数据完整性和准确性
5. **批量处理**:使用 `process_documents` 批量提取,提高效率
6. **错误处理**:对于提取失败的单据,记录错误信息,便于人工处理
## 常见问题
**Q: 如何处理模糊的扫描件?**\
A: 1) 使用高质量的扫描件;2) 预处理图片(去噪、增强对比度);3) Extract API 内置了高精度 OCR 引擎,可以处理大多数扫描件。
**Q: 如何自定义提取字段?**\
A: 修改对应的 Schema 定义即可。Schema 遵循 JSON Schema 规范,支持 `string`、`number`、`array`、`object` 等类型,通过 `description` 描述字段含义。
**Q: 如何处理多页单据?**\
A: Extract API 会自动处理多页文档,从所有页面中提取信息。
**Q: 可以使用其他 LLM 吗?**\
A: 可以。Agent 编排部分使用 LangChain,支持多种 LLM,只需替换 `ChatTongyi`(通义千问)为对应的类,如 `ChatOpenAI`(OpenAI)、`ChatZhipuAI`(智谱AI)等。信息提取由 Extract API 完成,不依赖特定 LLM。
## 相关文档
* [快速启动](/xparse/v1/quickstart) - 了解 xParse 基本使用方法
* [文档解析](/api-reference/endpoint/xparse/v1/parse-sync) - 了解文档解析 API
* [Agent教程](/xparse/v1/tutorials/agent-tutorial) - 了解通用 Agent 构建方法
# 信息提取 Agent:结构化数据提取与整理
Source: https://docs.textin.com/xparse/v1/tutorials/information-extraction-agent-tutorial
使用 xParse Extract API + LangChain 构建信息提取 Agent,实现从发票、医疗票据、合同、简历、产品文档、技术文档等文档中提取结构化信息并自动整理
本教程面向信息提取场景,展示如何利用 [xParse Extract API](/api-reference/endpoint/extract-v3) 作为数据底座,构建能够从非结构化文档中提取结构化信息(如发票、医疗票据、合同、简历、产品规格、API接口等)并自动整理的智能Agent。
## 场景介绍
### 业务痛点
在信息提取场景中,企业和开发者面临以下挑战:
* **文档格式多样**:需要处理发票、医疗票据、合同、简历、产品文档、技术文档等多种格式
* **信息提取繁琐**:需要从非结构化文档中提取结构化信息(发票信息、医疗费用、合同条款、个人信息、工作经历、产品参数、API接口等)
* **数据标准化困难**:不同来源的数据格式不统一,需要标准化处理
* **批量处理需求**:需要处理大量文档,手动提取效率低
* **数据验证**:提取的数据需要验证和校验,确保准确性
* **财务合规**:发票和医疗票据需要符合财务和税务要求
* **法律风险**:合同信息提取需要准确识别关键条款和风险点
### 解决方案
通过构建信息提取 Agent,我们可以实现:
* **一步完成解析与提取**:使用 [xParse Extract API](/api-reference/endpoint/extract-v3),文档解析与结构化抽取在一次 API 调用中完成,无需分步处理
* **Schema 驱动提取**:通过定义 JSON Schema 精确控制提取字段和格式,确保输出一致性
* **数据标准化**:将提取的信息转换为标准格式(JSON、CSV等)
* **数据验证**:验证提取的数据完整性和准确性
* **批量处理**:支持批量处理大量文档
* **财务自动化**:自动提取发票和医疗票据信息,支持财务系统对接
* **合同分析**:提取合同关键信息,识别重要条款和风险点
## 架构设计
```
文档(PDF/Word/Excel/图片)
↓
[xParse Extract API]
└─ 解析文档 + 结构化抽取(一步完成)
↓
[LangChain Agent]
├─ Tool 1-7: 调用 Extract API(各自定义 Schema)
↓
结构化数据(JSON/CSV)
```
**核心流程**:
1. 每个提取工具定义专属的 JSON Schema,描述需要提取的字段和结构
2. 调用 xParse Extract API,传入文档文件和 Schema,一步完成解析与结构化抽取
## 环境准备
```bash theme={null}
python -m venv .venv && source .venv/bin/activate
pip install requests langchain langchain-community langchain-core \
python-dotenv pandas
export TEXTIN_APP_ID=your-app-id # 在 TextIn 官网注册获取
export TEXTIN_SECRET_CODE=your-secret-code # 在 TextIn 官网注册获取
export DASHSCOPE_API_KEY=your-dashscope-api-key # 本教程使用通义千问大模型,也可以替换成其他大模型
```
> 提示:`TEXTIN_APP_ID` 与 `TEXTIN_SECRET_CODE` 参考 [API Key](/xparse/api-key),请登录 [Textin 工作台](https://www.textin.com/console/dashboard/setting) 获取。示例中使用 `通义千问` 的大模型能力,其他模型用法类似。
## Step 1:配置 Extract API
定义通用的 Extract API 调用函数和文件路径解析辅助函数:
```python theme={null}
import os
import json
import base64
import requests
from dotenv import load_dotenv
load_dotenv()
EXTRACT_API_URL = "https://api.textin.com/ai/service/v3/entity_extraction"
def extract_from_file(file_path: str, schema: dict, generate_citations: bool = False, stamp: bool = False) -> dict:
"""使用 xParse Extract API 从文档中提取结构化信息"""
with open(file_path, "rb") as f:
file_base64 = base64.b64encode(f.read()).decode("utf-8")
payload = {
"file": {
"file_base64": file_base64,
"file_name": os.path.basename(file_path)
},
"schema": schema,
"extract_options": {
"generate_citations": generate_citations,
"stamp": stamp
}
}
headers = {
"x-ti-app-id": os.getenv("TEXTIN_APP_ID"),
"x-ti-secret-code": os.getenv("TEXTIN_SECRET_CODE"),
"Content-Type": "application/json"
}
response = requests.post(EXTRACT_API_URL, json=payload, headers=headers)
result = response.json()
if result.get("code") != 200:
raise Exception(f"Extract API 错误: {result.get('message', '未知错误')}")
return result["result"]
def _resolve_file_path(file_path: str = None) -> str:
"""解析文件路径,返回有效路径或 None"""
if file_path in ("None", "none", None, "", "null"):
return None
if os.path.exists(file_path):
return file_path
return None
```
## Step 2:构建 LangChain Tools
### 定义提取 Schema
为每种文档类型定义专属的 JSON Schema,精确控制提取字段:
```python expandable theme={null}
INVOICE_SCHEMA = {
"type": "object",
"properties": {
"发票基本信息": {
"type": "object",
"properties": {
"发票代码": {"type": ["string", "null"], "description": "发票代码"},
"发票号码": {"type": ["string", "null"], "description": "发票号码"},
"开票日期": {"type": ["string", "null"], "description": "开票日期"}
}
},
"销售方": {
"type": "object",
"properties": {
"名称": {"type": ["string", "null"], "description": "销售方名称"},
"纳税人识别号": {"type": ["string", "null"], "description": "纳税人识别号"},
"地址电话": {"type": ["string", "null"], "description": "地址电话"},
"开户行及账号": {"type": ["string", "null"], "description": "开户行及账号"}
}
},
"购买方": {
"type": "object",
"properties": {
"名称": {"type": ["string", "null"], "description": "购买方名称"},
"纳税人识别号": {"type": ["string", "null"], "description": "纳税人识别号"},
"地址电话": {"type": ["string", "null"], "description": "地址电话"},
"开户行及账号": {"type": ["string", "null"], "description": "开户行及账号"}
}
},
"商品明细": {
"type": "array",
"description": "商品明细列表",
"items": {
"type": "object",
"properties": {
"名称": {"type": ["string", "null"], "description": "商品名称"},
"规格型号": {"type": ["string", "null"], "description": "规格型号"},
"单位": {"type": ["string", "null"], "description": "单位"},
"数量": {"type": ["string", "null"], "description": "数量"},
"单价": {"type": ["string", "null"], "description": "单价"},
"金额": {"type": ["string", "null"], "description": "金额"},
"税率": {"type": ["string", "null"], "description": "税率"},
"税额": {"type": ["string", "null"], "description": "税额"}
},
"required": ["名称", "规格型号","单位","数量","单价","金额","税率","税额"]
}
},
"金额信息": {
"type": "object",
"properties": {
"合计金额": {"type": ["string", "null"], "description": "合计金额"},
"合计税额": {"type": ["string", "null"], "description": "合计税额"},
"价税合计": {"type": ["string", "null"], "description": "价税合计(大写)"}
}
},
"其他信息": {
"type": "object",
"properties": {
"备注": {"type": ["string", "null"], "description": "备注"},
"收款人": {"type": ["string", "null"], "description": "收款人"},
"复核人": {"type": ["string", "null"], "description": "复核人"},
"开票人": {"type": ["string", "null"], "description": "开票人"}
}
}
},
"required": ["销售方", "购买方", "商品明细", "金额信息", "其他信息","发票基本信息"]
}
MEDICAL_BILL_SCHEMA = {
"type": "object",
"properties": {
"患者信息": {
"type": "object",
"properties": {
"姓名": {"type": ["string", "null"], "description": "患者姓名"},
"性别": {"type": ["string", "null"], "description": "性别"},
"年龄": {"type": ["string", "null"], "description": "年龄"},
"身份证号": {"type": ["string", "null"], "description": "身份证号"},
"医保卡号": {"type": ["string", "null"], "description": "医保卡号"}
}
},
"医疗机构信息": {
"type": "object",
"properties": {
"医院名称": {"type": ["string", "null"], "description": "医院名称"},
"科室": {"type": ["string", "null"], "description": "科室"},
"医生姓名": {"type": ["string", "null"], "description": "医生姓名"}
}
},
"就诊信息": {
"type": "object",
"properties": {
"就诊日期": {"type": ["string", "null"], "description": "就诊日期"},
"就诊类型": {"type": ["string", "null"], "description": "门诊/住院"},
"诊断结果": {"type": ["string", "null"], "description": "诊断结果"}
}
},
"费用明细": {
"type": "array",
"description": "费用明细列表",
"items": {
"type": "object",
"properties": {
"项目名称": {"type": ["string", "null"], "description": "项目名称"},
"数量": {"type": ["string", "null"], "description": "数量"},
"单价": {"type": ["string", "null"], "description": "单价"},
"金额": {"type": ["string", "null"], "description": "金额"},
"医保类型": {"type": ["string", "null"], "description": "甲类/乙类/丙类"}
},
"required": ["项目名称", "金额","数量","单价","医保类型"]
}
},
"费用汇总": {
"type": "object",
"properties": {
"总费用": {"type": ["string", "null"], "description": "总费用"},
"自费金额": {"type": ["string", "null"], "description": "自费金额"},
"医保支付": {"type": ["string", "null"], "description": "医保支付金额"},
"个人支付": {"type": ["string", "null"], "description": "个人支付金额"}
}
},
"其他信息": {
"type": "object",
"properties": {
"发票号码": {"type": ["string", "null"], "description": "发票号码"},
"结算方式": {"type": ["string", "null"], "description": "结算方式"}
}
}
},
"required": ["就诊信息", "费用明细", "费用汇总", "其他信息","医疗机构信息","患者信息"]
}
CONTRACT_SCHEMA = {
"type": "object",
"properties": {
"合同基本信息": {
"type": "object",
"description": "",
"required": ["合同编号","合同名称","签订日期","生效日期","到期日期"],
"properties": {
"合同编号": {
"type": [
"string",
"null"
],
"description": ""
},
"合同名称": {
"type": [
"string",
"null"
],
"description": ""
},
"签订日期": {
"type": [
"string",
"null"
],
"description": ""
},
"生效日期": {
"type": [
"string",
"null"
],
"description": ""
},
"到期日期": {
"type": [
"string",
"null"
],
"description": ""
}
}
},
"合同双方": {
"type": "object",
"description": "",
"required": [
"甲方-名称",
"甲方-地址",
"甲方-法定代表人",
"甲方-联系方式",
"乙方-名称",
"乙方-地址",
"乙方-法定代表人",
"乙方-联系方式"
],
"properties": {
"甲方-名称": {
"type": [
"string",
"null"
],
"description": ""
},
"甲方-地址": {
"type": [
"string",
"null"
],
"description": ""
},
"甲方-法定代表人": {
"type": [
"string",
"null"
],
"description": ""
},
"甲方-联系方式": {
"type": [
"string",
"null"
],
"description": ""
},
"乙方-名称": {
"type": [
"string",
"null"
],
"description": ""
},
"乙方-地址": {
"type": [
"string",
"null"
],
"description": ""
},
"乙方-法定代表人": {
"type": [
"string",
"null"
],
"description": ""
},
"乙方-联系方式": {
"type": [
"string",
"null"
],
"description": ""
}
}
},
"合同标的": {
"type": "object",
"description": "",
"required": [
"标的物",
"数量",
"金额"
],
"properties": {
"标的物": {
"type": [
"string",
"null"
],
"description": ""
},
"数量": {
"type": [
"string",
"null"
],
"description": ""
},
"金额": {
"type": [
"string",
"null"
],
"description": ""
}
}
},
"关键条款": {
"type": "object",
"description": "",
"required": [
"付款方式",
"交付方式",
"违约责任",
"争议解决"
],
"properties": {
"付款方式": {
"type": [
"string",
"null"
],
"description": ""
},
"交付方式": {
"type": [
"string",
"null"
],
"description": ""
},
"违约责任": {
"type": [
"string",
"null"
],
"description": ""
},
"争议解决": {
"type": [
"string",
"null"
],
"description": ""
}
}
},
"金额信息": {
"type": "object",
"description": "",
"required": [
"合同总金额",
"付款计划",
"保证金"
],
"properties": {
"合同总金额": {
"type": [
"string",
"null"
],
"description": ""
},
"付款计划": {
"type": [
"string",
"null"
],
"description": ""
},
"保证金": {
"type": [
"string",
"null"
],
"description": ""
}
}
}
},
"required": [
"合同基本信息",
"合同双方",
"合同标的",
"关键条款",
"金额信息"
]
}
RESUME_SCHEMA = {
"type": "object",
"properties": {
"个人信息": {
"type": "object",
"properties": {
"姓名": {"type": ["string", "null"], "description": "姓名"},
"性别": {"type": ["string", "null"], "description": "性别"},
"年龄": {"type": ["string", "null"], "description": "年龄"},
"电话": {"type": ["string", "null"], "description": "电话"},
"邮箱": {"type": ["string", "null"], "description": "邮箱"},
"地址": {"type": ["string", "null"], "description": "地址"}
}
},
"教育经历": {
"type": "array",
"description": "教育经历列表",
"items": {
"type": "object",
"properties": {
"学校": {"type": ["string", "null"], "description": "学校名称"},
"专业": {"type": ["string", "null"], "description": "专业"},
"学历": {"type": ["string", "null"], "description": "学历(本科/硕士/博士等)"},
"入学时间": {"type": ["string", "null"], "description": "入学时间"},
"毕业时间": {"type": ["string", "null"], "description": "毕业时间"}
},
"required": ["学校","专业","学历","入学时间","毕业时间"]
}
},
"工作经历": {
"type": "array",
"description": "工作经历列表",
"items": {
"type": "object",
"properties": {
"公司": {"type": ["string", "null"], "description": "公司名称"},
"职位": {"type": ["string", "null"], "description": "职位"},
"入职时间": {"type": ["string", "null"], "description": "入职时间"},
"离职时间": {"type": ["string", "null"], "description": "离职时间"},
"工作内容": {"type": ["string", "null"], "description": "主要工作内容"}
},
"required": ["公司","职位","入职时间","离职时间","工作内容"]
}
},
"技能": {
"type": "object",
"properties": {
"专业技能": {"type": "array", "items": {"type": "string"}, "description": "专业技能列表"},
"语言能力": {"type": "array", "items": {"type": "string"}, "description": "语言能力列表"},
"证书": {"type": "array", "items": {"type": "string"}, "description": "证书列表"}
}
}
},
"required": ["技能","工作经历","教育经历","个人信息"]
}
PRODUCT_SPECS_SCHEMA = {
"type": "object",
"properties": {
"产品名称": {"type": ["string", "null"], "description": "产品名称"},
"型号": {"type": ["string", "null"], "description": "产品型号"},
"技术参数": {
"type": "array",
"description": "技术参数列表",
"items": {
"type": "object",
"properties": {
"参数名": {"type": ["string", "null"], "description": "参数名称"},
"参数值": {"type": ["string", "null"], "description": "参数值"},
"单位": {"type": ["string", "null"], "description": "单位"}
},
"required": ["参数名", "参数值","单位"]
}
},
"功能特性": {
"type": "array",
"items": {"type": "string"},
"description": "功能特性列表"
},
"价格信息": {
"type": "object",
"properties": {
"价格": {"type": ["string", "null"], "description": "价格"},
"币种": {"type": ["string", "null"], "description": "币种"}
}
}
},
"required": ["产品名称","型号","技术参数","功能特性","价格信息"]
}
API_INFO_SCHEMA = {
"type": "object",
"properties": {
"接口列表": {
"type": "array",
"description": "API 接口列表",
"items": {
"type": "object",
"properties": {
"端点": {"type": ["string", "null"], "description": "API 端点 URL"},
"请求方法": {"type": ["string", "null"], "description": "GET/POST/PUT/DELETE"},
"描述": {"type": ["string", "null"], "description": "接口描述"},
"响应格式": {"type": ["string", "null"], "description": "响应数据格式描述"},
"认证方式": {"type": ["string", "null"], "description": "认证方式"}
},
"required": ["端点", "请求方法","描述","响应格式","认证方式"]
}
}
},
"required": ["接口列表"]
}
KEY_VALUE_SCHEMA = {
"type": "object",
"properties": {
"键值对列表": {
"type": "array",
"description": "从文档中提取的所有键值对",
"items": {
"type": "object",
"properties": {
"键": {"type": ["string", "null"], "description": "键名"},
"值": {"type": ["string", "null"], "description": "对应的值"}
},
"required": ["键", "值"]
}
}
},
"required": ["键值对列表"]
}
```
### Tool 1: 提取发票信息
```python theme={null}
from langchain_core.tools import Tool
def extract_invoice_info(file_path: str = None) -> str:
"""
从发票中提取结构化信息(使用 xParse Extract API)
提取内容包括:
- 发票基本信息(发票代码、发票号码、开票日期)
- 销售方信息(名称、纳税人识别号、地址电话、开户行及账号)
- 购买方信息(名称、纳税人识别号、地址电话、开户行及账号)
- 商品明细(名称、规格、单位、数量、单价、金额、税率、税额)
- 金额信息(合计金额、合计税额、价税合计)
- 其他信息(备注、收款人、复核人、开票人等)
Args:
file_path: 文档路径
"""
fp = _resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = extract_from_file(fp, INVOICE_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
```
### Tool 2: 提取医疗票据信息
```python theme={null}
def extract_medical_bill_info(file_path: str = None) -> str:
"""
从医疗票据中提取结构化信息(使用 xParse Extract API)
提取内容包括:
- 患者信息(姓名、性别、年龄、身份证号、医保卡号)
- 医疗机构信息(医院名称、科室、医生姓名)
- 就诊信息(就诊日期、就诊类型、诊断结果)
- 费用明细(项目名称、数量、单价、金额、医保类型)
- 费用汇总(总费用、自费金额、医保支付、个人支付)
Args:
file_path: 文档路径
"""
fp = _resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = extract_from_file(fp, MEDICAL_BILL_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
```
### Tool 3: 提取合同信息
```python theme={null}
def extract_contract_info(file_path: str = None) -> str:
"""
从合同中提取结构化信息(使用 xParse Extract API)
提取内容包括:
- 合同基本信息(合同编号、合同名称、签订日期、生效日期、到期日期)
- 合同双方(甲方、乙方:名称、地址、法定代表人、联系方式)
- 合同标的(标的物、数量、金额)
- 关键条款(付款方式、交付方式、违约责任、争议解决)
- 金额信息(合同总金额、付款计划、保证金)
Args:
file_path: 文档路径
"""
fp = _resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = extract_from_file(fp, CONTRACT_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
```
### Tool 4: 提取简历信息
```python theme={null}
def extract_resume_info(file_path: str = None) -> str:
"""
从简历中提取结构化信息(使用 xParse Extract API)
提取内容包括:
- 个人信息(姓名、性别、年龄、联系方式)
- 教育经历(学校、专业、学历、时间)
- 工作经历(公司、职位、时间、工作内容)
- 技能(专业技能、语言能力、证书等)
Args:
file_path: 文档路径
"""
fp = _resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = extract_from_file(fp, RESUME_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
```
### Tool 5: 提取产品规格
```python theme={null}
def extract_product_specs(file_path: str = None) -> str:
"""
从产品文档中提取产品规格和技术参数(使用 xParse Extract API)
提取内容包括:
- 产品名称和型号
- 技术参数(尺寸、重量、性能指标等)
- 功能特性
- 价格信息
Args:
file_path: 文档路径
"""
fp = _resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = extract_from_file(fp, PRODUCT_SPECS_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
```
### Tool 6: 提取 API 信息
```python theme={null}
def extract_api_info(file_path: str = None) -> str:
"""
从技术文档中提取 API 接口信息(使用 xParse Extract API)
提取内容包括:
- API端点(URL路径)
- 请求方法(GET、POST等)
- 请求参数
- 响应格式
- 认证方式
Args:
file_path: 文档路径
"""
fp = _resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = extract_from_file(fp, API_INFO_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
```
### Tool 7: 数据格式化
```python theme={null}
import pandas as pd
def format_data(file_path: str = None) -> str:
"""
从文档中提取键值对并格式化为标准格式(JSON、CSV等)
使用 xParse Extract API 提取文档中的所有键值对信息,
并转换为 JSON 和 CSV 格式。
Args:
file_path: 文档路径
"""
fp = _resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = extract_from_file(fp, KEY_VALUE_SCHEMA)
extracted = result["extracted_schema"]
data_list = extracted.get("键值对列表", [])
if not data_list:
return "未找到可格式化的数据"
json_output = json.dumps(data_list, ensure_ascii=False, indent=2)
try:
df = pd.DataFrame(data_list)
csv_output = df.to_csv(index=False)
except:
csv_output = "CSV格式化失败"
return f"JSON格式:\n{json_output}\n\nCSV格式:\n{csv_output}"
```
### 组装所有Tools
```python theme={null}
tools = [
Tool(
name="extract_invoice_info",
description="从发票中提取结构化信息,包括发票基本信息、销售方/购买方信息、商品明细、金额信息等。需要提供文档路径作为参数。",
func=extract_invoice_info
),
Tool(
name="extract_medical_bill_info",
description="从医疗票据中提取结构化信息,包括患者信息、医疗机构信息、就诊信息、费用明细、费用汇总等。需要提供文档路径作为参数。",
func=extract_medical_bill_info
),
Tool(
name="extract_contract_info",
description="从合同中提取结构化信息,包括合同基本信息、合同双方信息、合同标的、关键条款、金额信息等。需要提供文档路径作为参数。",
func=extract_contract_info
),
Tool(
name="extract_resume_info",
description="从简历中提取结构化信息,包括个人信息、教育经历、工作经历、技能等。需要提供文档路径作为参数。",
func=extract_resume_info
),
Tool(
name="extract_product_specs",
description="从产品文档中提取产品规格和技术参数,包括产品名称、型号、技术参数、功能特性、价格等。需要提供文档路径作为参数。",
func=extract_product_specs
),
Tool(
name="extract_api_info",
description="从技术文档中提取API接口信息,包括API端点、请求方法、请求参数、响应格式等。需要提供文档路径作为参数。",
func=extract_api_info
),
Tool(
name="format_data",
description="从文档中提取键值对信息并格式化为标准格式(JSON、CSV等)。需要提供文档路径作为参数。",
func=format_data
)
]
```
## Step 3:配置 LangChain Agent
```python theme={null}
from langchain_classic.agents import AgentType, initialize_agent
from langchain_community.chat_models import ChatTongyi
llm = ChatTongyi(
model="qwen-max",
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY"),
temperature=0.2,
)
agent_executor = initialize_agent(
tools=tools,
llm=llm,
agent=AgentType.ZERO_SHOT_REACT_DESCRIPTION,
verbose=True,
agent_kwargs={
"prefix": """你是一个专业的信息提取助手。你的任务是帮助用户:
1. 从文档中提取结构化信息(发票、医疗票据、合同、简历、产品规格、API接口等)
2. 将提取的信息格式化为标准格式(JSON、CSV等)
3. 验证提取数据的完整性和准确性
在回答时,请:
- 提供结构化的提取结果
- 使用JSON或表格格式展示数据
- 如果数据不完整,说明缺失的部分
- 使用工具获取准确的信息,不要猜测
- 对于财务类文档(发票、医疗票据),确保金额和税务信息的准确性
- 对于合同文档,重点关注关键条款和风险点
- 所有工具都需要提供文档文件路径作为参数
"""
}
)
```
## Step 4:完整示例代码
```python expandable theme={null}
#!/usr/bin/env python
# -*- coding: utf-8 -*-
"""
信息提取Agent完整示例
"""
import os
import json
import base64
import requests
import pandas as pd
from dotenv import load_dotenv
from langchain_core.tools import Tool
from langchain_classic.agents import AgentType, initialize_agent
from langchain_community.chat_models import ChatTongyi
load_dotenv()
EXTRACT_API_URL = "https://api.textin.com/ai/service/v3/entity_extraction"
INVOICE_SCHEMA = {
"type": "object",
"properties": {
"发票基本信息": {
"type": "object",
"properties": {
"发票代码": {"type": ["string", "null"], "description": "发票代码"},
"发票号码": {"type": ["string", "null"], "description": "发票号码"},
"开票日期": {"type": ["string", "null"], "description": "开票日期"}
}
},
"销售方": {
"type": "object",
"properties": {
"名称": {"type": ["string", "null"], "description": "销售方名称"},
"纳税人识别号": {"type": ["string", "null"], "description": "纳税人识别号"},
"地址电话": {"type": ["string", "null"], "description": "地址电话"},
"开户行及账号": {"type": ["string", "null"], "description": "开户行及账号"}
}
},
"购买方": {
"type": "object",
"properties": {
"名称": {"type": ["string", "null"], "description": "购买方名称"},
"纳税人识别号": {"type": ["string", "null"], "description": "纳税人识别号"},
"地址电话": {"type": ["string", "null"], "description": "地址电话"},
"开户行及账号": {"type": ["string", "null"], "description": "开户行及账号"}
}
},
"商品明细": {
"type": "array",
"description": "商品明细列表",
"items": {
"type": "object",
"properties": {
"名称": {"type": ["string", "null"], "description": "商品名称"},
"规格型号": {"type": ["string", "null"], "description": "规格型号"},
"单位": {"type": ["string", "null"], "description": "单位"},
"数量": {"type": ["string", "null"], "description": "数量"},
"单价": {"type": ["string", "null"], "description": "单价"},
"金额": {"type": ["string", "null"], "description": "金额"},
"税率": {"type": ["string", "null"], "description": "税率"},
"税额": {"type": ["string", "null"], "description": "税额"}
},
"required": ["名称", "规格型号","单位","数量","单价","金额","税率","税额"]
}
},
"金额信息": {
"type": "object",
"properties": {
"合计金额": {"type": ["string", "null"], "description": "合计金额"},
"合计税额": {"type": ["string", "null"], "description": "合计税额"},
"价税合计": {"type": ["string", "null"], "description": "价税合计(大写)"}
}
},
"其他信息": {
"type": "object",
"properties": {
"备注": {"type": ["string", "null"], "description": "备注"},
"收款人": {"type": ["string", "null"], "description": "收款人"},
"复核人": {"type": ["string", "null"], "description": "复核人"},
"开票人": {"type": ["string", "null"], "description": "开票人"}
}
}
},
"required": ["销售方", "购买方", "商品明细", "金额信息", "其他信息","发票基本信息"]
}
MEDICAL_BILL_SCHEMA = {
"type": "object",
"properties": {
"患者信息": {
"type": "object",
"properties": {
"姓名": {"type": ["string", "null"], "description": "患者姓名"},
"性别": {"type": ["string", "null"], "description": "性别"},
"年龄": {"type": ["string", "null"], "description": "年龄"},
"身份证号": {"type": ["string", "null"], "description": "身份证号"},
"医保卡号": {"type": ["string", "null"], "description": "医保卡号"}
}
},
"医疗机构信息": {
"type": "object",
"properties": {
"医院名称": {"type": ["string", "null"], "description": "医院名称"},
"科室": {"type": ["string", "null"], "description": "科室"},
"医生姓名": {"type": ["string", "null"], "description": "医生姓名"}
}
},
"就诊信息": {
"type": "object",
"properties": {
"就诊日期": {"type": ["string", "null"], "description": "就诊日期"},
"就诊类型": {"type": ["string", "null"], "description": "门诊/住院"},
"诊断结果": {"type": ["string", "null"], "description": "诊断结果"}
}
},
"费用明细": {
"type": "array",
"description": "费用明细列表",
"items": {
"type": "object",
"properties": {
"项目名称": {"type": ["string", "null"], "description": "项目名称"},
"数量": {"type": ["string", "null"], "description": "数量"},
"单价": {"type": ["string", "null"], "description": "单价"},
"金额": {"type": ["string", "null"], "description": "金额"},
"医保类型": {"type": ["string", "null"], "description": "甲类/乙类/丙类"}
},
"required": ["项目名称", "金额","数量","单价","医保类型"]
}
},
"费用汇总": {
"type": "object",
"properties": {
"总费用": {"type": ["string", "null"], "description": "总费用"},
"自费金额": {"type": ["string", "null"], "description": "自费金额"},
"医保支付": {"type": ["string", "null"], "description": "医保支付金额"},
"个人支付": {"type": ["string", "null"], "description": "个人支付金额"}
}
},
"其他信息": {
"type": "object",
"properties": {
"发票号码": {"type": ["string", "null"], "description": "发票号码"},
"结算方式": {"type": ["string", "null"], "description": "结算方式"}
}
}
},
"required": ["就诊信息", "费用明细", "费用汇总", "其他信息","医疗机构信息","患者信息"]
}
CONTRACT_SCHEMA = {
"type": "object",
"properties": {
"合同基本信息": {
"type": "object",
"description": "",
"required": ["合同编号","合同名称","签订日期","生效日期","到期日期"],
"properties": {
"合同编号": {
"type": [
"string",
"null"
],
"description": ""
},
"合同名称": {
"type": [
"string",
"null"
],
"description": ""
},
"签订日期": {
"type": [
"string",
"null"
],
"description": ""
},
"生效日期": {
"type": [
"string",
"null"
],
"description": ""
},
"到期日期": {
"type": [
"string",
"null"
],
"description": ""
}
}
},
"合同双方": {
"type": "object",
"description": "",
"required": [
"甲方-名称",
"甲方-地址",
"甲方-法定代表人",
"甲方-联系方式",
"乙方-名称",
"乙方-地址",
"乙方-法定代表人",
"乙方-联系方式"
],
"properties": {
"甲方-名称": {
"type": [
"string",
"null"
],
"description": ""
},
"甲方-地址": {
"type": [
"string",
"null"
],
"description": ""
},
"甲方-法定代表人": {
"type": [
"string",
"null"
],
"description": ""
},
"甲方-联系方式": {
"type": [
"string",
"null"
],
"description": ""
},
"乙方-名称": {
"type": [
"string",
"null"
],
"description": ""
},
"乙方-地址": {
"type": [
"string",
"null"
],
"description": ""
},
"乙方-法定代表人": {
"type": [
"string",
"null"
],
"description": ""
},
"乙方-联系方式": {
"type": [
"string",
"null"
],
"description": ""
}
}
},
"合同标的": {
"type": "object",
"description": "",
"required": [
"标的物",
"数量",
"金额"
],
"properties": {
"标的物": {
"type": [
"string",
"null"
],
"description": ""
},
"数量": {
"type": [
"string",
"null"
],
"description": ""
},
"金额": {
"type": [
"string",
"null"
],
"description": ""
}
}
},
"关键条款": {
"type": "object",
"description": "",
"required": [
"付款方式",
"交付方式",
"违约责任",
"争议解决"
],
"properties": {
"付款方式": {
"type": [
"string",
"null"
],
"description": ""
},
"交付方式": {
"type": [
"string",
"null"
],
"description": ""
},
"违约责任": {
"type": [
"string",
"null"
],
"description": ""
},
"争议解决": {
"type": [
"string",
"null"
],
"description": ""
}
}
},
"金额信息": {
"type": "object",
"description": "",
"required": [
"合同总金额",
"付款计划",
"保证金"
],
"properties": {
"合同总金额": {
"type": [
"string",
"null"
],
"description": ""
},
"付款计划": {
"type": [
"string",
"null"
],
"description": ""
},
"保证金": {
"type": [
"string",
"null"
],
"description": ""
}
}
}
},
"required": [
"合同基本信息",
"合同双方",
"合同标的",
"关键条款",
"金额信息"
]
}
RESUME_SCHEMA = {
"type": "object",
"properties": {
"个人信息": {
"type": "object",
"properties": {
"姓名": {"type": ["string", "null"], "description": "姓名"},
"性别": {"type": ["string", "null"], "description": "性别"},
"年龄": {"type": ["string", "null"], "description": "年龄"},
"电话": {"type": ["string", "null"], "description": "电话"},
"邮箱": {"type": ["string", "null"], "description": "邮箱"},
"地址": {"type": ["string", "null"], "description": "地址"}
}
},
"教育经历": {
"type": "array",
"description": "教育经历列表",
"items": {
"type": "object",
"properties": {
"学校": {"type": ["string", "null"], "description": "学校名称"},
"专业": {"type": ["string", "null"], "description": "专业"},
"学历": {"type": ["string", "null"], "description": "学历(本科/硕士/博士等)"},
"入学时间": {"type": ["string", "null"], "description": "入学时间"},
"毕业时间": {"type": ["string", "null"], "description": "毕业时间"}
},
"required": ["学校","专业","学历","入学时间","毕业时间"]
}
},
"工作经历": {
"type": "array",
"description": "工作经历列表",
"items": {
"type": "object",
"properties": {
"公司": {"type": ["string", "null"], "description": "公司名称"},
"职位": {"type": ["string", "null"], "description": "职位"},
"入职时间": {"type": ["string", "null"], "description": "入职时间"},
"离职时间": {"type": ["string", "null"], "description": "离职时间"},
"工作内容": {"type": ["string", "null"], "description": "主要工作内容"}
},
"required": ["公司","职位","入职时间","离职时间","工作内容"]
}
},
"技能": {
"type": "object",
"properties": {
"专业技能": {"type": "array", "items": {"type": "string"}, "description": "专业技能列表"},
"语言能力": {"type": "array", "items": {"type": "string"}, "description": "语言能力列表"},
"证书": {"type": "array", "items": {"type": "string"}, "description": "证书列表"}
}
}
},
"required": ["技能","工作经历","教育经历","个人信息"]
}
PRODUCT_SPECS_SCHEMA = {
"type": "object",
"properties": {
"产品名称": {"type": ["string", "null"], "description": "产品名称"},
"型号": {"type": ["string", "null"], "description": "产品型号"},
"技术参数": {
"type": "array",
"description": "技术参数列表",
"items": {
"type": "object",
"properties": {
"参数名": {"type": ["string", "null"], "description": "参数名称"},
"参数值": {"type": ["string", "null"], "description": "参数值"},
"单位": {"type": ["string", "null"], "description": "单位"}
},
"required": ["参数名", "参数值","单位"]
}
},
"功能特性": {
"type": "array",
"items": {"type": "string"},
"description": "功能特性列表"
},
"价格信息": {
"type": "object",
"properties": {
"价格": {"type": ["string", "null"], "description": "价格"},
"币种": {"type": ["string", "null"], "description": "币种"}
}
}
},
"required": ["产品名称","型号","技术参数","功能特性","价格信息"]
}
API_INFO_SCHEMA = {
"type": "object",
"properties": {
"接口列表": {
"type": "array",
"description": "API 接口列表",
"items": {
"type": "object",
"properties": {
"端点": {"type": ["string", "null"], "description": "API 端点 URL"},
"请求方法": {"type": ["string", "null"], "description": "GET/POST/PUT/DELETE"},
"描述": {"type": ["string", "null"], "description": "接口描述"},
"响应格式": {"type": ["string", "null"], "description": "响应数据格式描述"},
"认证方式": {"type": ["string", "null"], "description": "认证方式"}
},
"required": ["端点", "请求方法","描述","响应格式","认证方式"]
}
}
},
"required": ["接口列表"]
}
KEY_VALUE_SCHEMA = {
"type": "object",
"properties": {
"键值对列表": {
"type": "array",
"description": "从文档中提取的所有键值对",
"items": {
"type": "object",
"properties": {
"键": {"type": ["string", "null"], "description": "键名"},
"值": {"type": ["string", "null"], "description": "对应的值"}
},
"required": ["键", "值"]
}
}
},
"required": ["键值对列表"]
}
class InformationExtractionAgent:
"""信息提取Agent"""
def __init__(self):
self.setup_llm()
self.setup_agent()
def setup_llm(self):
self.llm = ChatTongyi(
model="qwen-max",
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY"),
temperature=0,
)
@staticmethod
def extract_from_file(file_path: str, schema: dict, generate_citations: bool = False, stamp: bool = False) -> dict:
with open(file_path, "rb") as f:
file_base64 = base64.b64encode(f.read()).decode("utf-8")
payload = {
"file": {
"file_base64": file_base64,
"file_name": os.path.basename(file_path)
},
"schema": schema,
"extract_options": {
"generate_citations": generate_citations,
"stamp": stamp
}
}
headers = {
"x-ti-app-id": os.getenv("TEXTIN_APP_ID"),
"x-ti-secret-code": os.getenv("TEXTIN_SECRET_CODE"),
"Content-Type": "application/json"
}
response = requests.post(EXTRACT_API_URL, json=payload, headers=headers)
result = response.json()
if result.get("code") != 200:
raise Exception(f"Extract API 错误: {result.get('message', '未知错误')}")
return result["result"]
@staticmethod
def _resolve_file_path(file_path: str = None) -> str:
if file_path in ("None", "none", None, "", "null"):
return None
if os.path.exists(file_path):
return file_path
return None
def setup_agent(self):
tools = [
Tool(
name="extract_invoice_info",
description="从发票中提取结构化信息,包括发票基本信息、销售方/购买方信息、商品明细、金额信息等。需要提供文档路径作为参数。",
func=self.extract_invoice_info
),
Tool(
name="extract_medical_bill_info",
description="从医疗票据中提取结构化信息,包括患者信息、医疗机构信息、就诊信息、费用明细、费用汇总等。需要提供文档路径作为参数。",
func=self.extract_medical_bill_info
),
Tool(
name="extract_contract_info",
description="从合同中提取结构化信息,包括合同基本信息、合同双方信息、合同标的、关键条款、金额信息等。需要提供文档路径作为参数。",
func=self.extract_contract_info
),
Tool(
name="extract_resume_info",
description="从简历中提取结构化信息,包括个人信息、教育经历、工作经历、技能等。需要提供文档路径作为参数。",
func=self.extract_resume_info
),
Tool(
name="extract_product_specs",
description="从产品文档中提取产品规格和技术参数,包括产品名称、型号、技术参数、功能特性、价格等。需要提供文档路径作为参数。",
func=self.extract_product_specs
),
Tool(
name="extract_api_info",
description="从技术文档中提取API接口信息,包括API端点、请求方法、请求参数、响应格式等。需要提供文档路径作为参数。",
func=self.extract_api_info
),
Tool(
name="format_data",
description="从文档中提取键值对信息并格式化为标准格式(JSON、CSV等)。需要提供文档路径作为参数。",
func=self.format_data
)
]
self.agent = initialize_agent(
tools=tools,
llm=self.llm,
agent=AgentType.ZERO_SHOT_REACT_DESCRIPTION,
verbose=True,
agent_kwargs={
"prefix": """你是一个专业的信息提取助手。你的任务是帮助用户:
1. 从文档中提取结构化信息(发票、医疗票据、合同、简历、产品规格、API接口等)
2. 将提取的信息格式化为标准格式(JSON、CSV等)
3. 验证提取数据的完整性和准确性
在回答时,请:
- 提供结构化的提取结果
- 使用JSON或表格格式展示数据
- 如果数据不完整,说明缺失的部分
- 使用工具获取准确的信息,不要猜测
- 对于财务类文档(发票、医疗票据),确保金额和税务信息的准确性
- 对于合同文档,重点关注关键条款和风险点
- 所有工具都需要提供文档文件路径作为参数
"""
}
)
def extract_invoice_info(self, file_path: str = None) -> str:
fp = self._resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = self.extract_from_file(fp, INVOICE_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
def extract_medical_bill_info(self, file_path: str = None) -> str:
fp = self._resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = self.extract_from_file(fp, MEDICAL_BILL_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
def extract_contract_info(self, file_path: str = None) -> str:
fp = self._resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = self.extract_from_file(fp, CONTRACT_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
def extract_resume_info(self, file_path: str = None) -> str:
fp = self._resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = self.extract_from_file(fp, RESUME_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
def extract_product_specs(self, file_path: str = None) -> str:
fp = self._resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = self.extract_from_file(fp, PRODUCT_SPECS_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
def extract_api_info(self, file_path: str = None) -> str:
fp = self._resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = self.extract_from_file(fp, API_INFO_SCHEMA)
return json.dumps(result["extracted_schema"], ensure_ascii=False, indent=2)
def format_data(self, file_path: str = None) -> str:
fp = self._resolve_file_path(file_path)
if not fp:
return "错误:请提供有效的文档路径。"
result = self.extract_from_file(fp, KEY_VALUE_SCHEMA)
extracted = result["extracted_schema"]
data_list = extracted.get("键值对列表", [])
if not data_list:
return "未找到可格式化的数据"
json_output = json.dumps(data_list, ensure_ascii=False, indent=2)
try:
df = pd.DataFrame(data_list)
csv_output = df.to_csv(index=False)
except:
csv_output = "CSV格式化失败"
return f"JSON格式:\n{json_output}\n\nCSV格式:\n{csv_output}"
def query(self, question: str) -> str:
"""查询 Agent,获取响应结果"""
response = self.agent.invoke({"input": question})
return response["output"]
def main():
agent = InformationExtractionAgent()
questions = [
"从 ./extraction_documents/invoice.pdf 中提取发票代码、发票号码、销售方和购买方信息、商品明细和金额",
# "从 ./extraction_documents/medical_bill.pdf 中提取患者信息、医院信息、诊断结果和费用明细",
# "从 ./extraction_documents/contract.pdf 中提取合同编号、合同双方信息、合同金额和关键条款",
# "从 ./extraction_documents/resume.pdf 中提取所有个人信息、教育经历和工作经历",
# "从 ./extraction_documents/product_spec.pdf 中提取产品规格和技术参数",
# "从 ./extraction_documents/api_docs.pdf 中提取所有API接口信息",
"将 ./extraction_documents/invoice.pdf 中的数据格式化为JSON格式"
]
for question in questions:
print(f"\n{'='*60}")
print(f"问题: {question}")
print(f"{'='*60}")
answer = agent.query(question)
print(f"\n回答:\n{answer}")
if __name__ == "__main__":
main()
```
## 使用示例
### 示例1:提取发票信息
```python theme={null}
agent = InformationExtractionAgent()
response = agent.query("从 ./extraction_documents/invoice.pdf 中提取发票代码、发票号码、销售方和购买方信息、商品明细和金额")
print(response)
```
### 示例2:提取医疗票据信息
```python theme={null}
response = agent.query("从 ./extraction_documents/medical_bill.pdf 中提取患者姓名、医院名称、诊断结果、总费用和医保支付金额")
print(response)
```
### 示例3:提取合同信息
```python theme={null}
response = agent.query("从 ./extraction_documents/contract.pdf 中提取合同编号、甲方和乙方信息、合同金额、付款方式和违约责任")
print(response)
```
### 示例4:提取简历信息
```python theme={null}
response = agent.query("从 ./extraction_documents/resume.pdf 中提取姓名、联系方式、教育经历和工作经历")
print(response)
```
### 示例5:提取产品规格
```python theme={null}
response = agent.query("从 ./extraction_documents/product_spec.pdf 中提取产品名称、型号、技术参数和价格")
print(response)
```
### 示例6:提取API信息
```python theme={null}
response = agent.query("从 ./extraction_documents/api_docs.pdf 中提取所有API端点、请求方法和参数")
print(response)
```
## 最佳实践
1. **Schema 设计**:为每种文档类型设计专属的 JSON Schema,精确定义需要提取的字段、类型和约束,确保输出格式一致
2. **批量处理**:支持批量处理多个文档,提高效率
3. **格式标准化**:将提取的数据转换为标准格式(JSON、CSV),便于后续处理
4. **财务文档处理**:
* 发票提取时重点关注发票代码、号码、金额等关键信息
* 医疗票据提取时注意区分自费、医保支付等不同费用类型
* 确保金额计算的准确性,支持财务系统对接
5. **合同文档处理**:
* 重点关注合同双方信息、合同金额、关键条款
* 识别违约责任、争议解决等重要条款
* 提取合同有效期,便于合同管理
6. **引用溯源**:对需要审核的场景,可以在调用 `extract_from_file` 时设置 `generate_citations=True`,获取提取结果在原文中的引用位置
7. **错误处理**:对提取失败的情况进行记录和人工复核,检查 API 返回的错误信息
8. **性能优化**:Extract API 在服务端完成解析和抽取,无需本地部署解析引擎,适合大规模批量处理
## 常见问题
**Q: 如何提高提取准确率?**\
A: 1) 优化 JSON Schema,精确定义字段和描述信息;2) 确保文档清晰,避免模糊或低质量的扫描件;3) 对提取结果进行验证和校验。
**Q: 如何处理格式不统一的文档?**\
A: 1) Extract API 支持多种文档格式(PDF、Word、Excel、图片等),会自动处理格式差异;2) 通过 Schema 统一输出格式;3) 人工校验和修正。
**Q: 如何批量处理大量文档?**\
A: 1) 遍历文档目录,逐个调用提取工具;2) 并行处理多个文档(使用多线程或异步);3) 使用队列管理任务,避免并发过高。
**Q: 发票信息提取不准确怎么办?**\
A: 1) 确保发票图片清晰;2) 优化 Schema 中的字段描述;3) 启用 `generate_citations=True` 检查引用位置,排查问题字段;4) 对于特殊格式的发票,可以调整 Schema 适配。
**Q: 医疗票据的费用明细如何提取?**\
A: 1) MEDICAL\_BILL\_SCHEMA 已定义费用明细数组,包含项目名称、数量、单价、金额、医保类型等字段;2) 费用汇总包含总费用、自费金额、医保支付、个人支付等;3) Extract API 能自动识别表格结构。
**Q: 合同关键条款如何识别?**\
A: 1) CONTRACT\_SCHEMA 已定义关键条款字段(付款方式、交付方式、违约责任、争议解决);2) 可以根据业务需求扩展 Schema,添加更多条款字段;3) 启用 citations 获取条款在原文中的位置。
## 相关文档
* [快速启动](/xparse/v1/quickstart) - 了解 xParse SDK 基本使用方法
* [xParse SDK 参考](/xparse/v1/sdk-python) - 了解 SDK API 详情
* [Agent教程](/xparse/v1/tutorials/agent-tutorial) - 了解通用Agent构建方法
# 医疗文档 Agent:智能病历分析与诊断辅助
Source: https://docs.textin.com/xparse/v1/tutorials/medical-agent-tutorial
使用 xParse SDK + LangChain 构建医疗文档处理 Agent,实现病历解析、医疗信息提取、相似病例检索和药物相互作用检查
本教程面向医疗场景,展示如何利用 [xParse SDK](/xparse/v1/sdk-python) 解析医疗文档,然后通过大模型自动提取医疗信息、检索相似病例和检查药物相互作用。
## 场景介绍
### 业务痛点
在医疗场景中,医生和医疗工作者面临以下挑战:
* **文档类型多样**:需要处理病历、检查报告、处方单、医学影像报告等多种格式
* **信息提取复杂**:需要从非结构化文档中提取症状、诊断、用药、检查结果等关键信息
* **病例检索困难**:需要快速检索相似病例和医学文献,辅助诊断决策
* **药物安全**:需要检查药物相互作用、过敏史、用药禁忌等安全问题
* **隐私保护**:医疗数据涉及患者隐私,需要安全处理
### 解决方案
通过构建医疗文档Agent,我们可以实现:
* **自动化文档解析**:使用 [xParse SDK](/xparse/v1/sdk-python) 自动解析各类医疗文档
* **智能信息提取**:调用 [xParse Extract API](/api-reference/endpoint/extract-v3) 直接从文档中提取结构化医疗信息(症状、诊断、用药等)
* **相似病例检索**:基于症状和诊断,从历史病例中检索相似案例
* **药物安全检查**:检查药物相互作用、过敏史、用药禁忌等
* **医学文献检索**:检索相关的医学文献和研究资料
## 架构设计
```
医疗文档(PDF/图片/Word)
↓
[xParse SDK] 解析 + 分块 + 向量化
↓
向量数据库(Milvus)
↓
[LangChain Agent]
├─ Tool 1: extract_medical_info(xParse Extract API)
├─ Tool 2: search_similar_cases(向量检索)
├─ Tool 3: check_drug_interaction(向量检索 + LLM 分析)
└─ Tool 4: search_medical_literature(向量检索)
↓
诊断辅助报告
```
**核心思路**:
* **信息提取**:使用 [xParse Extract API](/api-reference/endpoint/extract-v3) 直接从文档中提取结构化医疗信息,无需先检索再提取
* **相似病例检索**:使用向量检索找到语义相似的病例
* **医学文献检索**:使用向量检索找到相关的医学文献
* **药物安全检查**:大模型分析检索到的用药信息
## 环境准备
首先安装必要的依赖:
```bash theme={null}
python -m venv .venv && source .venv/bin/activate
pip install xparse-client langchain langchain-community langchain-core langchain-text-splitters langchain-milvus \
pymilvus python-dotenv dashscope requests
```
创建 `.env` 文件存储配置:
```bash theme={null}
# .env
TEXTIN_APP_ID=your-app-id
TEXTIN_SECRET_CODE=your-secret-code
MILVUS_DB_PATH=./medical_vectors.db
DASHSCOPE_API_KEY=your-dashscope-key
```
> 提示:`TEXTIN_APP_ID` 与 `TEXTIN_SECRET_CODE` 参考 [API Key](/xparse/api-key),请登录 [Textin 工作台](https://www.textin.com/console/dashboard/setting) 获取。示例中使用 `通义千问` 的大模型能力,其他模型用法类似。
## 完整代码示例
下面是一个完整的、可以直接运行的示例:
```python expandable theme={null}
import os
import json
import glob
import base64
import requests
from dotenv import load_dotenv
from xparse_client import XParseClient
from langchain_text_splitters import MarkdownHeaderTextSplitter, RecursiveCharacterTextSplitter
from langchain_core.tools import Tool
from langchain_classic.agents import AgentType, initialize_agent
from langchain_core.messages import HumanMessage
from langchain_community.chat_models import ChatTongyi
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
load_dotenv()
# ========== Step 1: 初始化 xParse SDK 并处理文档 ==========
client = XParseClient()
def process_documents() -> str:
"""处理医疗文档"""
try:
docs_dir = "/your/medical/documents/folder"
headers_to_split_on = [("#", "header1"), ("##", "header2"), ("###", "header3")]
markdown_splitter = MarkdownHeaderTextSplitter(headers_to_split_on=headers_to_split_on)
text_splitter = RecursiveCharacterTextSplitter(chunk_size=1536, chunk_overlap=100)
all_chunks = []
patterns = ["*.pdf", "*.png", "*.jpg", "*.jpeg", "*.docx"]
for pattern in patterns:
for file_path in glob.glob(os.path.join(docs_dir, pattern)):
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
md_docs = markdown_splitter.split_text(result.markdown)
for doc in md_docs:
doc.metadata["filename"] = os.path.basename(file_path)
chunks = text_splitter.split_documents(md_docs)
all_chunks.extend(chunks)
embedding = DashScopeEmbeddings(model="text-embedding-v4")
Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="medical_documents",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
return "✅ 已处理所有医疗文档,解析结果已存入向量数据库。"
except Exception as e:
return f"❌ 处理文档时出错:{str(e)}"
def process_single_file(file_path: str) -> str:
"""处理单个文件"""
try:
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
headers_to_split_on = [("#", "header1"), ("##", "header2"), ("###", "header3")]
markdown_splitter = MarkdownHeaderTextSplitter(headers_to_split_on=headers_to_split_on)
text_splitter = RecursiveCharacterTextSplitter(chunk_size=1536, chunk_overlap=100)
md_docs = markdown_splitter.split_text(result.markdown)
for doc in md_docs:
doc.metadata["filename"] = os.path.basename(file_path)
chunks = text_splitter.split_documents(md_docs)
embedding = DashScopeEmbeddings(model="text-embedding-v4")
Milvus.from_documents(
documents=chunks,
embedding=embedding,
collection_name="medical_documents",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
return f"✅ 成功处理文件 {file_path},解析结果已存入向量数据库。"
except Exception as e:
return f"❌ 处理文件 {file_path} 时出错:{str(e)}"
# ========== Step 2: 初始化向量数据库 ==========
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus(
embedding_function=embedding,
collection_name="medical_documents",
connection_args={"uri": os.getenv("MILVUS_DB_PATH")},
)
# ========== Step 3: 初始化大模型 ==========
llm = ChatTongyi(
model="qwen-max",
top_p=0.8,
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY")
)
# ========== Step 4: 构建 LangChain Tools ==========
EXTRACT_API_URL = "https://api.textin.com/ai/service/v3/entity_extraction"
def extract_from_file(file_path: str, schema: dict, generate_citations: bool = False) -> dict:
with open(file_path, "rb") as f:
file_base64 = base64.b64encode(f.read()).decode("utf-8")
payload = {
"file": {"file_base64": file_base64, "file_name": os.path.basename(file_path)},
"schema": schema,
"extract_options": {"generate_citations": generate_citations}
}
headers = {
"x-ti-app-id": os.getenv("TEXTIN_APP_ID"),
"x-ti-secret-code": os.getenv("TEXTIN_SECRET_CODE"),
"Content-Type": "application/json"
}
response = requests.post(EXTRACT_API_URL, json=payload, headers=headers)
result = response.json()
if result.get("code") != 200:
raise Exception(f"Extract API 错误: {result.get('message', '未知错误')}")
return result["result"]
MEDICAL_SCHEMA = {
"type": "object",
"properties": {
"基本信息": {
"type": "object",
"description": "患者基本信息",
"properties": {
"年龄": {"type": ["string", "null"], "description": "患者年龄"},
"性别": {"type": ["string", "null"], "description": "患者性别"},
"就诊日期": {"type": ["string", "null"], "description": "就诊日期"}
}
},
"症状": {
"type": "array",
"description": "患者症状列表(主诉、现病史中的症状描述)",
"items": {"type": "string"}
},
"诊断": {
"type": "array",
"description": "诊断结果列表(初步诊断、最终诊断、临床诊断)",
"items": {"type": "string"}
},
"用药": {
"type": "array",
"description": "用药信息列表",
"items": {
"type": "object",
"properties": {
"药物名称": {"type": ["string", "null"], "description": "药物名称"},
"剂量": {"type": ["string", "null"], "description": "剂量"},
"用法": {"type": ["string", "null"], "description": "用法用量"}
},
"required": ["药物名称", "剂量", "用法"]
}
},
"检查结果": {
"type": "array",
"description": "检查检验结果列表",
"items": {
"type": "object",
"properties": {
"检查项目": {"type": ["string", "null"], "description": "检查项目名称"},
"结果": {"type": ["string", "null"], "description": "检查结果"}
},
"required": ["检查项目", "结果"]
}
}
},
"required": ["基本信息", "症状", "诊断", "用药", "检查结果"]
}
def extract_medical_info(query: str) -> str:
"""从医疗文档中提取关键医疗信息"""
docs_dir = "/your/medical/documents/folder"
if "文件:" in query:
filename = query.split("文件:")[-1].strip()
file_path = os.path.join(docs_dir, filename)
else:
files = []
for pattern in ["*.pdf", "*.png", "*.jpg", "*.jpeg", "*.docx"]:
files.extend(glob.glob(os.path.join(docs_dir, pattern)))
if not files:
return "❌ 未找到医疗文档,请确认文档目录。"
file_path = files[0]
if not os.path.exists(file_path):
return f"❌ 文件不存在: {file_path}"
try:
result = extract_from_file(file_path, MEDICAL_SCHEMA, generate_citations=True)
extracted = result["extracted_schema"]
citations = result.get("citations", {})
extracted["来源文件"] = os.path.basename(file_path)
return json.dumps(extracted, ensure_ascii=False, indent=2)
except Exception as e:
return f"❌ 提取医疗信息时出错:{str(e)}"
def search_similar_cases(query: str) -> str:
"""
检索相似病例
基于症状、诊断等信息,使用向量检索找到语义相似的病例
"""
docs = vector_store.similarity_search(query, k=5)
if not docs:
return "❌ 未找到相似病例,请先运行文档处理。"
results = []
for i, doc in enumerate(docs, 1):
text = doc.page_content
metadata = doc.metadata
filename = metadata.get('filename', 'unknown')
page_num = metadata.get('page_number', '?')
prompt = f"""请从以下病例文本中提取关键信息:
病例文本:
{text}
请返回JSON格式:
{{
"diagnosis": "诊断信息",
"symptoms": "症状信息",
"summary": "病例摘要(100字以内)"
}}
只返回JSON,不要其他文字。"""
try:
response = llm.invoke([HumanMessage(content=prompt)])
case_info = json.loads(response.content)
except:
case_info = {"diagnosis": "未提取", "symptoms": "未提取", "summary": text[:100]}
results.append({
f"相似病例 {i}": {
"文件": filename,
"页码": page_num,
"诊断": case_info.get("diagnosis", "未找到"),
"症状": case_info.get("symptoms", "未找到"),
"相似度": "高" if i <= 2 else "中",
"病例摘要": case_info.get("summary", text[:200])
}
})
return json.dumps(results, ensure_ascii=False, indent=2)
def check_drug_interaction(query: str) -> str:
"""
检查药物相互作用
检查多种药物之间是否存在相互作用、过敏史、用药禁忌等
"""
docs = vector_store.similarity_search(query, k=3)
if not docs:
return "❌ 未找到相关医疗文档,请先运行文档处理。"
texts = []
sources = []
for doc in docs:
texts.append(doc.page_content)
filename = doc.metadata.get('filename', 'unknown')
page_num = doc.metadata.get('page_number', '?')
sources.append(f"{filename} (第{page_num}页)")
combined_text = "\n\n".join(texts)
prompt = f"""请检查以下医疗文档中的药物是否存在相互作用、过敏史、用药禁忌等安全问题:
医疗文档文本:
{combined_text}
请返回JSON格式的检查结果:
{{
"medications_found": ["药物1", "药物2", ...],
"interactions": [
{{
"drug1": "药物1",
"drug2": "药物2",
"warning": "相互作用警告信息",
"severity": "严重/中等/轻微"
}}
],
"allergies": ["过敏药物列表"],
"contraindications": ["用药禁忌列表"],
"overall_status": "安全/警告/危险",
"sources": {json.dumps(sources, ensure_ascii=False)}
}}
只返回JSON,不要其他文字。"""
try:
response = llm.invoke([HumanMessage(content=prompt)])
result = json.loads(response.content)
return json.dumps(result, ensure_ascii=False, indent=2)
except Exception as e:
return f"❌ 检查药物相互作用时出错:{str(e)}"
def search_medical_literature(query: str) -> str:
"""
检索医学文献
使用向量检索找到相关的医学文献和研究资料
"""
docs = vector_store.similarity_search(query, k=5)
if not docs:
return "❌ 未找到相关医学文献,请先运行文档处理。"
results = []
for i, doc in enumerate(docs, 1):
text = doc.page_content
metadata = doc.metadata
filename = metadata.get('filename', 'unknown')
page_num = metadata.get('page_number', '?')
is_literature = any(keyword in text for keyword in ["研究", "文献", "期刊", "论文", "参考文献"])
prompt = f"""请从以下文档中提取关键信息:
文档文本:
{text}
请返回JSON格式:
{{
"type": "医学文献/病历/报告",
"summary": "内容摘要(100字以内)",
"key_points": ["关键点1", "关键点2"]
}}
只返回JSON,不要其他文字。"""
try:
response = llm.invoke([HumanMessage(content=prompt)])
doc_info = json.loads(response.content)
except:
doc_info = {"type": "医学文献" if is_literature else "病历/报告", "summary": text[:100], "key_points": []}
results.append({
f"文献 {i}": {
"标题": filename,
"页码": page_num,
"类型": doc_info.get("type", "未知"),
"相关性": "高" if i <= 2 else "中",
"内容摘要": doc_info.get("summary", text[:200]),
"关键点": doc_info.get("key_points", [])
}
})
return json.dumps(results, ensure_ascii=False, indent=2)
# 定义工具列表
tools = [
Tool(
name="process_documents",
description="处理医疗文档,将PDF/图片/Word解析成文本。输入可以是'处理所有文档'或文件路径。",
func=lambda q: process_documents() if "所有" in q else process_single_file(q)
),
Tool(
name="extract_medical_info",
description="从医疗文档中提取关键医疗信息(症状、诊断、用药、检查结果、基本信息等)。输入格式:提取医疗信息 文件:病历.pdf",
func=extract_medical_info
),
Tool(
name="search_similar_cases",
description="检索相似病例,基于症状、诊断等信息查找历史相似病例。输入应为症状或诊断描述,如'发热、咳嗽、胸闷'。",
func=search_similar_cases
),
Tool(
name="check_drug_interaction",
description="检查药物相互作用,检查多种药物之间是否存在相互作用、过敏史、用药禁忌等。输入格式:检查药物相互作用 文件:处方.pdf 或直接提供药物列表。",
func=check_drug_interaction
),
Tool(
name="search_medical_literature",
description="检索医学文献,查找相关的医学研究文献和资料。输入应为要检索的医学主题或关键词,如'高血压治疗'。",
func=search_medical_literature
)
]
# ========== Step 5: 初始化 Agent ==========
agent = initialize_agent(
tools=tools,
llm=llm,
agent=AgentType.ZERO_SHOT_REACT_DESCRIPTION,
verbose=True,
)
# ========== Step 6: 使用示例 ==========
if __name__ == "__main__":
print("=" * 60)
print("示例 1: 处理医疗文档")
print("=" * 60)
response = agent.invoke({
"input": "请处理所有医疗文档"
})
print(response["output"])
print()
print("=" * 60)
print("示例 2: 提取医疗信息")
print("=" * 60)
response = agent.invoke({
"input": "从病历中提取患者的主诉、诊断和用药信息 文件:patient_record.pdf"
})
print(response["output"])
print()
print("=" * 60)
print("示例 3: 检索相似病例")
print("=" * 60)
response = agent.invoke({
"input": "检索与'发热、咳嗽、胸闷'症状相似的病例"
})
print(response["output"])
print()
print("=" * 60)
print("示例 4: 药物安全检查")
print("=" * 60)
response = agent.invoke({
"input": "检查处方中的药物是否存在相互作用 文件:prescription.pdf"
})
print(response["output"])
print()
print("=" * 60)
print("示例 5: 检索医学文献")
print("=" * 60)
response = agent.invoke({
"input": "检索关于'高血压治疗'的医学文献"
})
print(response["output"])
```
## 代码说明
### Step 1: xParse SDK 解析与文本处理
文档处理分为三个阶段:
* **解析**:使用 `XParseClient` 的 `client.parse.run()` 解析医疗文档,返回 Markdown 格式的结构化文本
* **分块**:使用 LangChain 的 `MarkdownHeaderTextSplitter` 按标题分块保持病历章节结构,再用 `RecursiveCharacterTextSplitter` 进行二次分块控制块大小
* **向量化**:使用 `DashScopeEmbeddings` 生成向量,通过 `Milvus.from_documents()` 存入向量数据库
**为什么使用 LangChain 分块和向量化**:
* `MarkdownHeaderTextSplitter` 能识别 Markdown 标题层级,按病历章节自然分块
* `RecursiveCharacterTextSplitter` 控制块大小(1536字符)并保留上下文重叠(100字符)
* 向量检索比文本匹配更准确,能理解医学概念和术语的语义关系
### Step 2: 向量数据库初始化
使用与文档处理相同的 embedding 模型初始化向量数据库连接,保证语义空间一致。
### Step 3: 大模型初始化
使用通义千问(qwen-max)作为大模型,用于信息提取和结果分析。
### Step 4: Tools 实现
* **extract\_medical\_info**:使用 xParse Extract API 直接从文档中提取结构化医疗信息,无需先检索再提取
* **search\_similar\_cases**:使用向量检索找到语义相似的病例,再用大模型提取关键信息
* **check\_drug\_interaction**:使用向量检索找到相关用药信息,再用大模型检查相互作用
* **search\_medical\_literature**:使用向量检索找到相关文献,再用大模型提取关键信息
**关键点**:`extract_medical_info` 通过 Extract API 直接对源文件进行结构化提取,避免了向量检索 + LLM 提取的两步流程,提取结果更完整准确。其他工具结合向量检索(语义相似度)和大模型(信息提取和分析),既快速又准确。
### Step 5: Agent 配置
Agent 会自动:
* 判断是否需要先处理文档
* 选择合适的 Tool 提取信息或检索
* 组织最终的回答
## 使用示例
### 示例 1:处理文档
```python theme={null}
response = agent.invoke({
"messages": [HumanMessage(content="请处理所有医疗文档")]
})
print(response["messages"][-1].content)
```
### 示例 2:提取医疗信息
```python theme={null}
response = agent.invoke({
"messages": [HumanMessage(content="从病历中提取患者的主诉、诊断和用药信息 文件:patient_record.pdf")]
})
print(response["messages"][-1].content)
```
### 示例 3:检索相似病例
```python theme={null}
response = agent.invoke({
"messages": [HumanMessage(content="检索与'发热、咳嗽、胸闷'症状相似的病例")]
})
print(response["messages"][-1].content)
```
### 示例 4:药物安全检查
```python theme={null}
response = agent.invoke({
"messages": [HumanMessage(content="检查处方中的'阿司匹林'和'华法林'是否存在相互作用 文件:prescription.pdf")]
})
print(response["messages"][-1].content)
```
### 示例 5:检索医学文献
```python theme={null}
response = agent.invoke({
"messages": [HumanMessage(content="检索关于'高血压治疗'的医学文献")]
})
print(response["messages"][-1].content)
```
## 最佳实践
1. **隐私保护**:医疗数据涉及患者隐私,确保数据加密存储和传输
2. **分块策略**:使用 `MarkdownHeaderTextSplitter` 按标题分块保持病历章节结构,便于理解上下文
3. **块大小控制**:通过 `chunk_size=1536` 和 `chunk_overlap=100` 平衡语义完整性和检索精度
4. **药物数据库**:在实际应用中,建议集成专业的药物相互作用数据库,提高检查准确性
5. **多语言支持**:医疗术语可能涉及多语言,确保解析引擎支持
6. **结果验证**:Agent 的建议仅供参考,最终诊断需由医生确认
7. **提示工程**:优化大模型的提示词,提高提取和检索准确率
8. **错误处理**:对于识别失败或提取错误的情况,记录错误信息,便于人工处理
## 常见问题
**Q: 如何处理手写病历?**\
A: 使用支持 OCR 的解析引擎(TextIn xParse),可以识别手写内容,但准确率可能低于打印文档。建议预处理图片(开启 xParse 切边增强)提高识别率。
**Q: 如何提高诊断准确性?**\
A: 1) 优化提示词,明确要求提取的字段;2) 使用更强的模型(如 qwen-max);3) 结合多个检查结果综合判断;4) 参考最新的医学文献。
**Q: 如何保护患者隐私?**\
A: 1) 数据加密存储;2) 访问权限控制;3) 日志脱敏处理;4) 符合HIPAA等医疗数据保护法规;5) 不在提示词中包含患者姓名等敏感信息。
**Q: 可以使用其他 LLM 吗?**\
A: 可以。LangChain 支持多种 LLM,只需替换 `ChatTongyi`(通义千问)为对应的类,如 `ChatOpenAI`(OpenAI)、`ChatZhipuAI`(智谱AI)等。
**Q: 如何提高相似病例检索的准确性?**\
A: 1) 在提示词中明确相似度判断标准;2) 要求大模型提取关键特征(症状、诊断、检查结果)进行匹配;3) 可以结合多个文档综合判断。
## 相关文档
* [快速启动](/xparse/v1/quickstart) - 了解 xParse SDK 基本使用方法
* [xParse SDK 参考](/xparse/v1/sdk-python) - 了解 SDK API 详情
* [Agent教程](/xparse/v1/tutorials/agent-tutorial) - 了解通用Agent构建方法
# 实战教程导览
Source: https://docs.textin.com/xparse/v1/tutorials/overview
按场景分类的 xParse 实战教程,涵盖信息抽取、RAG 应用、智能 Agent 助手和平台集成。
如果您是首次接触 xParse,建议先阅读 [Python SDK 文档](/xparse/v1/sdk-python) 和 [API 参考](/api-reference/endpoint/xparse/v1/parse-sync),了解基本用法后再开始实战教程。您也可以直接上手,在实践中学习。
## xParse + LangChain 构建 Agent
使用 xParse API 从文档中提取结构化数据,适用于发票、合同、订单、病历、财务等场景。
支持发票、医疗票据、合同、简历、产品规格、API 文档等多类型文档的自动化提取。
发票、合同、订单的自动化处理与数据验证。
自动化合规审核、异常检测和财务数据提取。
病历解析、相似病例检索、药物相互作用检查。
自动解析文档、更新知识库、智能问答的一体化助手。
## RAG 应用
使用 xParse SDK 解析文档 + LangChain 分块/嵌入,构建检索增强生成应用。
覆盖企业知识库、法律文档检索、技术文档问答三大场景。
基于 LangGraph 的智能 RAG,支持问题重写、相关性评估和迭代优化。
## Dify 平台集成
通过 Dify 平台的可视化界面,快速搭建基于 xParse 的 RAG 和 Agent 应用。
通过知识流水线创建知识库,搭建 Chatflow 智能问答应用。
## 示例 Demo
开源示例项目集合,每个项目独立可运行,覆盖银行流水、发票、医疗报告、合同审查、招标文件、财务报表等场景。
开箱即用的结构化抽取示例项目,前后端完整,支持一键启动。
# 分钟级构建多场景 RAG 应用
Source: https://docs.textin.com/xparse/v1/tutorials/rag-tutorial
使用 xParse SDK + LangChain 构建完整的 RAG 应用,包含企业知识库、法律文档检索等实际场景
本教程将带您了解如何使用 [xParse SDK](/xparse/v1/sdk-python) 和 LangChain 构建完整的 RAG(检索增强生成)应用。我们将通过三个实际场景,展示从文档解析到智能分块、向量化到检索的完整流程。
## 什么是 RAG?
RAG(Retrieval-Augmented Generation,检索增强生成)是一种结合信息检索和生成式 AI 的技术。通过 RAG,大模型可以基于企业知识库进行回答,而不是仅依赖训练数据,从而提供更准确、更相关的答案。
RAG 的核心流程包括:
1. **文档解析**:使用 [xParse SDK](/xparse/v1/sdk-python) 将非结构化文档转换为 Markdown 和结构化元素
2. **智能分块**:使用 LangChain 文本分割器对解析结果进行分块
3. **向量化存储**:使用 LangChain Embeddings 将分块向量化并存入向量数据库
4. **检索查询**:根据用户问题检索相关文档片段
5. **生成回答**:将检索到的内容作为上下文,让大模型生成答案
xParse SDK 负责高质量的文档解析,LangChain 负责后续的分块、向量化和检索,两者结合为您提供灵活的 RAG 构建能力。
## 环境准备
首先安装必要的依赖:
```bash theme={null}
python -m venv .venv && source .venv/bin/activate
pip install xparse-client langchain langchain-community langchain-core \
langchain-text-splitters langchain-milvus python-dotenv
```
创建 `.env` 文件存储配置:
```bash theme={null}
# .env
TEXTIN_APP_ID=your-app-id
TEXTIN_SECRET_CODE=your-secret-code
DASHSCOPE_API_KEY=your-dashscope-key
```
> 提示:`TEXTIN_APP_ID` 与 `TEXTIN_SECRET_CODE` 参考 [API Key](/xparse/api-key),请登录 [Textin 工作台](https://www.textin.com/console/dashboard/setting) 获取。示例中使用 `通义千问` 的大模型能力,其他模型用法类似。
下面我们将通过三个实际场景,展示如何构建 RAG 应用。
## RAG 完整流程
```
文档文件 (PDF/Word/Excel...)
↓
[xParse SDK 文档解析]
└─ client.parse.run() → Markdown + 结构化元素
↓
[LangChain 智能分块]
├─ MarkdownHeaderTextSplitter(按标题)
├─ RecursiveCharacterTextSplitter(按字符)
└─ 按页面分组(按元素 page_number)
↓
[LangChain 向量化 + 存储]
├─ DashScopeEmbeddings 向量化
└─ Milvus.from_documents() 存入向量数据库
↓
[检索系统]
├─ 用户问题 → 向量化
├─ 向量相似度检索
└─ 返回相关文档片段
↓
[大模型生成]
└─ 基于检索内容生成答案
```
## 场景 1:企业知识库构建
### 需求描述
某企业需要构建内部知识库,包含产品手册、技术文档、培训材料等。员工可以通过自然语言提问,快速找到相关信息。
**文档特点**:
* 格式多样:PDF、Word、Excel
* 结构清晰:有明确的章节标题
* 内容专业:技术术语较多
**处理要求**:
* 保持章节完整性
* 支持语义检索
* 快速响应查询
### 配置方案
针对结构化文档,我们使用 `MarkdownHeaderTextSplitter` 按标题分块,保持章节完整性:
```python theme={null}
from xparse_client import XParseClient
from langchain_text_splitters import MarkdownHeaderTextSplitter, RecursiveCharacterTextSplitter
from langchain_core.documents import Document
from langchain_community.embeddings import DashScopeEmbeddings
from langchain_milvus import Milvus
import os, glob
from dotenv import load_dotenv
load_dotenv()
client = XParseClient()
# 按标题分块配置
headers_to_split_on = [("#", "header1"), ("##", "header2"), ("###", "header3")]
markdown_splitter = MarkdownHeaderTextSplitter(headers_to_split_on=headers_to_split_on)
text_splitter = RecursiveCharacterTextSplitter(chunk_size=1536, chunk_overlap=100)
# 解析并分块
all_chunks = []
for file_path in glob.glob("./knowledge_base/*.pdf"):
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
md_docs = markdown_splitter.split_text(result.markdown)
for doc in md_docs:
doc.metadata["filename"] = os.path.basename(file_path)
chunks = text_splitter.split_documents(md_docs)
all_chunks.extend(chunks)
# 向量化并存入 Milvus
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="knowledge_base",
connection_args={"uri": "./kb_vectors.db"},
)
```
### 完整代码示例
```python theme={null}
#!/usr/bin/env python
# -*- coding: utf-8 -*-
"""
企业知识库构建示例
"""
from xparse_client import XParseClient
from langchain_text_splitters import MarkdownHeaderTextSplitter, RecursiveCharacterTextSplitter
from langchain_core.documents import Document
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
import os, glob
from dotenv import load_dotenv
load_dotenv()
def build_knowledge_base():
"""构建知识库"""
print("=" * 60)
print("开始构建企业知识库...")
print("=" * 60)
client = XParseClient()
headers_to_split_on = [("#", "header1"), ("##", "header2"), ("###", "header3")]
markdown_splitter = MarkdownHeaderTextSplitter(headers_to_split_on=headers_to_split_on)
text_splitter = RecursiveCharacterTextSplitter(chunk_size=1536, chunk_overlap=100)
all_chunks = []
for file_path in glob.glob("./knowledge_base/*.pdf"):
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
md_docs = markdown_splitter.split_text(result.markdown)
for doc in md_docs:
doc.metadata["filename"] = os.path.basename(file_path)
chunks = text_splitter.split_documents(md_docs)
all_chunks.extend(chunks)
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="knowledge_base",
connection_args={"uri": "./kb_vectors.db"},
)
print(f"\n共处理 {len(all_chunks)} 个文档片段")
print("\n" + "=" * 60)
print("知识库构建完成!")
print("=" * 60)
def query_knowledge_base(question: str, top_k: int = 5):
"""查询知识库"""
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus(
embedding_function=embedding,
collection_name="knowledge_base",
connection_args={"uri": "./kb_vectors.db"},
)
docs = vector_store.similarity_search(question, k=top_k)
print(f"\n问题: {question}")
print(f"\n找到 {len(docs)} 个相关文档片段:\n")
for i, doc in enumerate(docs, 1):
print(f"{i}. 文档: {doc.metadata.get('filename', 'N/A')}")
print(f" 内容: {doc.page_content[:200]}...")
print()
if __name__ == '__main__':
# 构建知识库
build_knowledge_base()
# 查询示例
query_knowledge_base("如何使用产品 API?")
```
## 场景 2:法律文档检索系统
### 需求描述
律师事务所需要构建法律文档检索系统,包含合同、判决书、法律条文等。律师可以通过关键词或自然语言快速检索相关案例和法律依据。
**文档特点**:
* 主要是 PDF 格式
* 页面结构清晰
* 需要保持页面完整性
* 跨页内容需要关联
**处理要求**:
* 按页面分块,保持页面完整性
* 支持精确检索
* 保留文档元数据(如案件编号、日期等)
### 配置方案
针对 PDF 文档,我们通过 xParse 解析出的元素按 `page_number` 分组,保持页面完整性:
```python theme={null}
from xparse_client import XParseClient
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_core.documents import Document
from langchain_community.embeddings import DashScopeEmbeddings
from langchain_milvus import Milvus
from collections import defaultdict
import os, glob
from dotenv import load_dotenv
load_dotenv()
client = XParseClient()
# 按页面分块
all_chunks = []
for file_path in glob.glob("./legal_documents/*.pdf"):
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
page_texts = defaultdict(list)
for el in result.elements:
page_texts[el.page_number].append(el.text)
page_docs = [
Document(
page_content="\n\n".join(texts),
metadata={"filename": os.path.basename(file_path), "page_number": pn}
)
for pn, texts in sorted(page_texts.items())
]
chunks = RecursiveCharacterTextSplitter(
chunk_size=2048, chunk_overlap=150
).split_documents(page_docs)
all_chunks.extend(chunks)
# 向量化并存入 Milvus
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="legal_documents",
connection_args={"uri": "./legal_vectors.db"},
)
```
### 完整代码示例
```python theme={null}
#!/usr/bin/env python
# -*- coding: utf-8 -*-
"""
法律文档检索系统示例
"""
from xparse_client import XParseClient
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_core.documents import Document
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
from collections import defaultdict
from typing import List, Dict
import os, glob
from dotenv import load_dotenv
load_dotenv()
def build_legal_document_index():
"""构建法律文档索引"""
print("=" * 60)
print("开始构建法律文档检索系统...")
print("=" * 60)
client = XParseClient()
all_chunks = []
for file_path in glob.glob("./legal_documents/*.pdf"):
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
page_texts = defaultdict(list)
for el in result.elements:
page_texts[el.page_number].append(el.text)
page_docs = [
Document(
page_content="\n\n".join(texts),
metadata={"filename": os.path.basename(file_path), "page_number": pn}
)
for pn, texts in sorted(page_texts.items())
]
chunks = RecursiveCharacterTextSplitter(
chunk_size=2048, chunk_overlap=150
).split_documents(page_docs)
all_chunks.extend(chunks)
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="legal_documents",
connection_args={"uri": "./legal_vectors.db"},
)
print(f"\n共处理 {len(all_chunks)} 个文档片段")
print("\n" + "=" * 60)
print("法律文档索引构建完成!")
print("=" * 60)
def search_legal_documents(query: str, case_type: str = None, top_k: int = 10) -> List[Dict]:
"""检索法律文档"""
embedding = DashScopeEmbeddings(model="text-embedding-v4")
vector_store = Milvus(
embedding_function=embedding,
collection_name="legal_documents",
connection_args={"uri": "./legal_vectors.db"},
)
docs = vector_store.similarity_search(query, k=top_k)
results = []
for doc in docs:
results.append({
'content': doc.page_content,
'metadata': doc.metadata
})
return results
def format_search_results(results: List[Dict]) -> str:
"""格式化检索结果"""
output = []
for i, result in enumerate(results, 1):
metadata = result.get('metadata', {})
output.append(f"{i}. 文档: {metadata.get('filename', 'N/A')}")
output.append(f" 页码: {metadata.get('page_number', 'N/A')}")
output.append(f" 内容: {result.get('content', '')[:300]}...")
output.append("")
return "\n".join(output)
if __name__ == '__main__':
# 构建索引
build_legal_document_index()
# 检索示例
query = "合同违约责任"
results = search_legal_documents(query, top_k=5)
print(f"\n查询: {query}")
print("\n检索结果:")
print(format_search_results(results))
```
## 场景 3:技术文档问答系统
### 需求描述
技术团队需要构建 API 文档问答系统,开发者可以通过自然语言提问,快速找到 API 使用方法、参数说明等。
**文档特点**:
* 主要是 Markdown 和 PDF 格式
* 代码示例较多
* 结构相对简单
* 需要精确匹配 API 名称
**处理要求**:
* 基础分块即可
* 支持代码块识别
* 快速检索响应
### 配置方案
针对技术文档,我们使用 `RecursiveCharacterTextSplitter` 进行基础分块,简单高效:
```python theme={null}
from xparse_client import XParseClient
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_core.documents import Document
from langchain_community.embeddings import DashScopeEmbeddings
from langchain_milvus import Milvus
import os, glob
from dotenv import load_dotenv
load_dotenv()
client = XParseClient()
# 基础分块
all_chunks = []
for file_path in glob.glob("./api_docs/*.pdf"):
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
doc = Document(
page_content=result.markdown,
metadata={"filename": os.path.basename(file_path)}
)
chunks = RecursiveCharacterTextSplitter(
chunk_size=1024, chunk_overlap=50
).split_documents([doc])
all_chunks.extend(chunks)
# 向量化并存入 Milvus
embedding = DashScopeEmbeddings(model="text-embedding-v3")
vector_store = Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name="api_documentation",
connection_args={"uri": "./api_docs.db"},
)
```
### 完整代码示例(集成大模型)
```python theme={null}
#!/usr/bin/env python
# -*- coding: utf-8 -*-
"""
技术文档问答系统示例(集成大模型)
"""
from xparse_client import XParseClient
from langchain_text_splitters import RecursiveCharacterTextSplitter
from langchain_core.documents import Document
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
from langchain_community.chat_models import ChatTongyi
from langchain_core.messages import HumanMessage
from typing import List, Dict
import os, glob
from dotenv import load_dotenv
load_dotenv()
class APIDocQASystem:
"""API 文档问答系统"""
def __init__(self, milvus_path: str, collection_name: str):
self.milvus_path = milvus_path
self.collection_name = collection_name
self.embedding = DashScopeEmbeddings(model="text-embedding-v3")
self.vector_store = Milvus(
embedding_function=self.embedding,
collection_name=collection_name,
connection_args={"uri": milvus_path},
)
self.llm = ChatTongyi(
model="qwen-max",
dashscope_api_key=os.getenv("DASHSCOPE_API_KEY")
)
def build_index(self):
"""构建文档索引"""
client = XParseClient()
all_chunks = []
for file_path in glob.glob("./api_docs/*.pdf"):
with open(file_path, "rb") as f:
result = client.parse.run(file=f, filename=os.path.basename(file_path))
doc = Document(
page_content=result.markdown,
metadata={"filename": os.path.basename(file_path)}
)
chunks = RecursiveCharacterTextSplitter(
chunk_size=1024, chunk_overlap=50
).split_documents([doc])
all_chunks.extend(chunks)
embedding = DashScopeEmbeddings(model="text-embedding-v3")
self.vector_store = Milvus.from_documents(
documents=all_chunks,
embedding=embedding,
collection_name=self.collection_name,
connection_args={"uri": self.milvus_path},
)
print("文档索引构建完成!")
def retrieve(self, query: str, top_k: int = 3) -> List[Dict]:
"""检索相关文档"""
docs = self.vector_store.similarity_search(query, k=top_k)
results = []
for doc in docs:
results.append({
'content': doc.page_content,
'metadata': doc.metadata
})
return results
def answer(self, question: str) -> str:
"""基于检索结果生成答案"""
results = self.retrieve(question, top_k=3)
context = "\n\n".join([
f"文档片段 {i+1}:\n{result['content']}"
for i, result in enumerate(results)
])
prompt = f"""基于以下文档内容回答用户问题。
文档内容:
{context}
用户问题:{question}
请基于文档内容回答问题,如果文档中没有相关信息,请说明。"""
response = self.llm.invoke([HumanMessage(content=prompt)])
return response.content
def main():
qa_system = APIDocQASystem(
milvus_path='./api_docs.db',
collection_name='api_documentation'
)
# 构建索引(首次运行)
# qa_system.build_index()
# 问答示例
questions = [
"如何使用用户认证 API?",
"API 的 rate limit 是多少?",
"如何上传文件?"
]
for question in questions:
print(f"\n问题: {question}")
answer = qa_system.answer(question)
print(f"回答: {answer}")
if __name__ == '__main__':
main()
```
## 与向量数据库集成
### Milvus 使用说明
Milvus 是一个开源的向量数据库,通过 LangChain 可以方便地将 xParse 解析的文档存入 Milvus 并进行向量检索:
```python theme={null}
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
import os
from dotenv import load_dotenv
load_dotenv()
embedding = DashScopeEmbeddings(model="text-embedding-v4")
# 连接 Milvus 向量存储
vector_store = Milvus(
embedding_function=embedding,
collection_name="documents",
connection_args={"uri": "./vectors.db"},
)
# 语义检索
docs = vector_store.similarity_search("用户认证", k=5)
for doc in docs:
print(f"文档: {doc.metadata.get('filename', 'N/A')}")
print(f"内容: {doc.page_content[:100]}...")
print()
```
### Zilliz 使用说明
Zilliz 是 Milvus 的云端托管版本,使用 LangChain 集成方式类似:
```python theme={null}
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
embedding = DashScopeEmbeddings(model="text-embedding-v4")
# 连接 Zilliz 向量存储
vector_store = Milvus(
embedding_function=embedding,
collection_name="documents",
connection_args={
"uri": "https://xxxxxxx.serverless.xxxxxxx.cloud.zilliz.com.cn",
"token": "your-api-key"
},
)
# 语义检索
docs = vector_store.similarity_search("用户认证", k=5)
```
## 检索和查询最佳实践
### 1. 使用 LangChain 进行检索
使用 LangChain 的向量存储可以自动处理查询向量化,无需手动调用 embed API:
```python theme={null}
from langchain_milvus import Milvus
from langchain_community.embeddings import DashScopeEmbeddings
import os
from dotenv import load_dotenv
load_dotenv()
embedding = DashScopeEmbeddings(model="text-embedding-v4")
# 连接向量存储
vector_store = Milvus(
embedding_function=embedding,
collection_name="documents",
connection_args={"uri": "./vectors.db"},
)
# 直接使用自然语言查询,无需手动向量化
docs = vector_store.similarity_search("用户认证", k=5)
```
### 2. 相似度阈值
使用 LangChain 的 `similarity_search_with_score` 可以获取相似度分数:
```python theme={null}
def search_with_threshold(query: str, threshold: float = 0.7, top_k: int = 10):
"""带阈值的检索"""
# 获取带分数的检索结果
docs_with_scores = vector_store.similarity_search_with_score(query, k=top_k)
# 过滤低相似度结果
# 注意:LangChain 返回的分数是距离(越小越相似),需要转换为相似度
filtered = [
(doc, score) for doc, score in docs_with_scores
if (1 - score) >= threshold # COSINE 距离转换为相似度
]
return filtered
```
### 3. 混合检索
结合向量检索和关键词检索:
```python theme={null}
def hybrid_search(query: str, vector_store, milvus_path, top_k: int = 5):
"""混合检索:向量 + 关键词"""
from pymilvus import MilvusClient
from langchain_core.documents import Document
# 向量检索
vector_docs = vector_store.similarity_search(query, k=top_k)
collection_name = vector_store.collection_name
# 关键词检索(使用 Milvus 的查询功能)
keyword_results = []
try:
client = MilvusClient(uri=milvus_path)
collections = client.list_collections()
if collection_name not in collections:
print(f"Collection '{collection_name}' 不存在,跳过关键词检索")
return vector_docs
keywords = query.split()
if not keywords:
return vector_docs
expr_parts = []
for keyword in keywords:
escaped_keyword = keyword.replace("'", "''").replace("%", "\\%").replace("_", "\\_")
expr_parts.append(f"text like '%{escaped_keyword}%'")
expr = " or ".join(expr_parts)
keyword_data = client.query(
collection_name=collection_name,
filter=expr,
limit=top_k,
output_fields=["text", "metadata"]
)
for item in keyword_data:
doc = Document(
page_content=item.get("text", ""),
metadata=item.get("metadata", {}) if isinstance(item.get("metadata"), dict) else {}
)
keyword_results.append(doc)
except Exception as e:
print(f"关键词检索失败: {e}")
keyword_results = []
# 合并结果(去重)
all_docs = {}
for doc in vector_docs:
doc_id = doc.page_content[:100]
all_docs[doc_id] = doc
for doc in keyword_results:
doc_id = doc.page_content[:100]
if doc_id not in all_docs:
all_docs[doc_id] = doc
return list(all_docs.values())
```
## 性能优化建议
1. **批量处理**:使用 xParse SDK 批量解析多个文档,配合 LangChain 批量分块和向量化
2. **分块策略优化**:根据文档类型选择合适的 LangChain 分割器,减少不必要的分块
3. **向量模型选择**:平衡精度和速度,生产环境可考虑使用 `text-embedding-v3`
4. **索引优化**:在 Milvus 中创建合适的索引,提升检索速度
## 下一步
* **查看[快速启动指南](/xparse/v1/quickstart)**:了解 xParse SDK 的基本使用方法
* **阅读[API 文档](/api-reference/endpoint/xparse/v1/parse-sync)**:了解详细的接口参数和配置选项
* **探索更多场景**:根据您的业务需求,灵活组合 xParse SDK 和 LangChain 能力
如果您在构建 RAG 应用时遇到问题,可以参考这些示例代码,或联系技术支持获取帮助。
# 项目列表
Source: https://docs.textin.com/xparse/v1/tutorials/sample-projects
基于 xParse 的结构化抽取开源示例项目集合,每个项目独立可运行,覆盖银行流水、发票、医疗报告、合同审查、招标文件、财务报表等场景。
所有示例项目均为前后端完整的独立应用,克隆仓库后填入 API 凭证即可一键启动。
源码仓库:[intsig-textin/xparse-sample-projects](https://github.com/intsig-textin/xparse-sample-projects)
## 项目总览
支持 PDF/图片,分批抽取交易明细,含余额连续性校验与 JSON/CSV 导出。
支持 PDF/Word/图片,自动分类、抽取头部字段与明细行,含规则校验。
支持扫描件与图片,抽取患者信息、诊断、检查指标、治疗与预后。
条款风险审阅、规范审阅、主体识别,支持导出 Word 报告。
按 6 大模块并发抽取基础信息、资格要求、评审要求等结构化字段。
基于规则提取资产负债表、利润表、现金流量表,无需大模型。
## 银行流水抽取
面向财务审计、贷款审批、个人记账等场景。上传银行流水 PDF 或图片,OCR 解析完成后立即展示结果页,用户手动点击「AI 抽取」触发结构化提取。长流水表格自动按行数分批并发送给 LLM,各批结果流式追加到交易明细表。提取完成后进行余额连续性校验,支持导出 JSON 和 CSV。
**技术栈**:Python + FastAPI / React + Vite / TextIn 文档解析 / OpenAI 兼容接口
```bash theme={null}
# 后端
cd bank-statement-extract/backend
cp ../.env.example ../.env # 填入凭证
pip install -r requirements.txt && python main.py
# 前端
cd bank-statement-extract/frontend
npm install && npm run dev # http://localhost:5173
```
## 海外发票抽取
面向跨境业务场景的发票结构化抽取工具。支持 PDF/Word/图片上传,自动分类发票类型,抽取头部字段、明细行,并进行金额一致性等规则校验。
**技术栈**:Python + FastAPI / React + TypeScript + Vite / TextIn 文档解析 / OpenAI 兼容接口
```bash theme={null}
# 后端
cd invoice-extract/backend
cp ../.env.example ../.env # 填入凭证
pip install -r requirements.txt && python main.py
# 前端
cd invoice-extract/frontend
npm install && npm run dev # http://localhost:5173
```
## 医疗报告抽取
面向医疗文档结构化场景。支持检验单、影像报告、出院小结等多种文档类型,针对扫描件和拍照件做了优化处理,抽取患者信息、诊断、检查指标、治疗与预后建议。
**技术栈**:Python + FastAPI / React + Vite / TextIn 文档解析 / OpenAI 兼容接口
```bash theme={null}
# 后端
cd medical-report-extract/backend
cp ../.env.example ../.env # 填入凭证
pip install -r requirements.txt && python main.py
# 前端
cd medical-report-extract/frontend
npm install && npm run dev # http://localhost:5173
```
## 合同审查
面向合同初审场景。解析合同正文后并行执行条款风险审阅(责任、违约、知识产权、保密、争议解决)和规范审阅(错漏、一致性、格式、修订),自动识别甲乙方主体,支持导出 Word 审查报告。
**技术栈**:Python + FastAPI / React + Vite / TextIn 文档解析 / OpenAI 兼容接口
```bash theme={null}
# 后端
cd contract-review/backend
cp ../.env.example ../.env # 填入凭证
pip install -r requirements.txt && python main.py
# 前端
cd contract-review/frontend
npm install && npm run dev # http://localhost:5173
```
## 招标文件解析
面向招采场景。将招标文件按标题切块并路由到 6 个模块(基础信息、资格要求、评审要求、投标要求、无效标风险、附件材料),各模块并发抽取,输出结构化 JSON,支持导出汇总结果。
**技术栈**:Python + FastAPI / React + TypeScript + Vite / TextIn 文档解析 / OpenAI 兼容接口
```bash theme={null}
# 后端
cd tender-doc-parse/backend
cp ../.env.example ../.env # 填入凭证
pip install -r requirements.txt && python main.py
# 前端
cd tender-doc-parse/frontend
npm install && npm run dev # http://localhost:5173
```
## 财务三大表抽取
面向财务分析、投研辅助场景。基于 TextIn 返回的结构化 `detail` 字段,通过规则自动定位并提取资产负债表、利润表、现金流量表,前端自动计算同比趋势,支持 CSV 导出。**无需大模型。**
**技术栈**:Python + FastAPI / React + TypeScript + Create React App / TextIn 文档解析
```bash theme={null}
# 后端(仅需 TextIn 凭证,无需大模型配置)
cd financial-report-extract/backend
cp ../.env.example ../.env # 填入 TEXTIN_APP_ID 和 TEXTIN_SECRET_CODE
pip install -r requirements.txt && python main.py
# 前端
cd financial-report-extract/frontend
npm install && npm start # http://localhost:3000
```
## 获取 API 凭证
访问 [TextIn 开放平台](https://www.textin.com) 注册并获取 `App ID` 与 `Secret Code`,详见 [API Key 说明](/xparse/api-key)。